In January 2025, Aditi Singh and coauthors revealed a survey titled Agentic Retrieval-Augmented Era: A Survey on Agentic RAG, revised in April 2026. They describe agentic retrieval augmented technology, or agentic RAG, as a search system with an AI agent inside it. The agent can plan its subsequent step, test its personal outcomes, and use different packages, resembling a calculator or a search field, whereas it seems for info. The identical survey lists analysis and effectivity among the many open challenges. That’s the half I wished to measure.
Retrieval augmented technology, or RAG, implies that a language mannequin, an AI system that writes textual content, solutions a query utilizing textual content it first retrieved from a set of paperwork. RAG with plain search seems the query up as soon as, as written. Agentic RAG provides an agent. A language mannequin reads the primary outcomes and decides whether or not to cease or to jot down a brand new search.
Extra searches seem like they need to discover higher proof, which means the paper that truly solutions the query. Every additional search additionally wants one other language mannequin name, and whoever runs the system pays for it. Each additionally makes the consumer wait longer and offers the agent one other likelihood to jot down a worse search than the one it began with.
So I ran one take a look at. I designed it and used an AI coding assistant, Claude Code, a software that writes and runs code from directions, to construct and run it. I attempted 4 methods of looking out, with the identical 298 questions over the identical 2,000 latest arXiv papers. The 4 methods have been these.
-
Plain search seems the query up as soon as, as written.
-
A reranker makes the identical search, then makes use of a small scoring mannequin to reorder the primary 50 outcomes.
-
A query rewriter asks a language mannequin to rewrite the query 3 ways, searches with all 4 variations, and merges the outcomes.
-
An agent makes a search, then lets a language mannequin learn the primary outcomes. The mannequin decides whether or not to cease or to jot down a brand new search, as much as three searches in all.
All 4 are methods of doing the primary half of RAG. RAG has two halves. The primary half retrieves textual content that’s related to the query. The second half offers that textual content to a language mannequin, which writes the reply. I examined solely the primary half, so none of those 4 writes a solution.
Right here is how every one suits. Plain search is the retrieval half of peculiar RAG in its easiest kind. The reranker is identical, with a standard additional step that reorders the outcomes. The query rewriter is the retrieval half of RAG with query rewriting, one other widespread method, and it follows the identical mounted steps each time. Solely the agent is agentic, as a result of it reads the outcomes and chooses whether or not to cease or to go looking once more.
For every means, I counted how usually it put the correct paper among the many first 5 outcomes it returned, its high 5. The query rewriter and the agent use a language mannequin, so they don’t return precisely the identical reply twice. I ran every of them 3 times.
What the run confirmed
-
The agent put the correct paper within the high 5 for 96.87 p.c of questions, in opposition to 95.64 p.c for plain search. That hole is +1.2 proportion factors, and the vary of believable values runs from -0.8 to +3.5. A variety that features zero means this take a look at can not inform the 2 aside.
-
Plain search left the correct paper out of its high 5 on 13 questions. The agent discovered the correct paper for 7 to eight of them in every run, and misplaced 3 to five papers that plain search had discovered.
-
A reranker reorders the primary 50 outcomes with a second mannequin and desires no language mannequin name. It put the correct paper greater within the record by a transparent margin, with a rating of 0.959 in opposition to 0.895 on the rank measure defined beneath. It value nothing in mannequin charges.
-
Rewriting the query into three variants and merging the outcomes did worse than plain search, at 93.6 in opposition to 95.6 p.c, although that hole additionally sits inside its vary.
The quick reply to the title is that, on this take a look at, giving the agent extra searches didn’t clearly discover higher proof. It discovered some papers plain search missed and misplaced some plain search had discovered, and the achieve it left was too small to inform from likelihood. The one clear enchancment got here from the reranker, an affordable step that reordered the primary 50 outcomes and moved the correct paper greater.
All the things beneath reveals how I acquired there, what I modified alongside the best way, and the place the outcome stops being dependable.
How must you take a look at whether or not a search agent finds higher proof?
I wanted to measure the looking out alone, so the standard of a ultimate written reply couldn’t disguise it. The take a look at due to this fact stops one step earlier than the reply. For every query, there’s precisely one paper whose summary, its quick abstract, solutions it. A means of looking out succeeds if that paper seems within the first 5 outcomes. From right here on I name every means of looking out a design.
Listed below are the 4 designs, named dense, rerank, multiquery, and agent. The primary one, dense, is the plain search and the baseline, which is the model the others are in contrast with. Every of the others provides one factor. The one which rewrites the query first is multiquery, and the one that may search once more is agent.
Dense is the plain search and the baseline. It turns the query into an embedding, which is an inventory of numbers that represents what the textual content means. Each summary has its personal embedding too, made beforehand by the identical mannequin. The search returns the abstracts whose numbers sit closest to the query’s, very like discovering the closest factors on a map.
It makes one search and calls no language mannequin. I used the embedding mannequin BAAI/bge-small-en-v1.5, which is launched underneath the MIT license.
Rerank is identical search with one additional step. The dense search first returns its high 50 abstracts. A second mannequin, referred to as a cross encoder, then reads the query and every summary collectively and offers every pair a rating for the way effectively they match. The 50 are reordered by that rating, so the summary that matches greatest strikes to the highest.
It reads every pair in full, so it runs solely on the 50 and never on all 2,000 abstracts. I used cross-encoder/ms-marco-MiniLM-L-6-v2, launched underneath Apache 2.0. It’s a small scoring mannequin that by no means writes textual content.
Multiquery is the search with rewriting. Claude Haiku 5.5, a small and quick mannequin from Anthropic, writes three totally different variations of the query. The system searches with the unique and the three variations, which provides 4 ranked lists. It merges the 4 lists into one with reciprocal rank fusion, or RRF.
RRF offers every paper 1 divided by (60 plus its place) for each record it seems in, and provides the scores up. A paper in place 1 of an inventory earns 1/61, and a paper in place 10 earns 1/70. A paper that sits excessive in a number of lists due to this fact finally ends up on high. Cormack, Clarke, and Büttcher launched it in 2009 and glued the fixed at 60.
Agent is the search that may attempt once more. The primary search makes use of the query as written. Claude Haiku 5.5 then sees the titles of the highest 5 outcomes and replies both “cease” or with a brand new question, which is the phrases to seek for. It may search at most 3 times. The lists from all its searches are merged with the identical RRF setting, so it ends with one ranked record just like the others.
A librarian is a good image of the agent. Ask a plain query and a plain search returns what sits nearest on the shelf. A librarian who rephrases it, maybe utilizing the phrases researchers in that space truly use, could discover the correct e book. The identical librarian may guess phrases from the improper space and stroll away from the correct shelf. Which of these occurs extra usually is what I measured.
One equity level issues right here. The agent and multiquery search greater than as soon as, and dense searches as soon as. The outcomes desk beneath prints the typical variety of searches subsequent to each design, so extra looking out is seen and never hidden.
What precisely have been the questions and the papers?
The take a look at is barely pretty much as good as its questions and its assortment, so right here is how I constructed each, and what I checked.
The place did the papers come from?
I collected 2,000 papers from arXiv, the open server the place researchers put up papers earlier than peer assessment. They arrive from 4 classes. cs.AI is for synthetic intelligence, cs.CL for computation and language, cs.IR for info retrieval, and cs.LG for machine studying.
The papers have been submitted on 92 totally different days between 1 July and 30 September 2026. I selected that window as a result of Anthropic’s mannequin overview lists a June 2026 coaching knowledge cutoff for the fashions I used. That’s the final date their coaching knowledge covers, so the papers shouldn’t be in it. The title and summary of every paper are the one textual content any design may see.
arXiv’s phrases of use for its programming interface permit its descriptive metadata for use underneath the Inventive Commons CC0 1.0 public area declaration. The phrases describe descriptive metadata as together with fields resembling title, summary, authors, identifiers, and classification phrases. That covers the titles and abstracts I used. The papers’ full texts carry their authors’ personal licenses, and I didn’t use them.
How have been the questions written?
Earlier than working any search, I picked 300 papers at random to jot down questions on. I name them supply papers. For every one, Claude Sonnet 5.5 learn the title and summary and wrote one query that the paper solutions. The directions informed it by no means to repeat the title or a stretch of 4 or extra phrases from it.
The questions rotate by three kinds. A particular query names the strategy or setting in Claude Sonnet 5.5’s personal phrases. A downside query describes the issue with out naming the strategy. A obscure query is brief and imprecise, like one thing half remembered.
The desk reveals three of the 298 questions, one among every type. Every is the primary of its type in my record, so I picked them by a hard and fast rule and never as a result of they seemed good. For every one, it offers the paper the query was written from and the place that paper got here in when plain search ran, the place 1 means first. All 298 questions are within the repository.
|
Type |
Query |
Paper it was written from |
Plain search rank |
|---|---|---|---|
|
particular |
How can I take advantage of answer prefixes or different privileged hints throughout RL coaching to offer a studying sign on issues the place a language mannequin by no means samples an accurate reply, whereas nonetheless optimizing the target for the unique unhinted immediate? |
Off-Context GRPO: Studying to Motive on Onerous Issues utilizing Privileged Data |
5 |
|
downside |
How can we make research measuring whether or not AI help meaningfully helps non-experts plan chemical, organic, radiological, or nuclear assaults comparable throughout analysis efforts, given inconsistent definitions of who counts as a non-expert, differing risk scopes, baselines, scoring rubrics, and determination guidelines? |
A Threshold Exceedance Framework for CBRN Uplift Analysis in Frontier Language Fashions |
8 |
|
obscure |
paper that scores clusterings in opposition to identified lessons with two separate measures, one for the way pure clusters are and one for avoiding over-splitting, and hyperlinks it to ROC curves |
Exterior Clustering Validation by the Homogeneity-Parsimony Commerce-off |
1 |
I set the principles, and Claude Sonnet 5.5 wrote every query from a paper’s summary. Every query was then checked in opposition to that summary, because the part on checking beneath describes. The questions listed here are lengthy and detailed. Even the one labeled obscure is 28 phrases and names particular concepts, resembling “two separate measures” and “ROC curves”. An individual typing right into a search field may write just a few phrases, resembling “clustering analysis ROC”, which provides a search a lot much less to work with.
What are the lookalike papers?
In a small trial run first, which I name the pilot and describe beneath, plain search was too good, so I added a tougher situation. For every supply paper, I put its 5 most related papers into the gathering, measured by shared phrases (time period frequency inverse doc frequency, or TF IDF). I used shared phrases and never the embedding mannequin, so the lookalike papers weren’t chosen by the identical mannequin that does the looking out.
These neighbors are solely loosely related. The median high neighbor had a similarity of 0.15 on a scale the place 1 means an identical. Which means the neighbors share some matter phrases however are removed from copies. This take a look at is due to this fact tougher than a random assortment and nonetheless resembles peculiar lookalike papers on the identical matter.
How have been the questions checked?
A query might be unfair if the summary doesn’t truly reply it, or if one other paper solutions it simply as effectively. The coding assistant first learn each query in opposition to its supply summary and the three nearest different papers and marked every one go or fail. I then spot checked 30 of the passes in opposition to their abstracts and located no unsupported solutions. That test covers 30 questions, and the opposite 268 relaxation on the assistant’s go alone.
Two questions failed as a result of they requested for a outcome the summary doesn’t report, which left 298. For instance, one requested how a lot labeled knowledge is required, which the summary by no means states. Their IDs are q064 and q088 within the repository.
What did the pilot change?
I ran a small pilot first, as a result of a take a look at is ineffective if the plain search already will get every little thing proper. The pilot used 300 papers and 20 questions, of which 17 handed assessment.
Plain search put the correct paper at rank 1, which is first place, for all 17 of them. No design may have seemed higher, so the pilot couldn’t separate something. That’s the reason I added the lookalike papers and grew the gathering to 2,000.
The pilot additionally uncovered a mistake in my first agent. It merged its searches by protecting every paper’s greatest uncooked similarity rating. On one pilot query, a rewritten question pushed the correct paper from rank 1 all the way down to rank 4. The reason being {that a} rating of 0.8 for one question doesn’t imply the identical as 0.8 for one more. I modified the agent to merge by place with RRF, the identical setting multiquery makes use of.
I didn’t tune the fixed of 60, and I didn’t attempt different values.
Right here is every little thing that modified alongside the best way, and what triggered every change.
-
The gathering grew and gained lookalike papers, as a result of the pilot was too simple.
-
The agent’s merge modified from greatest rating to RRF, due to the pilot query above.
-
Three questions modified after assessment and earlier than any search that calls a language mannequin ran. Two repeated 4 or extra phrases of their paper’s title, so I regenerated them. One query’s supply paper had additionally been a pilot supply, so I changed it with one other paper.
-
5 questions initially got here again with out a query as a result of Claude Sonnet 5.5 replied with plain textual content, not the format I anticipated. I accepted the plain textual content, so all 300 acquired a query.
After I noticed the plain search and reranker outcomes, I learn once more all 13 questions that plain search missed, together with the papers it returned as an alternative. I modified no query, and I eliminated none due to a outcome. I additionally didn’t drop the questions that plain search already ranked first. Eradicating them would have meant selecting the take a look at after seeing the reply.
How do I rating a design, and the way a lot ought to I belief a quantity?
Two measures carry the outcomes, and each are greater when the design is best.
Recall at 5 (recall@5) is the share of questions the place the correct paper seems within the high 5. Whether it is 95 p.c, then for 95 of 100 questions a reader 5 outcomes would see the correct paper.
Imply reciprocal rank at 10 (MRR@10) rewards placing the correct paper first. A paper at rank 1 scores 1, rank 2 scores one half, rank 5 scores one fifth, and a paper outdoors the highest 10 scores 0. The rating is the typical over questions.
A single common hides how a lot it may transfer with a special set of questions. So I report a spread for every distinction. Think about drawing 298 questions from the pile time and again, placing every one again after it’s drawn, and recomputing the distinction every time. I did that 2,000 occasions and took the center 95 p.c of the outcomes. It is a bootstrap vary, and it reveals how a lot the reply strikes when the set of questions modifications.
The distinction is paired, which means every design is in contrast with plain search on the identical questions. When a spread contains zero, the info are appropriate with no actual distinction.
The 2 designs that decision a language mannequin, multiquery and agent, ran 3 times every. Dense and rerank return the identical outcome each time, in order that they ran as soon as. Claude Haiku 5.5 doesn’t let me set the temperature. That setting is the management that makes a mannequin repeat itself kind of precisely, so its replies differ somewhat from run to run.
I turned off its considering possibility, the place the mannequin causes at size earlier than it solutions. That means the reported value and the delay, which is the time from the query to the ranked record, mirror the retrieval design alone, with no hidden reasoning added. Claude Sonnet 5.5, which wrote the questions, doesn’t permit considering to be turned off, so I used its lowest considering setting as an alternative.
What did the 4 designs rating?
The desk beneath solutions the query the entire take a look at was constructed for, which is whether or not extra looking out finds the correct paper extra usually. The multiquery and agent rows present the imply over three runs, and the brackets present the bottom and highest run. Variations on this article are computed from the unrounded values, so a niche can differ by 0.1 from subtracting the rounded numbers proven.
|
Design |
Proper paper in high 5 (p.c) |
MRR@10 |
Searches per query |
Median delay (seconds) |
Mannequin value per 1,000 queries |
|---|---|---|---|---|---|
|
dense |
95.6 |
0.895 |
1.0 |
0.01 |
$0 |
|
rerank |
97.0 |
0.959 |
1.0 |
1.46 |
$0 |
|
multiquery |
93.6 [93.0 to 94.3] |
0.868 [0.866 to 0.871] |
4.0 |
1.37 |
$0.06 |
|
agent |
96.9 [96.6 to 97.0] |
0.906 [0.902 to 0.909] |
1.7 |
1.40 |
$0.09 |
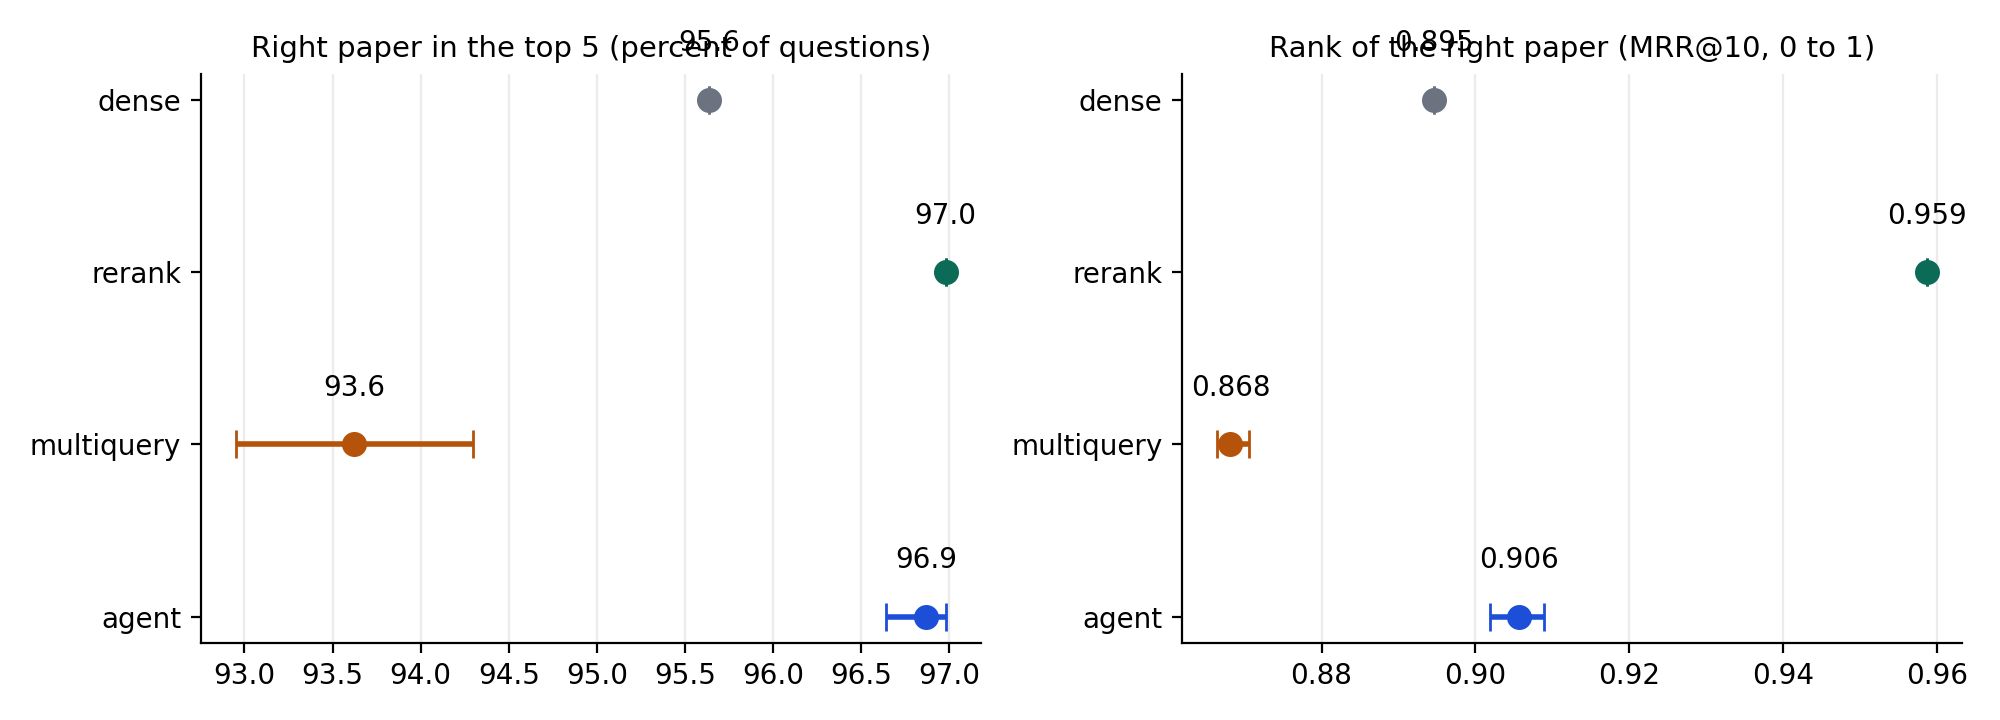
Picture by writer. Every dot is one design’s rating on the 298 questions, which have been mounted earlier than the multiquery and agent runs, from the saved outcome information. Larger is best on each charts, and the quick traces mark the bottom and highest of three runs for multiquery and agent. The reranker and the agent sit above plain search on each measures, and multiquery sits beneath.
Plain search already finds the correct paper in 95.6 p.c of questions, and it ranks it first for 253 of 298. That leaves 13 questions the place an additional search may assist. Recall can rise by at most 13 of 298 questions, which is 4.4 factors, so no design can achieve greater than that on recall. I come again to this underneath the boundaries.
Which variations are actual?
This part issues as a result of the next quantity within the desk doesn’t imply a greater design. The chart reveals every design’s change from plain search, with its vary.
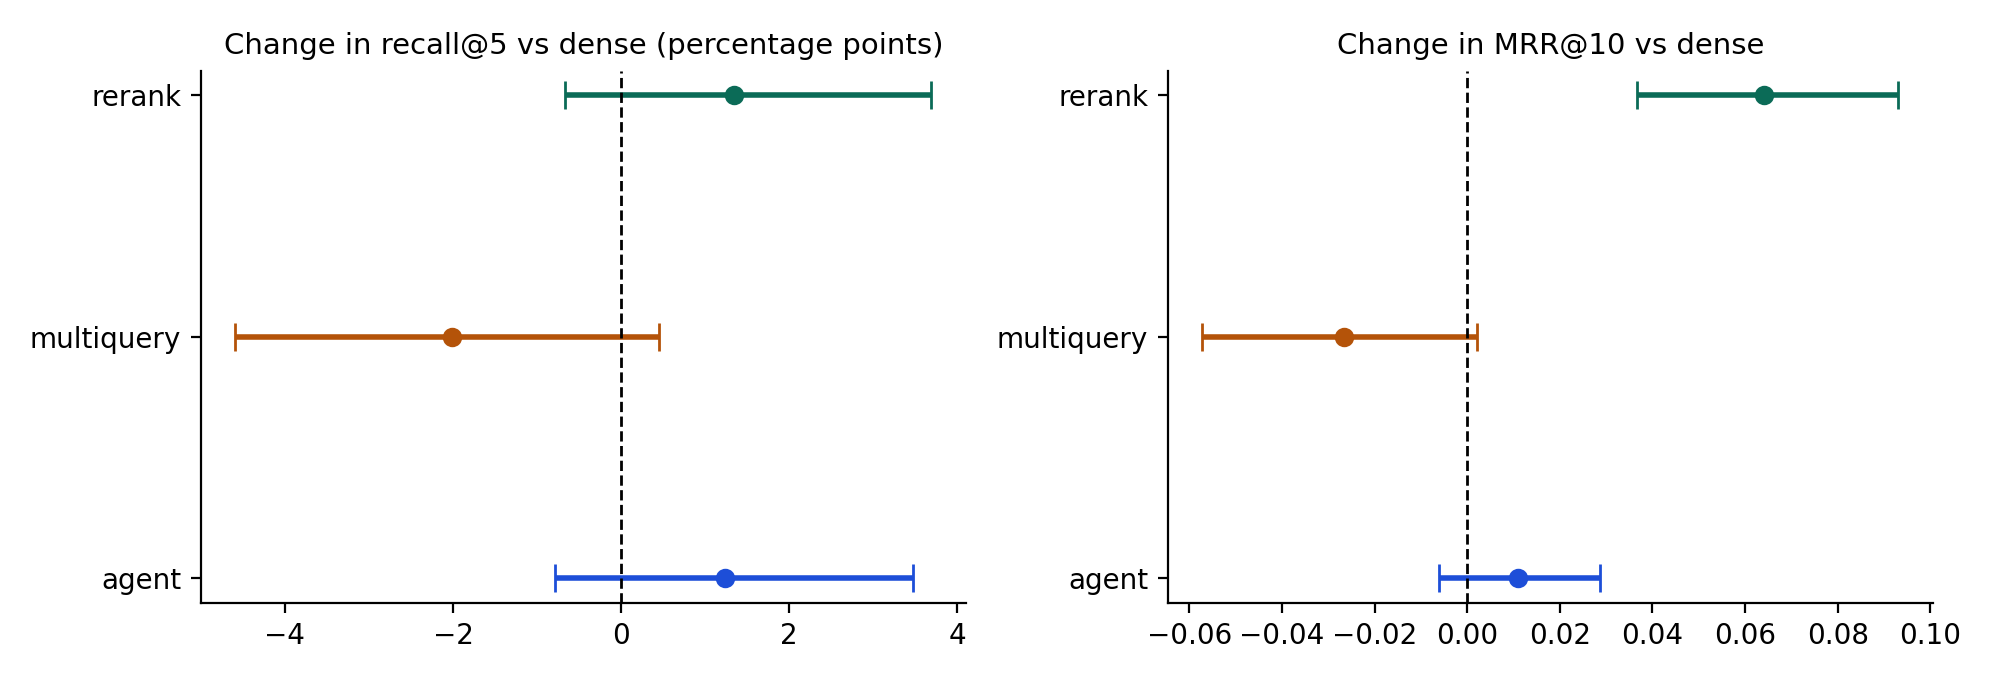
Picture by writer. Every dot is the typical change from plain search over the three runs, on the identical questions, and every line is the 95 p.c bootstrap vary. A line that crosses the dashed zero line means the take a look at can not separate that design from plain search. Solely the reranker’s achieve in MRR@10 clears zero.
-
The reranker gained +1.3 factors on recall@5 (vary -0.7 to +3.7), which incorporates zero. On rank high quality, which is MRR@10, it gained +0.064 (vary +0.037 to +0.093), which clears zero. It’s the solely clear enchancment within the take a look at. It strikes the correct paper greater, and that prices one additional scoring go and no mannequin charges. It additionally provides about 1.5 seconds of delay on my laptop computer.
-
The agent gained +1.2 factors on recall (vary -0.8 to +3.5). On rank high quality it gained +0.011 (vary -0.006 to +0.029). Each ranges embrace zero. The sincere studying is that the agent could also be somewhat higher, could also be no totally different, and could also be barely worse, and this take a look at can not say which.
-
Multiquery modified recall by -2.0 factors (vary -4.6 to +0.4), and on rank high quality by -0.026 (vary -0.057 to +0.002). Each ranges embrace zero, however in each run it misplaced 11 to 13 of the 285 papers plain search had discovered, which additionally suggests it’s worse.
The three runs differ by 0.3 factors for agent and 1.3 factors for multiquery on recall. Each are smaller than the 4 to five factors of width within the ranges above. That width comes from having 298 questions, so repeating the runs extra wouldn’t change the image. Extra questions would.
The place did the agent assist, and the place did it damage?
The averages disguise what truly occurred contained in the searches, so this part seems at particular questions. I saved each question the agent wrote, and the queries quoted beneath are precisely because it wrote them, together with the technical shorthand.
The place did the agent assist?
The agent turned plain wording into the phrases researchers in that space truly use. One query requested the right way to ship incoming requests, in actual time, to a number of servers that generate textual content, every with restricted capability, whereas balancing response time in opposition to whole output. Plain search didn’t return the correct paper in its high 10. The agent’s second question was SLO-aware request routing throughout decode replicas with KV cache capability constraints optimization, and the correct paper moved to rank 1 in all three runs.
One other query requested for a technique to make a byte pair encoding vocabulary extra environment friendly by hiding not often used intermediate items. That vocabulary is the record of phrase items a mannequin reads textual content in. Plain search put the correct paper at rank 6. The agent rewrote it as BPE vocabulary pruning eradicating unused merge tokens reallocating vocabulary slots, and the paper moved to rank 1 or 2.
The place did the agent damage?
The agent additionally added phrases that weren’t within the query, guessed from its reminiscence of the sector. One query requested for a language mannequin design that feeds its personal final inside state again in as its subsequent enter. Plain search ranked the correct paper first. The agent’s second question added the phrases “steady thought,” and its third added the identify “Coconut,” which the query by no means used.
The outcomes for these queries have been different papers about fashions that cause in inside numbers and never in phrases, and so they have been merged above the correct paper. It slipped from rank 1 to rank 5 and rank 4 in two runs, which continues to be inside the highest 5. Within the third run it fell out of the highest 10, and that’s the solely run the place it counts as misplaced.
One other query requested the right way to take a look at whether or not the interior reminiscence of a discovered reinforcement studying replace rule helps or hurts. Plain search had the paper at rank 5. The agent’s third question added “LSTM” and “discovered optimizer.” These are phrases from different analysis areas, and the query by no means used them. The paper ended outdoors the highest 5 in all three runs.
That is my studying of the 16 questions the place the outcome modified, not a measured impact. Rewrites that borrowed phrases from the query’s personal analysis space helped. Rewrites that guessed phrases from the agent’s reminiscence of the world usually named one thing else. The merge then positioned these different papers above a paper plain search had already discovered.
Solely 2 questions have been misplaced in all three runs. The opposite 6 have been misplaced in simply one of many three runs, which is peculiar variation between runs. That’s 12 losses in whole, cut up 4, 3, and 5 throughout the three runs.
How usually did the agent search?
The agent stopped after one search on about 59 p.c of questions, after a single mannequin name to resolve. It used all three searches on about 26 p.c. On 7 to eight questions per run it used all three and nonetheless missed. 5 questions have been by no means discovered by plain search or by any agent run.
What does this not present?
A outcome with out its limits is straightforward to overread, so listed here are the boundaries, within the order I’d fear about them.
There may be little room to enhance. Plain search is true on 285 of 298 questions, so solely 13 questions can present a achieve on recall. The ranges above attain about 2 to three factors on both aspect of every estimate, so a smaller actual achieve wouldn’t present. A tougher assortment, or many extra questions, could be wanted to detect a small actual profit.
It’s one assortment and one form of query. The papers are latest AI preprints from one quarter, and a mannequin wrote every query from the summary. Questions written from an summary share its wording, which helps any search that matches phrases. Each query right here has between 14 and 54 phrases, with a median of 32. An actual consumer’s questions could be messier and could also be a lot shorter, which provides a search much less to work with. I make no declare about enterprise paperwork, different languages, or longer texts.
The agent is one mannequin with one set of directions. I wrote the agent’s directions as soon as and didn’t tune them. A stronger mannequin, higher directions, or a special merge may change the end in both route.
The assessment coated solely a part of the questions. The coding assistant did the primary go over all 300 questions, and I checked 30 of them. Some unfair questions could stay. The questions plain search misses are those that matter most right here, and I learn these 13 once more by hand.
There are just a few smaller points. One alternative query has no lookalike papers planted subsequent to it and could also be simpler. Of the pilot’s supply papers, 12 additionally seem within the full assortment, so the pilot and the total run overlap. The take a look at additionally measures retrieval solely, so it says nothing about whether or not the ultimate written reply is best.
What would I do with this?
The discovering is “no clear enchancment on this assortment, at the price of additional mannequin calls and delay”. That’s the helpful outcome, as a result of it tells you the place to not spend first.
In case you run a RAG system, depend first. Take just a few hundred actual questions, run plain search, and see what number of it misses. If it misses only a few, an agent has little to repair. Plain search missed 13 of my 298 questions.
Add a reranker earlier than you add an agent. It was the one change right here with a transparent achieve, and it wants no language mannequin calls, although it provides about 1.5 seconds of delay on my laptop computer. Then, for those who add an agent, learn the queries it writes. Cap the variety of searches, merge by place and never by uncooked rating, and watch for brand spanking new phrases that weren’t within the consumer’s query. Within the examples I learn, these added phrases have been the place papers have been misplaced.
I left one query open. The reranker gave the clearer achieve at no cost. What must be true of your questions for an agent’s additional searches to be value their delay and their failures?
Are you able to run the take a look at your self?
The code, the saved outcome information, and the query set are within the companion repository on GitHub. All the things beneath runs from the highest folder of that repository in a terminal. I ran it with Python 3.9.
Setup installs 4 packages and desires an Anthropic API key. The secret is utilized by Claude Sonnet 5.5, which wrote the questions, and by Claude Haiku 5.5, which runs the query rewriter and the agent. Plain search and the reranker want no key and ran on my laptop computer.
These instructions use the saved papers and my reviewed query file, so that you rating precisely the 298 questions on this article. To construct a brand new assortment and query set, run MODE=full python collect_papers.py and MODE=full python make_questions.py first, then mark every query 1 or 0 within the okay (1/0) column of data_full/questions_review.csv, as a result of solely questions marked 1 are scored. A brand new set will differ from mine. The repository already incorporates my saved outcomes, and run_eval.py skips rows it already has, so delete outcomes/full.jsonl first if you would like the instructions above to recompute them.
Two items of code carry the principle thought. The primary is the merge step.
The second is the agent loop. It makes the primary search with the query as written and reveals the mannequin the highest 5 titles. The mannequin then both stops or writes a brand new question, as much as the search restrict.
The costs I used are record costs copied from the supplier’s pricing web page on 15 October 2026. Claude Sonnet 5.5 value about $0.60 for writing all questions, retries, and fixes. The three runs of multiquery and agent value $0.14 collectively, and the pilot value underneath $0.05. The entire venture value underneath $0.80.
Chosen sources
[1] A. Singh, A. Ehtesham, S. Kumar, T. Talaei Khoei, A. V. Vasilakos, Agentic Retrieval-Augmented Era: A Survey on Agentic RAG (2025, revised 2026), arXiv. Supply for the definition of agentic RAG and the open challenges named within the opening.
[2] G. V. Cormack, C. L. A. Clarke, S. Büttcher, Reciprocal rank fusion outperforms Condorcet and particular person rank studying strategies (2009), Proceedings of the thirty second Worldwide ACM SIGIR Convention on Analysis and Improvement in Data Retrieval. Supply for the merge technique and its fixed of 60.
[3] S. Xiao, Z. Liu, P. Zhang, N. Muennighoff, C-Pack: Packaged Sources To Advance Basic Chinese language Embedding (2023), arXiv, and the mannequin card for BAAI/bge-small-en-v1.5, launched underneath the MIT license. The embedding mannequin utilized by each design.
[4] cross-encoder/ms-marco-MiniLM-L-6-v2, Hugging Face mannequin card, launched underneath Apache 2.0. The reranking mannequin.
[5] arXiv, Phrases of use for arXiv APIs. The phrases permit descriptive metadata, together with title and summary, for use underneath CC0 1.0, and ask for no a couple of request each three seconds. Used for the titles and abstracts within the assortment.
[6] Anthropic, Fashions overview and considering documentation. Supply for the June 2026 coaching knowledge cutoff, the costs, and the considering and temperature settings of Claude Sonnet 5.5 and Claude Haiku 5.5.
[7] agentic-rag-evidence-test, GitHub repository for this text (2026). The code, the 298 reviewed questions, and the saved outcomes for each run on this article.