Most launch charts I’ve seen present the brand new mannequin successful every thing, which is why the Gemini 4 Argon chart caught my consideration. It wins lots and loses in a couple of locations that matter so much to anybody who spends their day in a terminal, and I belief that form of chart extra.
I’ve a behavior with launch posts that I’m not particularly pleased with. I skip the headline quantity and hunt for the row the place the mannequin loses, as a result of that row often decides whether or not I’m truly going to make use of it or not. A mannequin will get picked for the one irritating form of work that fills somebody’s week, and the common of forty benchmarks says little or no about how that work will go.
With Argon, the story is on the backside of the desk, and it’s the cause this text exists. The identical mannequin that takes first place on repository-level software program engineering sits nicely behind on terminal work, and additionally it is a mannequin the place one careless API name can run to $10 or $20. That form of unevenness tells me greater than a clear sweep would.
The remainder of this piece follows that thread via the API, the pricing, the benchmarks and the case research, and the 2 code samples embody the guards I truly need in a script.
What shipped and the place you may attain it
Google introduced Argon on September 30, 2026, and for the primary two weeks solely vetted safety defenders may use it, via the Fairwind Program, together with early testers comparable to Wiz. It reached builders on October 13 via the paid tier of the Gemini API and AI Studio, with Antigravity out there to Google AI Extremely subscribers. The mannequin ID is gemini-4-argon, and a second one, gemini-4-argon-cyber-permissive, is aimed toward licensed defenders, so most readers can ignore it.
It’s a sparse mixture-of-experts transformer with a March 2026 cutoff. Textual content, code, photographs, audio, video, and PDFs go in, and solely textual content and code come out, so Argon can not draw you a diagram, which I discover mildly humorous given the following part.
One pool of one million tokens
The change that pursuits me most is the output window. Older Gemini fashions took roughly one million tokens in and gave at most 64K again. Argon raises the output restrict to 1M tokens, and the lengthy decode docs describe a unified window of 1,048,576 tokens shared throughout enter, considering, and output, so a 100K immediate leaves room for nearly 950K of reply.
The default output cap stays at 65,536 tokens, principally so no one wakes as much as a shock bill. To go previous it you elevate max_output_tokens (as much as 1,048,576 minus your enter) and use lengthy decode.
On the Interactions API which means background=True, and Google’s servers chain the 64K hops into one interplay for you, whereas on the GenerateContent API you deal with the continuation your self. Ask for greater than the pool and also you get an HTTP 400.
So why do you have to care? An enormous era used to imply chopping the job into chunks, feeding every consequence again in, and hoping the mannequin nonetheless remembered what it had promised in chunk one. That workflow was by no means enjoyable, and lengthy decode is a good cause to retire it.
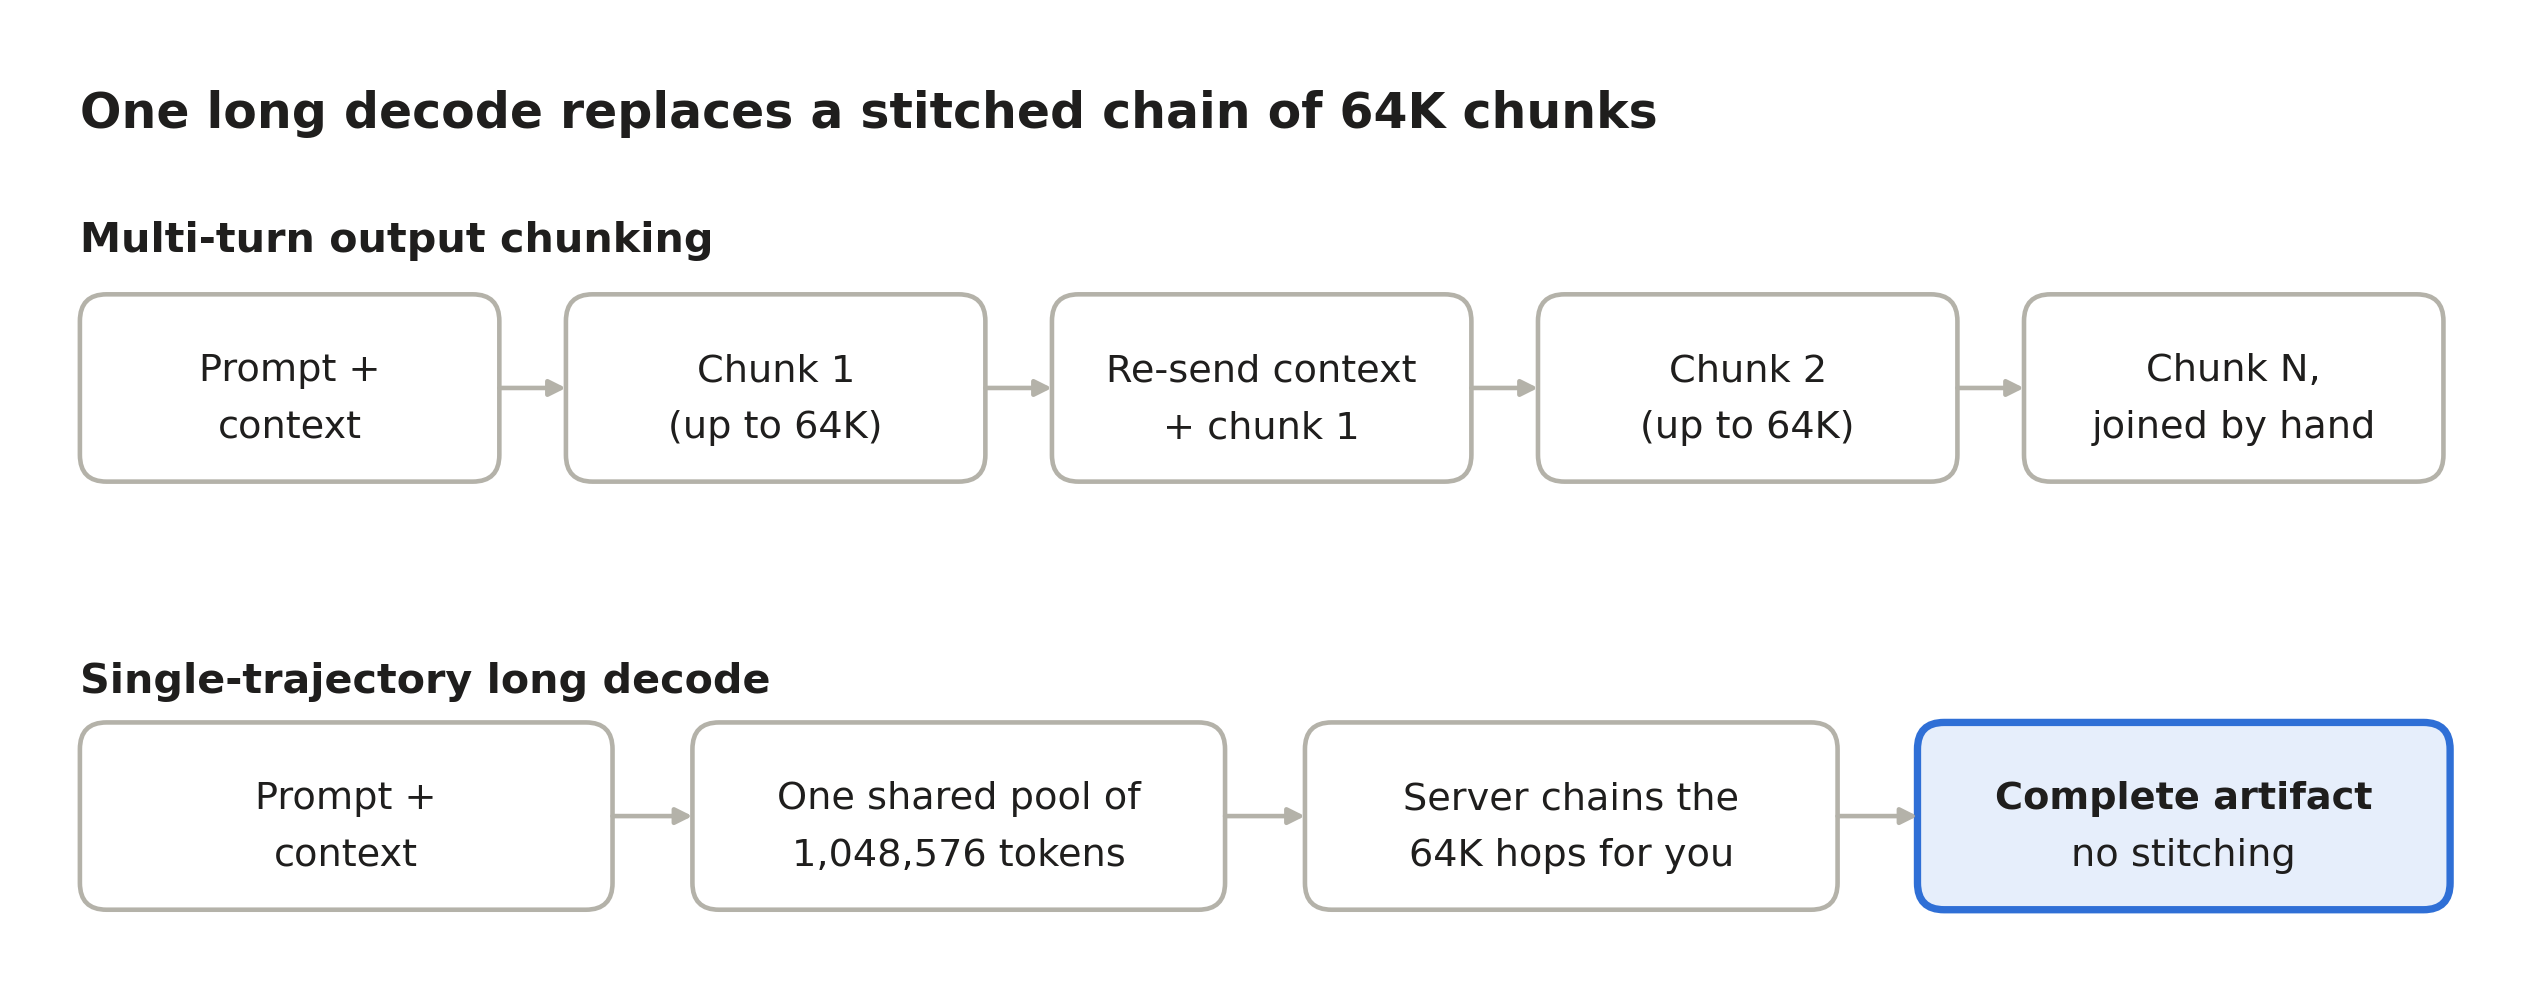
The highest lane resends a rising context on each flip and leaves the stitching to you, whereas the underside lane lets the server chain the hops inside one shared pool.
One caveat from the identical docs is that lengthy decode can run for a number of minutes, so it belongs in background jobs.
Considering ranges and one breaking change
thinking_level takes three values, "LOW", "MEDIUM" and "HIGH". Low is for classification, summarizing, and pulling out metadata, medium (the default) covers on a regular basis coding, software use, doc Q&A and video, and excessive is for multi-file engineering, proofs, structure work and vulnerability looking.
The one to observe for if you’re migrating is that the outdated integer thinking_budget and the MINIMAL setting now return an HTTP 400, so grep for these two earlier than the rest. Caching modified as nicely, since Argon solely does implicit caching, with a 95 p.c low cost on cached enter, and the express caching endpoints are gone.
Right here is the usual name within the type value preserving in a script. It validates the extent up entrance, as a result of a nasty worth solely fails after the request has gone out, and it logs token counts on the finish, since output tokens embody considering tokens and that’s the quantity on the bill.
The long-decode model wants extra care. It clamps the output cap towards the true immediate dimension, since asking for greater than the pool minus the immediate is a assured HTTP 400, and it refuses to begin when the worst-case invoice is above a restrict you set. That examine is a little bit of belt and braces, however a refused run prices nothing.
The worst-case estimate makes use of the introductory value, in order that fixed has to vary on December 1. The loop additionally retains every thing in reminiscence, which is ok for a couple of hundred thousand tokens, however write every delta to disk if dropping the connection would damage.
Pricing and the verbosity catch
Introductory pricing (as of mid-October 2026) is $2.00 per million enter tokens and $10.00 per million output tokens, with considering billed as output and cached enter 95 p.c off. The window closes on November 30, and from December 1 the usual costs of $4.00 and $20.00 apply.
On the introductory fee, that places Argon stage with Claude Sonnet 5.5, at half the value of Claude Opus 5.5, and much beneath GPT-6 Astra at $10 and $50.
Then comes the catch. Synthetic Evaluation discovered that Argon used 110M tokens on its analysis suite towards a discipline median of 82M, so it talks greater than its rivals.
It nonetheless got here out cheaper per job, at $1.99 towards $3.26 for GPT-6 Astra and $5.98 for Claude Opus 5.5, so the financial savings are actual however smaller than the speed card suggests. And one unconstrained 1M-token reply prices $10 at intro pricing or $20 at normal pricing, in a single name.
The place Argon wins and the place it trails
Do not forget that row I talked about at the start? I went searching for it. On Terminal-Bench 4.0 Argon scores 57.4 p.c whereas Claude Opus reaches 66.4 and Sonnet 70.6, and on FrontierSWE v2 it will get 55.0 towards 65.5 for GPT-6 Astra.
It additionally trails on OSWorld 2.0 and on Brokers’ Final Examination (39.5 towards 59.3), and the blended Synthetic Evaluation Index places it at 52.6, about stage with GPT-6 Astra and 5 factors behind Opus 5.5. In case your day is generally an agent reacting step-by-step to a shell or a desktop, these are the numbers that matter, and they aren’t flattering.
The wins come from a distinct form of work. Argon takes first place on DeepSWE v1.1 at 77.9 p.c, leads the Vals Index general, and posts 84.2 p.c on GraphWalks BFS within the 256K to 1M vary towards 71.8 for GPT-6 Astra and 66.8 for Opus 5.5. It additionally leads LVBench for lengthy video at 91.7 p.c.
Every of those rewards holding a big construction in your head without delay, which a shared million-token pool is constructed for, so my learn is that Argon fits an enormous downside you may hand over and stroll away from, and will get much less fascinating when you need to steer it step-by-step.
What Google says Argon has accomplished up to now
The case research present what that headroom is for. Google says Argon brokers are migrating C and C++ to Rust at sizes from re2 as much as greater than 800,000 strains within the Fuchsia Zircon kernel.
Within the libgav1 video decoder they changed 32,000 strains of SIMD with protected Rust that the compiler vectorizes by itself, giving a decoder that runs 2.7 instances sooner than the earlier Rust port with an identical output, which is the consequence value waiting for an out of doors copy.
A staff of brokers studying fleet profiling information is anticipated to free 500 TiB to 1 PiB of reminiscence throughout Google’s information facilities, and Wiz used the mannequin to discover a vital vulnerability in hospital software program that earlier frontier fashions had missed.
All of those are Google’s personal numbers, so deal with them as robust alerts till somebody outdoors the corporate reproduces a couple of of them.
···
Must you change?
So do you have to change? In all probability not totally. Ship Argon the work with an enormous form, comparable to repository-scale refactors, lengthy paperwork, authorized and monetary evaluation, and video overview, and preserve interactive terminal brokers on Sonnet or Opus, the place they at present lead.
Route by workload, set max_output_tokens on objective, and do not forget that the pricing window closes on November 30 and the verbosity will present up in your bill nicely earlier than the benchmarks do.
···
Earlier than you go!
I write about AI and ML engineering, and about what new mannequin releases imply for the individuals who should construct with them. You’ll be able to subscribe to my publication if you want extra of that.
Join With Me