Anthropic launched Claude Haiku 5.5 on October 7, 2026, and calls it its most cost-effective, quickest, and most succesful small mannequin. The API mannequin ID is claude-haiku-5-5, and prompts as much as 100,000 tokens value $0.10 per million enter tokens and $0.50 per million output tokens. This text covers what modified since Haiku 4.5, the way to construct quick, low-cost AI workflows with it in Python (classification, extraction, and sub-agents), and when an even bigger Claude mannequin remains to be the higher decide.
Haiku 5.5
Anthropic positions Haiku 5.5 for high-volume, cost-sensitive work resembling summaries, compaction, database queries, and classification, and as a subagent alongside Opus 5.5 and Sonnet 5.5. It’s obtainable on the Claude Platform, Amazon Internet Companies, Google Cloud, and Microsoft Azure. Its security evaluations are documented within the system card. Anthropic’s deprecation web page lists the earliest retirement date as October 7, 2027.
What’s New In contrast With Haiku 4.5?
| Function | Haiku 4.5 | Haiku 5.5 |
|---|---|---|
| Context window | 200K tokens | 1M tokens |
| Max output | 64K tokens | 128K tokens |
| Pondering management | Handbook pondering finances | Adaptive pondering with an effort setting, a primary for a Haiku |
| Value per million tokens, prompts as much as 100K (enter / output) | $1.00 / $5.00 | $0.10 / $0.50 |
| Value over 100K | $1.00 / $5.00 | $0.50 / $2.50 |
| Smallest cacheable immediate | 4,096 tokens | 512 tokens |
| GDPval-AA (information work) | 735 | 1620 |
| OSWorld 2.1, offline subset (pc use) | 15.7% | 72.4% |
| Humanity’s Final Examination, no instruments | 10.2% | 45.9% |
| Terminal-Bench 4.0 (agentic coding) | 0.0% | 39.2% |
The benchmark rows are Anthropic’s personal outcomes, and the launch web page reveals Sonnet 5.5 forward on all 4 (for instance, 70.6% on Terminal-Bench 4.0). The worth reduce can be smaller in observe than the record costs recommend. Haiku 5.5 makes use of a more recent tokenizer, so the identical textual content counts as roughly 30% extra tokens. Anthropic places the common saving at round 75%, after accounting for the tokenizer and for the ten% of requests that run over 100K tokens.
Three modifications can break present Haiku 4.5 code. The what’s-new web page lists them as breaking: sending temperature, top_p, or top_k returns an error, ending the messages with an assistant prefill returns an error, and guide pondering with budget_tokens returns an error. Two conduct modifications matter as properly. Adaptive pondering is on by default, so a response can begin with a pondering block, and pondering tokens rely towards max_tokens. Security classifiers also can decline a request, so your code should deal with stop_reason: "refusal". On security, Anthropic says Haiku 5.5’s cybersecurity safeguards are stricter than Haiku 4.5’s and block penetration testing.
Utilizing Haiku 5.5 for Quick, Low-cost Workflows
You want Python 3.10 or newer, an API key from the Claude Console, and a current Anthropic SDK, because the code under makes use of the newer output_config parameter.
pip set up -U anthropic
export ANTHROPIC_API_KEY="your-key-here"
The primary command installs or upgrades the official Python SDK. The second shops your key within the shell session, and the SDK reads ANTHROPIC_API_KEY routinely. On Home windows PowerShell, use $env:ANTHROPIC_API_KEY="your-key-here".
Step 1: Classification and Extraction
These are the 2 jobs Haiku was constructed for: a brief enter and a brief, structured reply, repeated 1000’s of occasions. The code makes use of JSON outputs, which constrain the reply to a schema you present. It additionally holds the shared worth desk and a price helper that the following two scripts reuse.
# haiku_tasks.py
"""Quick, low-cost Claude Haiku 5.5 calls: classification and extraction with JSON outputs."""
import json

import anthropic

MODEL = "claude-haiku-5-5"
shopper = anthropic.Anthropic()    # reads ANTHROPIC_API_KEY from the setting

# USD per million tokens (enter, output) for prompts as much as 100K tokens.
PRICES = {
    "claude-haiku-5-5": (0.10, 0.50),
    "claude-sonnet-5-5": (2.00, 10.00),
    "claude-opus-5-5": (4.00, 20.00),
}

CATEGORY_SCHEMA = {
    "kind": "object",
    "properties": {"class": {"kind": "string", "enum": ["billing", "shipping", "technical", "other"]}},
    "required": ["category"],
    "additionalProperties": False,
}

INVOICE_SCHEMA = {
    "kind": "object",
    "properties": {
        "vendor": {"kind": "string"},
        "invoice_number": {"kind": "string"},
        "whole": {"kind": "quantity"},
        "forex": {"kind": "string"},
        "due_date": {"kind": "string", "description": "ISO date, YYYY-MM-DD"},
    },
    "required": ["vendor", "invoice_number", "total", "currency", "due_date"],
    "additionalProperties": False,
}


def cost_usd(mannequin, utilization):
    price_in, price_out = PRICES[model]
    return (utilization.input_tokens * price_in + utilization.output_tokens * price_out) / 1_000_000


def ask_json(schema, instruction, textual content, mannequin=MODEL, effort="low"):
    """One request whose reply have to be JSON matching `schema`. Returns (information, utilization)."""
    reply = shopper.messages.create(
        mannequin=mannequin,
        max_tokens=1000,    # pondering tokens rely towards this restrict, so go away headroom
        system=instruction,
        messages=[{"role": "user", "content": text}],
        output_config={"effort": effort, "format": {"kind": "json_schema", "schema": schema}},
    )
    if reply.stop_reason in ("refusal", "max_tokens"):
        elevate RuntimeError(f"No usable reply, cease motive: {reply.stop_reason}")
    # A reply can begin with a pondering block, so decide the textual content block by kind.
    reply = "".be part of(block.textual content for block in reply.content material if block.kind == "textual content")
    return json.masses(reply), reply.utilization


def classify(textual content, mannequin=MODEL):
    information, utilization = ask_json(CATEGORY_SCHEMA, "Classify the client message.", textual content, mannequin)
    return information["category"], utilization


def extract_invoice(textual content, mannequin=MODEL):
    information, utilization = ask_json(INVOICE_SCHEMA, "Extract the bill fields from the textual content.", textual content, mannequin)
    return information, utilization


if __name__ == "__main__":
    for message in ["I was charged twice this month.", "My parcel never arrived.", "The app crashes on login."]:
        class, utilization = classify(message)
        print(f"{class:<10} {utilization.input_tokens} in / {utilization.output_tokens} out  <- {message}")

    bill = "Acme Cloud Ltd, bill AC-2291. Whole due: 1,240.50 USD by 15 November 2026."
    fields, utilization = extract_invoice(bill)
    print(fields, f"(${cost_usd(MODEL, utilization):.6f})")
PRICES lists enter and output costs per million tokens for the three fashions (from Anthropic’s launch web page and pricing web page), and cost_usd turns a response’s token counts into {dollars}. The 2 schemas describe the output you need: CATEGORY_SCHEMA limits class to 4 allowed values, and INVOICE_SCHEMA lists 5 fields.
ask_json is the core perform. It sends one request with the schema inside output_config.format, and effort set to low, so the mannequin spends little time pondering on a simple process. Anthropic’s JSON outputs assure legitimate JSON that matches the schema. Discover what’s lacking: there is no such thing as a temperature, as a result of Haiku 5.5 rejects it. max_tokens is 1000 although solutions are tiny, since pondering tokens rely in opposition to it. Two checks comply with. A cease motive of refusal or max_tokens raises an error as a substitute of failing silently on a half-empty reply. Then the textual content is learn by block kind, as a result of a reply could start with a pondering block, and parsed as JSON.
I used JSON outputs as a substitute of forcing a instrument name on objective. Haiku 5.5 accepts a pressured instrument name, however Opus 5.5 rejects one with a 400 error, so JSON outputs are the transportable selection for the three-model comparability in Step 3. One caveat: JSON outputs are not obtainable on Amazon Bedrock for Haiku 5.5, so on Bedrock you describe the format within the immediate and validate the consequence your self. Run it:
python haiku_tasks.pyThe __main__ block classifies three messages and extracts fields from one bill, printing the tokens used and the price of the extraction. Anticipate one class per message and a dictionary with 5 fields.
Step 2: Sub-Brokers
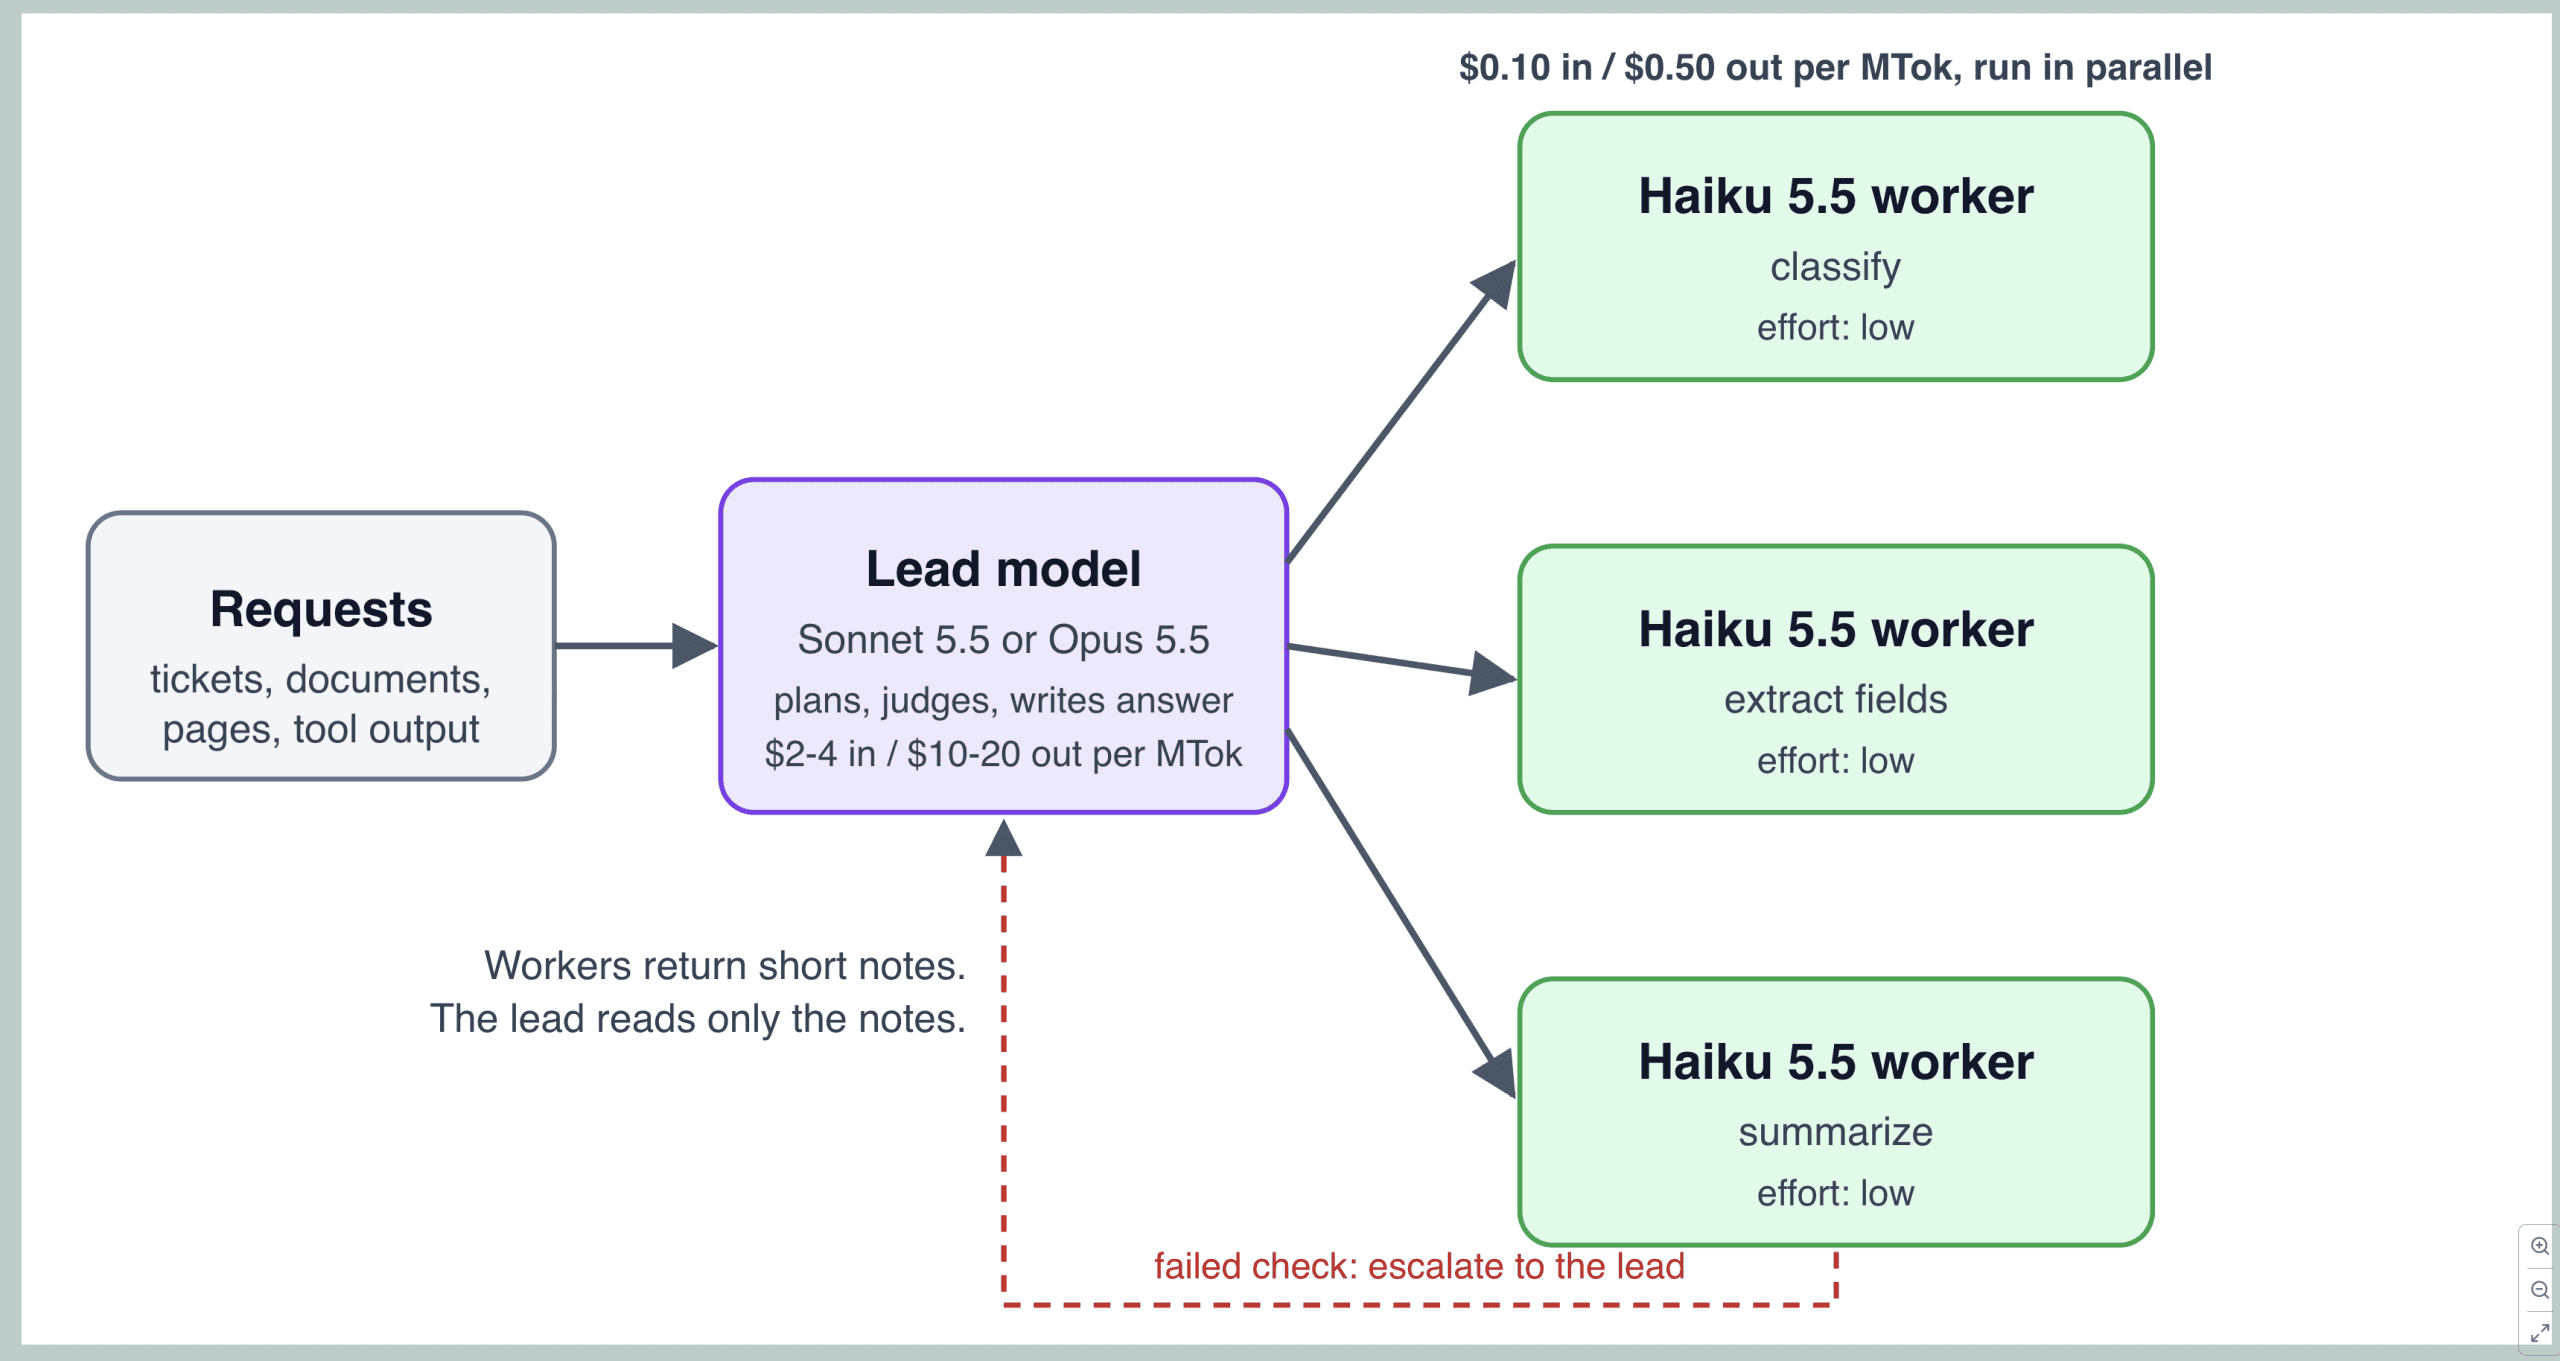
A sub-agent setup splits the work. A bigger mannequin decides what to do and writes the ultimate reply, whereas many Haiku staff deal with the slender, repetitive jobs in parallel. That is the sample Anthropic names for Haiku, and Cognition experiences utilizing Haiku 5.5 because the sidekick in Devin Fusion with Opus 5.5 because the lead.
# subagents.py
"""A lead mannequin delegates slender jobs to parallel Haiku 5.5 staff, then writes the reply."""
import asyncio

import anthropic

from haiku_tasks import MODEL as WORKER, cost_usd

LEAD = "claude-sonnet-5-5"
shopper = anthropic.AsyncAnthropic()


def text_of(reply):
    return "".be part of(block.textual content for block in reply.content material if block.kind == "textual content")


async def summarize(title, doc, restrict):
    async with restrict:    # cap what number of staff run without delay
        reply = await shopper.messages.create(
            mannequin=WORKER,
            max_tokens=1500,
            system="Summarize the doc in two sentences. Maintain names, dates and quantities actual.",
            messages=[{"role": "user", "content": document}],
            output_config={"effort": "low"},
        )
    return title, text_of(reply), cost_usd(WORKER, reply.utilization)


async def reply(paperwork, query):
    restrict = asyncio.Semaphore(8)
    notes = await asyncio.collect(*(summarize(n, d, restrict) for n, d in paperwork.gadgets()))
    worker_cost = sum(value for _, _, value in notes)

    transient = "n".be part of(f"[{name}] {abstract}" for title, abstract, _ in notes)
    reply = await shopper.messages.create(
        mannequin=LEAD,
        max_tokens=2000,
        system="You're the lead analyst. Reply utilizing solely the employee notes.",
        messages=[{"role": "user", "content": f"Question: {question}nnWorker notes:n{brief}"}],
        output_config={"effort": "medium"},
    )
    return text_of(reply), worker_cost, cost_usd(LEAD, reply.utilization)


if __name__ == "__main__":
    paperwork = {
        "contract-a": "Northwind renewed its help contract on 3 March 2026 for 48,000 USD per 12 months.",
        "contract-b": "Contoso signed a 12-month license on 9 Could 2026. The charge is 15,500 USD, billed quarterly.",
        "contract-c": "Fabrikam's settlement ends on 30 June 2026 and renews provided that both social gathering offers discover.",
    }
    textual content, worker_cost, lead_cost = asyncio.run(reply(paperwork, "Which agreements want motion earlier than July 2026?"))
    print(textual content)
    print(f"staff: ${worker_cost:.6f}  lead: ${lead_cost:.6f}")
summarize is one employee. It asks Haiku for a two-sentence abstract at low effort and returns the doc title, the abstract, and the price. The Semaphore caps what number of staff run on the identical time, which retains you inside your charge limits. reply begins each employee without delay with asyncio.collect, provides up the employee value, after which sends solely the brief summaries to the lead mannequin — right here Sonnet 5.5 at its default effort. The lead by no means reads the complete paperwork, and that’s the place the financial savings come from. The perform returns the reply plus each prices, so you’ll be able to see the place the cash went.
Step 3: Evaluating Value and Latency
Printed numbers solely go to date, so this script runs the identical classification process on all three fashions and measures accuracy, latency, and value by yourself account.
# compare_models.py
"""Run the identical classification process on three fashions and evaluate accuracy, latency and value."""
import statistics
import time

from haiku_tasks import classify, cost_usd

MODELS = ["claude-haiku-5-5", "claude-sonnet-5-5", "claude-opus-5-5"]

TICKETS = [
    ("I was charged twice for my last order.", "billing"),
    ("Please send me a copy of my invoice.", "billing"),
    ("Where is my package? It was due on Monday.", "shipping"),
    ("My order was delivered to the wrong building.", "shipping"),
    ("The app crashes every time I open settings.", "technical"),
    ("I cannot log in even after resetting my password.", "technical"),
    ("Can you tell me about your company history?", "other"),
    ("My card was declined but the money left my account.", "billing"),
]


def run(mannequin):
    seconds, value, hits, output_tokens = [], 0.0, 0, 0
    for textual content, label in TICKETS:
        begin = time.perf_counter()
        class, utilization = classify(textual content, mannequin)
        seconds.append(time.perf_counter() - begin)
        hits += class == label
        value += cost_usd(mannequin, utilization)
        output_tokens += utilization.output_tokens
    n = len(TICKETS)
    return hits / n, statistics.median(seconds), value / n * 1000, output_tokens / n


if __name__ == "__main__":
    print(f"{'mannequin':<20}{'accuracy':>9}{'median s':>10}{'$/1k calls':>12}{'out tok':>9}")
    for mannequin in MODELS:
        attempt:
            accuracy, median_s, per_thousand, out_tokens = run(mannequin)
        besides Exception as error:    # for instance, a mannequin or platform that rejects the request
            print(f"{mannequin:<20} failed: {error}")
            proceed
        print(f"{mannequin:<20}{accuracy:>9.0%}{median_s:>10.2f}{per_thousand:>12.3f}{out_tokens:>9.0f}")
run sends every of the eight take a look at messages by classify with a selected mannequin and data the time, value, correctness, and output tokens. per_thousand converts the common to {dollars} per 1,000 requests. The principle block runs Haiku, Sonnet, and Opus in flip and prints one row every. If a mannequin or platform rejects the request, the script prints the error and strikes on. Eight messages are a smoke take a look at, so exchange them with samples from your personal site visitors earlier than you determine something.
python compare_models.pyWhen you wait on your personal numbers, record costs give a clear comparability. Take a classification name with 300 enter tokens and 30 output tokens, and ignore pondering tokens. On the printed costs, that prices:
| Mannequin | Enter / output per million tokens | Value per 1,000 calls |
|---|---|---|
| Haiku 5.5 | $0.10 / $0.50 | $0.045 |
| Sonnet 5.5 | $2.00 / $10.00 | $0.90 |
| Opus 5.5 | $4.00 / $20.00 | $1.80 |
The fee per 1,000 calls is (300 × enter worth + 30 × output worth) ÷ 1,000,000 × 1,000. That is arithmetic from record costs, not a measurement, and the three fashions share the identical tokenizer household, so the token counts are comparable. On pace, Anthropic says Haiku 5.5 is its quickest mannequin at normal pace, although Opus fashions in Quick Mode are faster. Clients report the hole in observe: Asana noticed over 30% decrease process latency than the mannequin it makes use of as we speak, and Field measured about half the latency of Haiku 4.5.
When to Attain for Haiku, and When Not To
Attain for Haiku 5.5 when the duty is slender, the amount is excessive, or an individual is ready: classification, routing, extraction, summaries, compaction, and sub-agent work. AlphaSense reported that Haiku 5.5 beat Haiku 4.5 on its doc question-answering workload — 0.84 in opposition to 0.76 — on a job that makes about 8 million calls per week. Stick with Sonnet 5.5 or Opus 5.5 for advanced agentic coding, the place Anthropic says the bigger fashions stay the higher selection. The hole is seen within the benchmarks above. A great rule is to start out with Haiku on each high-volume step, take a look at it on a pattern of your actual information, and transfer a step up solely the place the outcomes fall brief.
Wrapping Up
Haiku 5.5 additionally has an extended runway than its predecessor. Anthropic lists its earliest retirement at October 7, 2027, whereas Haiku 4.5’s earliest date is October 15, 2026 — which is as we speak, although it’s nonetheless listed as energetic and Anthropic commits to advance discover earlier than retiring a mannequin. The SDKs additionally gained beta help for pc use and browser use, the duties Anthropic says swimsuit a quick, low-cost mannequin. My learn is that extra agent work will transfer to small fashions operating in parallel beneath a bigger planner, because the proof so removed from Anthropic’s clients factors that approach. That’s an expectation, not a promise.
To recap: Haiku 5.5 cuts record costs by 90% for many prompts and provides adaptive pondering, a 1M context window, and a big soar on Anthropic’s benchmarks. Migrating means dropping sampling parameters and prefill, studying content material blocks by kind, and budgeting for extra tokens. Use it for classification, extraction, and sub-agents, measure it in opposition to Sonnet and Opus by yourself information, and escalate solely when it falls brief.
Shittu Olumide is a software program engineer and technical author obsessed with leveraging cutting-edge applied sciences to craft compelling narratives, with a eager eye for element and a knack for simplifying advanced ideas. You can even discover Shittu on Twitter.