

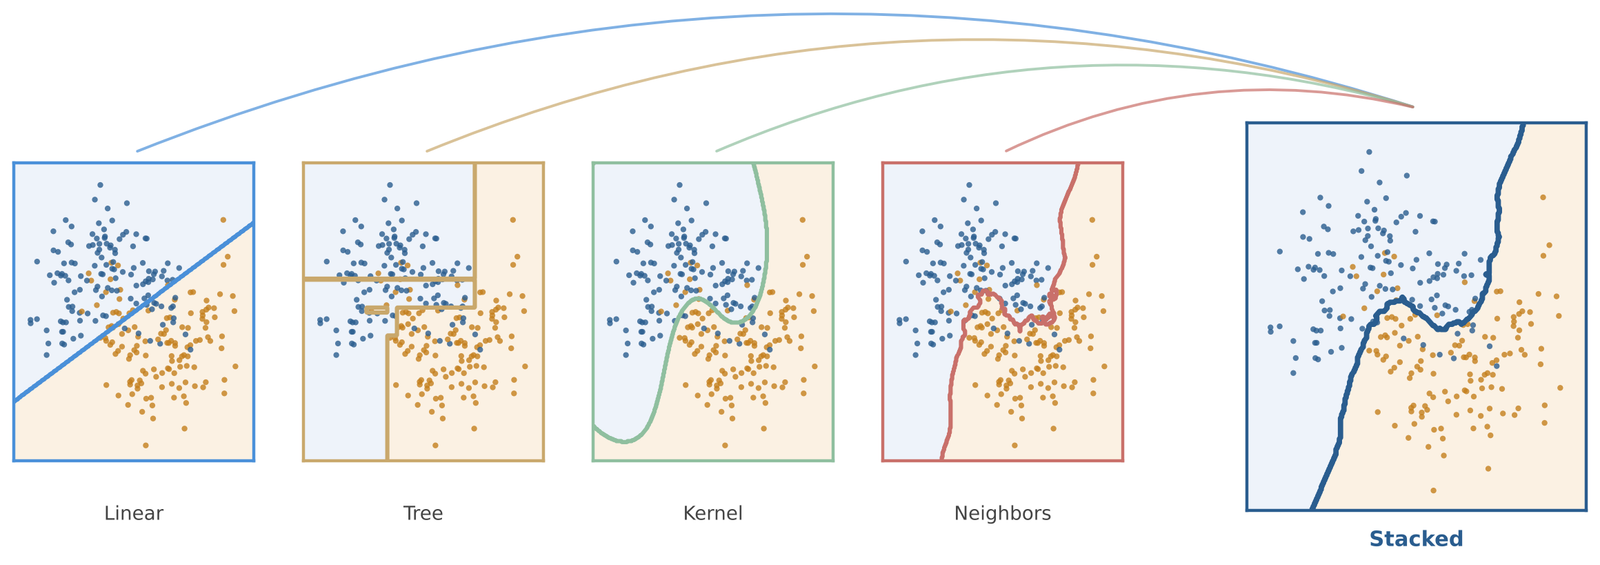
The theoretical case for stacking
Ensembling is near gospel in aggressive ML: stack a handful of fashions, feed their predictions right into a meta-model that learns find out how to mix them, and also you usually beat any single mannequin within the stack. The theoretical mechanism is particular, not obscure: it really works when the bottom fashions make completely different sorts of errors. If mannequin A will get proper what mannequin B will get fallacious, a meta-model can study to belief every one the place it is dependable. If all the bottom fashions make the similar errors, there’s nothing complementary to mix, and stacking should purchase you little to nothing.
That is a testable, falsifiable declare, not simply “stacking is nice,” however particularly “stacking’s profit scales with how in a different way your base fashions err.” So I constructed two situations on the identical dataset, one designed to offer stacking actual room to assist and one designed to take that room away, and measured what really occurred. Each end result beneath comes from repeated stratified 5-fold cross-validation (3 repeats, 15 whole folds) somewhat than a single practice/check cut up — a robustness repair for a limitation flagged in an earlier benchmark of mine, the place single-split numbers can transfer round greater than they need to.
Dataset: an artificial binary classification downside (sklearn.datasets.make_classification, 2,000 samples, 20 options, real looking noise and sophistication overlap) — clearly artificial, chosen so the base-model variety might be managed instantly somewhat than being an accident of no matter actual dataset occurred to be mendacity round.
Situation 1 — various base fashions, the setup stacking’s idea is constructed on: logistic regression (linear), a choice tree (axis-aligned splits), an SVM (kernel-based, a essentially completely different choice boundary), and k-nearest-neighbors (instance-based, no express boundary in any respect). 4 genuinely other ways of drawing a choice boundary.
Situation 2 — correlated base fashions, intentionally working towards stacking’s idea: random forest, gradient boosting, and extra-trees — three variants of the identical underlying concept (tree ensembles), more likely to agree with one another excess of the varied group does.
The outcomes
|
Situation |
Greatest single mannequin |
Voting ensemble |
Stacking ensemble |
|---|---|---|---|
|
Numerous base fashions |
0.820 (SVC) |
0.809 |
0.830 |
|
Correlated base fashions |
0.834 (ExtraTrees) |
0.829 |
0.835 |
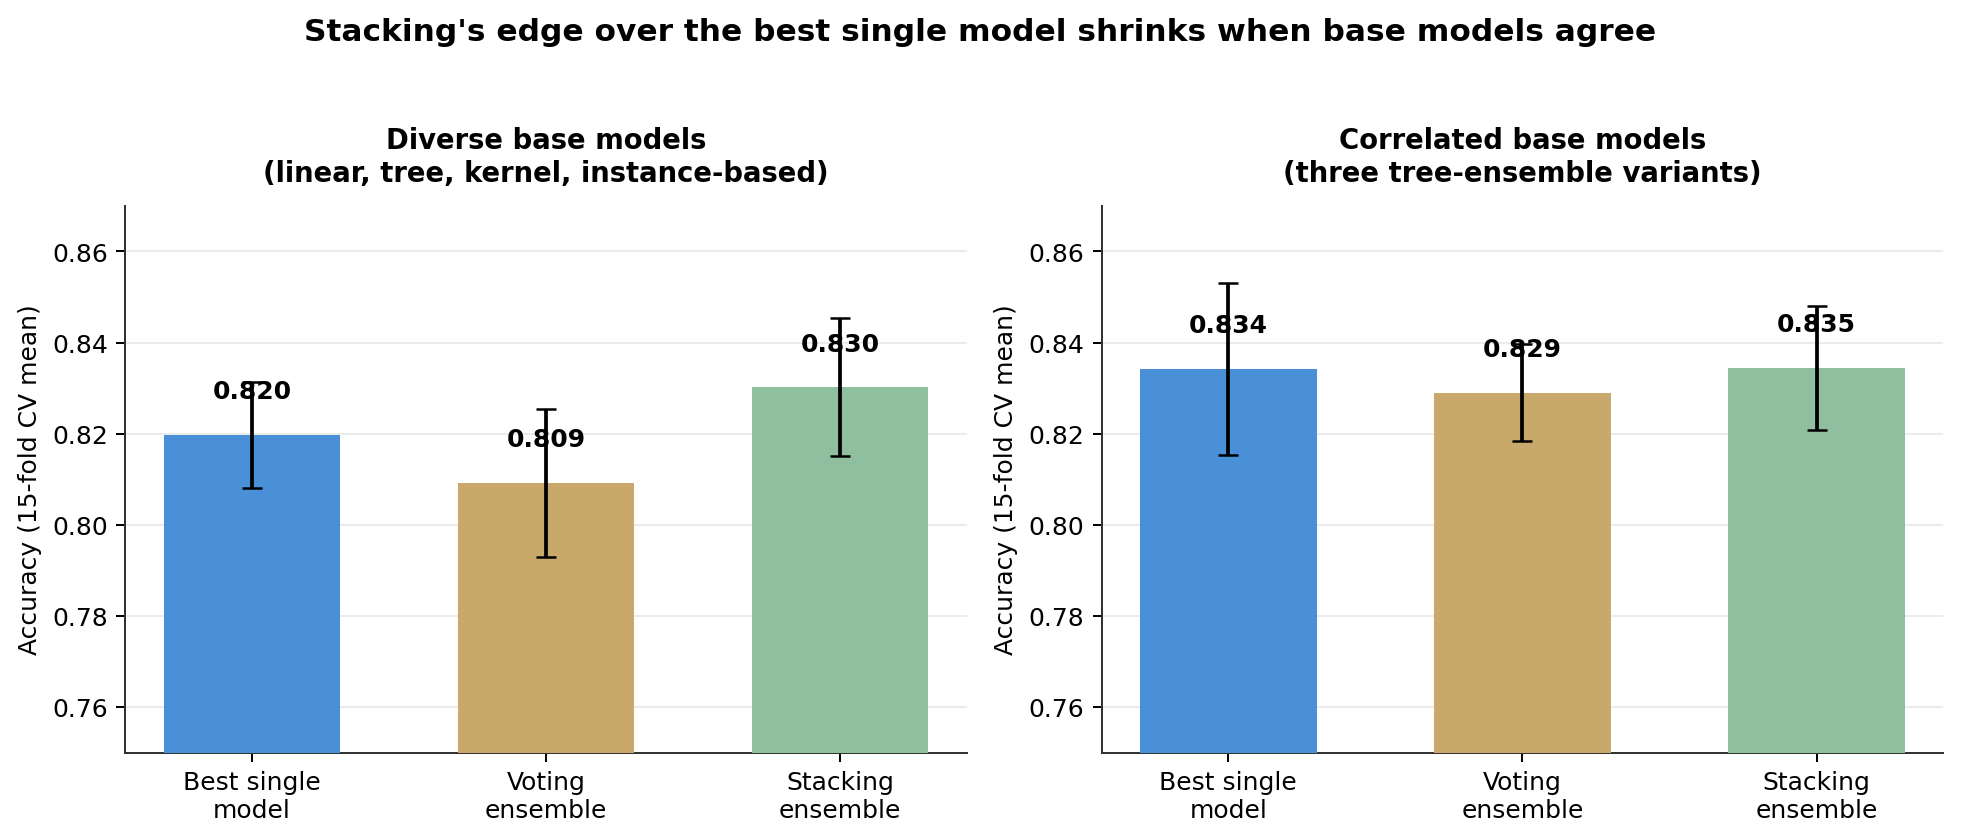
Within the various situation, stacking earned its maintain. 0.830 versus the most effective single mannequin’s 0.820 — an actual, significant hole given the error bars (±0.015 for stacking, ±0.012 for the one mannequin) barely overlap. That is stacking behaving precisely the best way its theoretical case predicts: 4 fashions making genuinely completely different sorts of errors gave the meta-model actual complementary sign to mix.
Within the correlated situation, stacking’s edge almost vanished. 0.835 versus 0.834 — a 0.1-point distinction that is fully swallowed by the usual deviation on both quantity (±0.014 and ±0.019 respectively). Three tree-ensemble variants agree with one another intently sufficient that there was nearly nothing left for a meta-model to take advantage of. That is the idea’s personal prediction, confirmed instantly: no error variety, no stacking profit.
The shock: voting underperformed the most effective single mannequin in each situations. Not stacking — plain averaging. 0.809 versus 0.820 within the various situation, 0.829 versus 0.834 within the correlated one. Easy voting has no strategy to down-weight a genuinely weaker mannequin within the combine; it simply averages everybody in, together with whichever base mannequin is dragging the group down. Stacking’s meta-model, against this, learns how a lot to belief every base mannequin — which is precisely why it did not endure the identical destiny.
The associated fee aspect of the ledger
|
Situation |
Greatest single mannequin |
Voting ensemble |
Stacking ensemble |
|---|---|---|---|
|
Numerous base fashions |
4.8s (SVC) |
5.4s |
23.7s |
|
Correlated base fashions |
3.6s (ExtraTrees) |
24.9s |
125.9s |
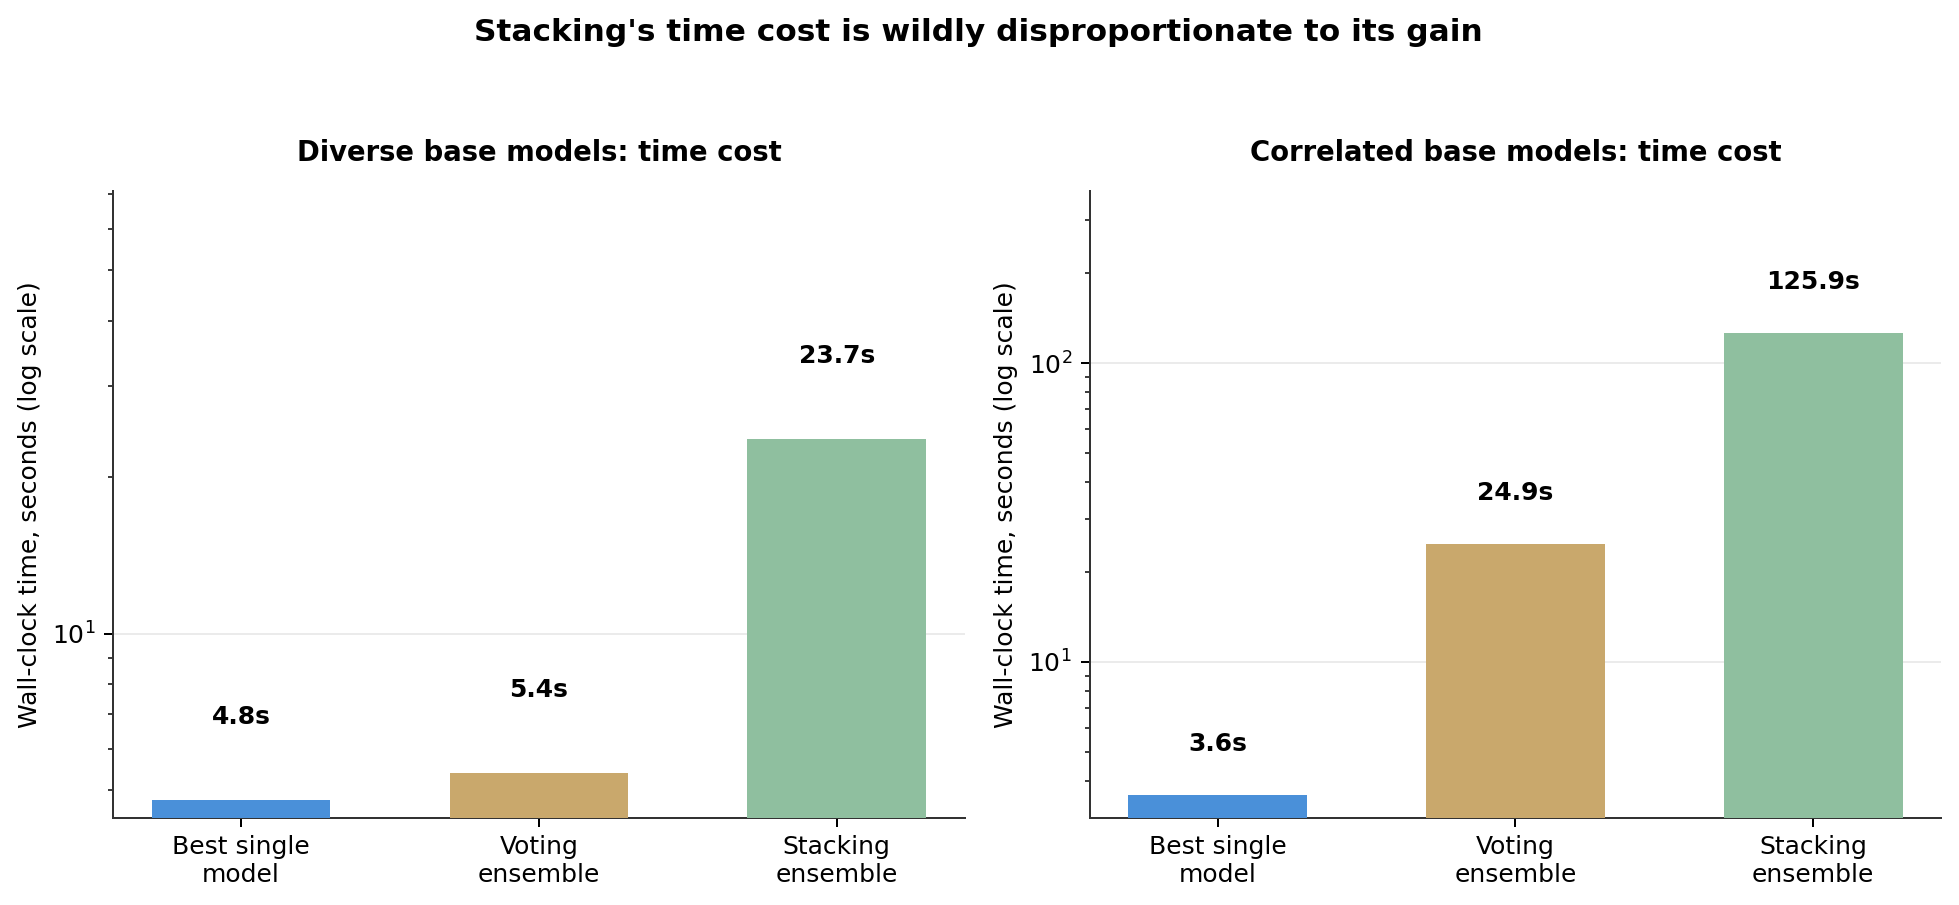
Within the various situation, stacking’s 23.7 seconds for a real 1-point accuracy acquire is an affordable commerce in most actual settings. Within the correlated situation, it is a a lot tougher promote: 125.9 seconds — roughly 35x the one mannequin’s coaching time — for a 0.1-point distinction that is not statistically distinguishable from zero. That is not a rounding error in a analysis paper; in a pipeline that retrains repeatedly, it is an actual, recurring value paid for nothing.
Why voting misplaced even when stacking received
This deserves its personal rationalization, as a result of it is the least intuitive end result right here. Voting and stacking use the identical base fashions — the one distinction is how they’re mixed. Voting takes a hard and fast, equal-weighted common of each base mannequin’s prediction. Stacking trains a second mannequin whose total job is to study the appropriate weighting, knowledgeable by which base fashions are literally dependable on which sorts of examples.
Within the various situation, KNN and the plain choice tree had been the weakest of the 4 base fashions — strong however clearly behind the SVM. Voting has no mechanism to note that and downweight them; it simply averages all 4 in in equal proportion, and the weaker two drag the ensemble beneath what the strongest single mannequin achieved by itself. Stacking’s meta-model, educated on out-of-fold predictions from all 4, learns one thing nearer to “belief the SVM extra, the tree much less” — which is exactly the mechanism that allow it beat the most effective single mannequin as an alternative of getting dragged down by the weakest one.
The place this comparability falls brief
-
One artificial dataset. The variety-versus-correlation sample is a property of ensemble idea normally, not this dataset particularly, however the actual numbers (the dimensions of stacking’s edge, the dimensions of voting’s shortfall) would shift on actual, messier knowledge with a distinct noise profile.
-
Base mannequin selections, not an exhaustive search. A unique alternative of 4 “various” fashions, or three “correlated” ones, may shift these particular numbers — although the underlying mechanism (variety creates room for a meta-model so as to add worth) ought to maintain no matter which particular fashions embody “various” versus “correlated.”
-
Binary classification solely. Multi-class or regression stacking can behave in a different way, notably round how the meta-model’s cross-validation is structured.
The precise choice framework
Earlier than reaching for a stacking ensemble over your single finest mannequin, three questions:
-
Do your candidate base fashions really make completely different sorts of errors, or do they simply have completely different names? Three tree-ensemble variants sound various however usually aren’t, in the best way that truly issues for stacking. Verify correlation between base fashions’ predictions (or errors) earlier than assuming variety — it is one line of code and it instantly predicts how a lot stacking will assist.
-
Is the accuracy acquire, if any, bigger than your fold-to-fold noise? A single practice/check cut up will fortunately report a stacking “win” that is really simply noise — cross-validate and have a look at the unfold, not simply the imply, earlier than trusting a comparability like this one.
-
What is the precise value of retraining a stack versus a single mannequin, at your actual retraining frequency? 126 seconds as soon as is nothing. 126 seconds each night time for a 12 months, for a acquire throughout the noise flooring, is a value value naming explicitly somewhat than paying by default.
The takeaway
“Stacking beats your finest single mannequin” is true beneath a particular, checkable situation — real variety in how the bottom fashions err — and significantly much less true exterior it. The extra attention-grabbing and extra actionable discovering right here is not stacking versus single fashions within the summary; it is that naive voting can really underperform your finest particular person mannequin even when stacking, utilizing the very same base fashions, would not. Combining fashions is not free, and averaging is not the identical as combining effectively — the meta-model’s skill to study who to belief and when is doing actual work {that a} easy common cannot replicate.