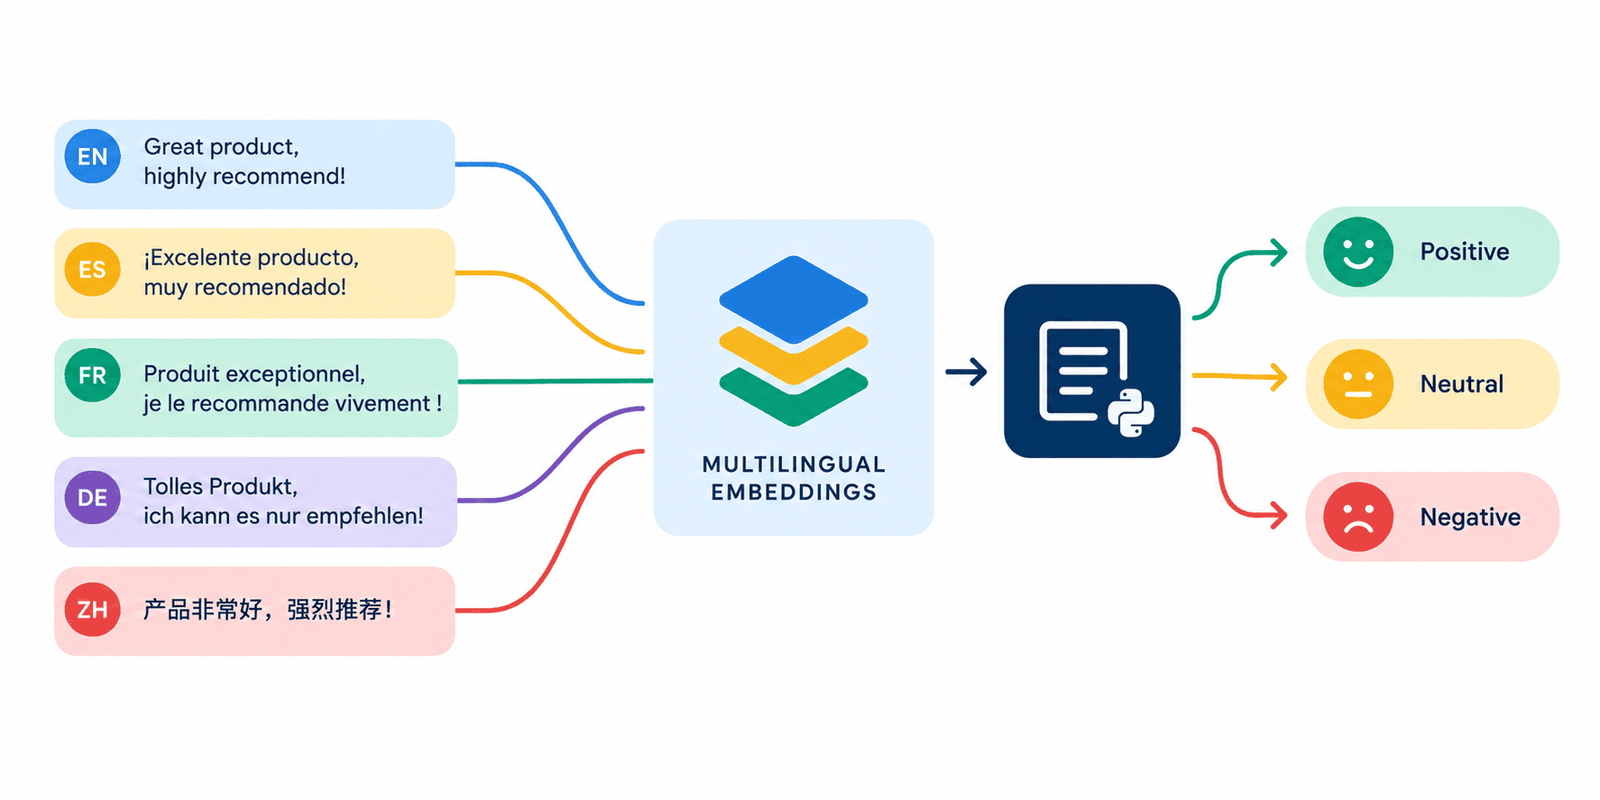
On this article, you’ll learn to construct a multilingual textual content classification pipeline utilizing multilingual massive language mannequin (LLM) embeddings and Scikit-learn, with out coaching separate fashions for every language.
Matters we’ll cowl embrace:
- What multilingual LLM embeddings are and why they get rid of the necessity for language-specific fashions.
- The way to arrange a free, native embedding pipeline utilizing Ollama, BGE-M3, and Scikit-LLM.
- The way to practice and consider a logistic regression classifier on high of multilingual embeddings utilizing a real-world evaluation dataset.
Introduction
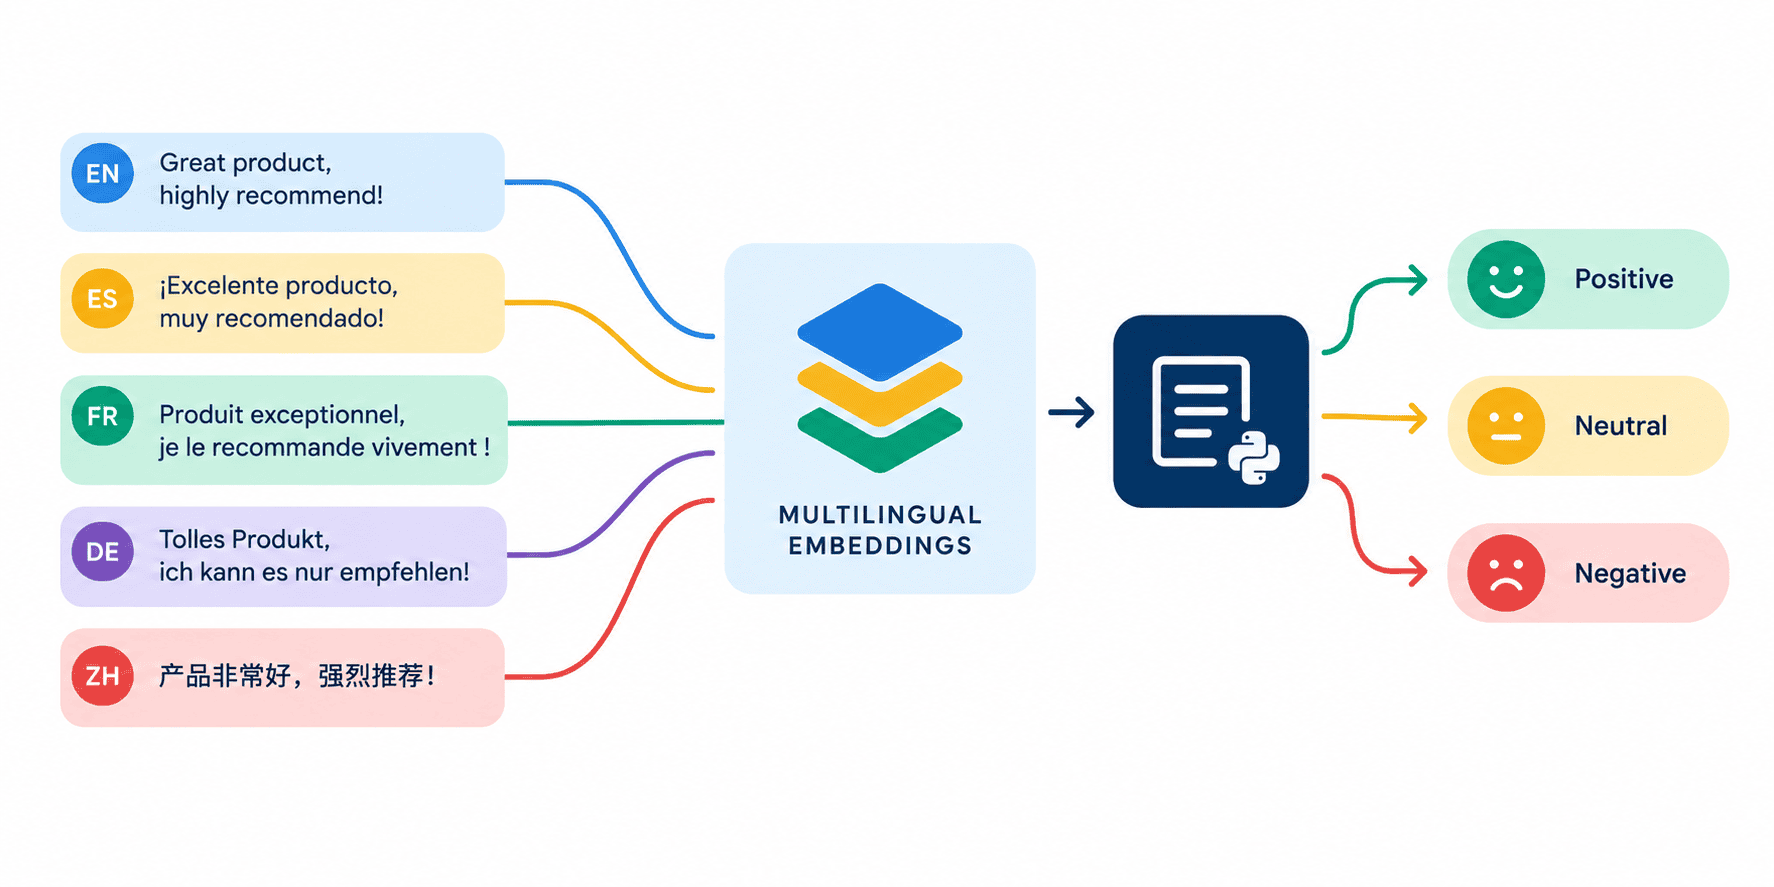
Constructing machine studying fashions for a worldwide viewers, resembling textual content classifiers primarily based on multilingual information, historically required coaching a separate mannequin for every language. Thus, the method may simply turn out to be unmanageable. Fortunately, progress in LLMs additionally extends to situations like this! Multilingual LLM embeddings are numerical representations of textual content produced by a mannequin that maps textual content from totally different languages into a typical vector area. With these “barrier-free” embeddings, all it takes thereafter is coaching a downstream, light-weight classifier on high of them. Let’s uncover how to do that step-by-step, aided by Scikit-LLM.
Preliminary Setup
Within the sequel, we’ll assemble a multilingual textual content classification pipeline aided by Scikit-LLM and scikit-learn.
|
# Putting in Python dependencies pip set up scikit–llm “datasets==2.19.1” –q
# Repair Colab’s lacking system dependencies first (version-dependent, use with care in different environments) apt–get replace –qq && apt–get set up –y –qq zstd
# Putting in Ollama distribution curl –fsSL https://ollama.com/set up.sh | sh |
Making certain a 100% free and runnable answer in a wide range of operating environments, together with notebooks, requires bypassing paid APIs like OpenAI. That’s why, as an alternative, now we have put in an Ollama distribution providing a wide range of free LLMs. Accordingly, within the subsequent steps we’ll configure Scikit-LLM to talk to a neighborhood Ollama server operating BGE-M3, which is a state-of-the-art, open-source mannequin supporting multilingual data within the embedding technology course of.
Subsequent, we begin the Ollama server as a background course of —that is essentially the most hassle-free means to make use of Ollama in a cloud-based pocket book, however not obligatory if working with your personal IDE and native Ollama distribution. We additionally pull the aforementioned multilingual mannequin for embedding technology, BGE-M3 (extra details about this mannequin on its official web site).
|
import subprocess import time
# Beginning the Ollama server within the background subprocess.Popen([“ollama”, “serve”]) time.sleep(5) # Give the server a number of seconds to initialize
# Pulling the multilingual embedding mannequin ollama pull bge–m3 |
The final configuration step is to make use of Scikit-LLM’s configuration module to level it to our Ollama occasion. The configuration strategy we’re utilizing doesn’t require an precise key, however a dummy one, as proven under:
|
from skllm.config import SKLLMConfig
# Level Scikit-LLM to our native Ollama occasion SKLLMConfig.set_gpt_url(“http://localhost:11434/v1/”)
# Present a dummy key (required by the inner shopper, however safely ignored by Ollama) SKLLMConfig.set_openai_key(“free-friendly-dummy-key”) |
Constructing the Pipeline
The primary main step in constructing our multilingual classification pipeline is, in fact, getting the info. We are going to contemplate the Amazon Multi-language Evaluations dataset, which has labeled buyer evaluations on a 5-star ranking scale (internally encoded with labels 0 to 4). To keep away from an excessively time-consuming execution — particularly concerning the embedding technology course of in a while — we’ll load a complete of 2000 evaluations in each English and Spanish. Be happy to pick out a bigger pattern should you’d wish to, however attempt to preserve it language-balanced and guarantee random shuffling of your information earlier than making use of additional steps like a training-test break up.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 |
from datasets import load_dataset import pandas as pd
print(“Loading and shuffling information to make sure class range…”)
# 1. Loading the whole break up # 2. Shuffling it randomly with shuffle() # 3. Extracting 1000 different samples with choose(vary(1000)) data_en = (load_dataset(“mteb/amazon_reviews_multi”, “en”, break up=“practice”, trust_remote_code=True) .shuffle(seed=42) .choose(vary(1000)))
data_es = (load_dataset(“mteb/amazon_reviews_multi”, “es”, break up=“practice”, trust_remote_code=True) .shuffle(seed=42) .choose(vary(1000)))
# Combining right into a single DataFrame df = pd.concat([pd.DataFrame(data_en), pd.DataFrame(data_es)], ignore_index=True)
# Shuffling bilingual information df = df.pattern(frac=1, random_state=42).reset_index(drop=True)
# Options and Labels X = df[‘text’] y = df[‘label’]
print(f“Complete samples: {len(X)}”) print(“n— Class Verification (ought to have samples from 0 to 4) —“) print(y.value_counts()) |
Output:
|
Loading and shuffling information to guarantee class range... Complete samples: 2000
—– Class Verification (ought to have samples from 0 to 4) —– label 0 444 3 410 2 404 4 380 1 362 Title: rely, dtype: int64 |
The magic occurs subsequent. We outline a scikit-learn pipeline consisting of two main phases:
- Utilizing a GPTVectorizer from Scikit-LLM and having it set as much as make the most of our beforehand loaded BGE-M3 mannequin for constructing embeddings.
- Feeding the embeddings to coach a classifier primarily based on a LogisticRegression mannequin kind.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 |
from skllm.fashions.gpt.vectorization import GPTVectorizer from sklearn.pipeline import Pipeline from sklearn.linear_model import LogisticRegression from sklearn.model_selection import train_test_split from sklearn.metrics import classification_report
# Splitting into 80% coaching and 20% testing X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)
# Defining the Pipeline pipeline = Pipeline([ (“vectorizer”, GPTVectorizer(model=“bge-m3”, batch_size=32)), (“classifier”, LogisticRegression(max_iter=1000, random_state=42)) ])
# Coaching the pipeline print(“Extracting embeddings and coaching classifier…”) pipeline.match(X_train, y_train) |
Why did I say the magic takes place right here? Let’s look extra intently:
BGE-M3 is a multilingual embedding mannequin that has been pre-trained on large information spanning over 100 languages. Put one other means, it’s able to internally mapping each our English and Spanish evaluations into a typical dimensional (embedding) area: not primarily based on their concrete vocabulary, however primarily based on the that means behind it. Thus, language boundaries disappear in the course of the strategy of producing embeddings, with LLM outputs for “This product is unbelievable!” and “¡Este producto es fantástico!” being practically similar.
Consequently, by the point the embeddings arrive on the logistic regression mannequin for coaching and inference, the classifier doesn’t truly care in regards to the language anymore. It has the knowledge it must carry out ranking classifications on product evaluations.
|
print(“Evaluating on the take a look at set…”) y_pred = pipeline.predict(X_test)
print(“n— Classification Report —“) print(classification_report(y_test, y_pred)) |
Outcomes:
|
—– Classification Report —– precision recall f1–rating assist
0 0.66 0.78 0.72 82 1 0.40 0.30 0.34 64 2 0.46 0.46 0.46 91 3 0.56 0.54 0.55 84 4 0.71 0.73 0.72 79
accuracy 0.57 400 macro avg 0.56 0.56 0.56 400 weighted avg 0.56 0.57 0.56 400 |
The outcomes are simply okay, however not nice. There may be considerably higher efficiency in appropriately predicting excessive scores (0 for 1-star, 4 for 5-star) than for predicting intermediate scores. Don’t panic; there are at the very least two causes for this:
- The classification activity at hand is inherently difficult: distinguishing between a 3-star and a 4-star evaluation is intuitively more durable than discerning, for example, between constructive, unfavourable, and impartial evaluations.
- Extra importantly, now we have used simply 2000 samples (80% of them for mannequin coaching), however these samples are embeddings with 1024 options every. Feeding such a small quantity of high-dimensional information to a classifier is almost certainly the right recipe for overfitting your mannequin. When you’ve got the time to run the code for longer, strive utilizing a number of thousand extra examples as an alternative.
Wrapping Up
In conventional pure language processing, we have been typically confronted with two far-from-ideal choices when dealing with multilingual information for predictive duties like textual content classification: translate all of your information right into a base language — a sluggish, costly course of with frequent lack of nuance — or practice separate fashions: one for each language. Within the pipeline we simply constructed, the heavy burden is assumed by the multilingual embedding mannequin (BGE-M3) leveraged by Scikit-LLM, which is able to transparently mapping textual content throughout a wide range of languages right into a uniform embedding area.
On this article, you’ll learn to construct a multilingual textual content classification pipeline utilizing multilingual massive language mannequin (LLM) embeddings and Scikit-learn, with out coaching separate fashions for every language.
Matters we’ll cowl embrace:
- What multilingual LLM embeddings are and why they get rid of the necessity for language-specific fashions.
- The way to arrange a free, native embedding pipeline utilizing Ollama, BGE-M3, and Scikit-LLM.
- The way to practice and consider a logistic regression classifier on high of multilingual embeddings utilizing a real-world evaluation dataset.
Introduction
Constructing machine studying fashions for a worldwide viewers, resembling textual content classifiers primarily based on multilingual information, historically required coaching a separate mannequin for every language. Thus, the method may simply turn out to be unmanageable. Fortunately, progress in LLMs additionally extends to situations like this! Multilingual LLM embeddings are numerical representations of textual content produced by a mannequin that maps textual content from totally different languages into a typical vector area. With these “barrier-free” embeddings, all it takes thereafter is coaching a downstream, light-weight classifier on high of them. Let’s uncover how to do that step-by-step, aided by Scikit-LLM.
Preliminary Setup
Within the sequel, we’ll assemble a multilingual textual content classification pipeline aided by Scikit-LLM and scikit-learn.
|
# Putting in Python dependencies pip set up scikit–llm “datasets==2.19.1” –q
# Repair Colab’s lacking system dependencies first (version-dependent, use with care in different environments) apt–get replace –qq && apt–get set up –y –qq zstd
# Putting in Ollama distribution curl –fsSL https://ollama.com/set up.sh | sh |
Making certain a 100% free and runnable answer in a wide range of operating environments, together with notebooks, requires bypassing paid APIs like OpenAI. That’s why, as an alternative, now we have put in an Ollama distribution providing a wide range of free LLMs. Accordingly, within the subsequent steps we’ll configure Scikit-LLM to talk to a neighborhood Ollama server operating BGE-M3, which is a state-of-the-art, open-source mannequin supporting multilingual data within the embedding technology course of.
Subsequent, we begin the Ollama server as a background course of —that is essentially the most hassle-free means to make use of Ollama in a cloud-based pocket book, however not obligatory if working with your personal IDE and native Ollama distribution. We additionally pull the aforementioned multilingual mannequin for embedding technology, BGE-M3 (extra details about this mannequin on its official web site).
|
import subprocess import time
# Beginning the Ollama server within the background subprocess.Popen([“ollama”, “serve”]) time.sleep(5) # Give the server a number of seconds to initialize
# Pulling the multilingual embedding mannequin ollama pull bge–m3 |
The final configuration step is to make use of Scikit-LLM’s configuration module to level it to our Ollama occasion. The configuration strategy we’re utilizing doesn’t require an precise key, however a dummy one, as proven under:
|
from skllm.config import SKLLMConfig
# Level Scikit-LLM to our native Ollama occasion SKLLMConfig.set_gpt_url(“http://localhost:11434/v1/”)
# Present a dummy key (required by the inner shopper, however safely ignored by Ollama) SKLLMConfig.set_openai_key(“free-friendly-dummy-key”) |
Constructing the Pipeline
The primary main step in constructing our multilingual classification pipeline is, in fact, getting the info. We are going to contemplate the Amazon Multi-language Evaluations dataset, which has labeled buyer evaluations on a 5-star ranking scale (internally encoded with labels 0 to 4). To keep away from an excessively time-consuming execution — particularly concerning the embedding technology course of in a while — we’ll load a complete of 2000 evaluations in each English and Spanish. Be happy to pick out a bigger pattern should you’d wish to, however attempt to preserve it language-balanced and guarantee random shuffling of your information earlier than making use of additional steps like a training-test break up.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 |
from datasets import load_dataset import pandas as pd
print(“Loading and shuffling information to make sure class range…”)
# 1. Loading the whole break up # 2. Shuffling it randomly with shuffle() # 3. Extracting 1000 different samples with choose(vary(1000)) data_en = (load_dataset(“mteb/amazon_reviews_multi”, “en”, break up=“practice”, trust_remote_code=True) .shuffle(seed=42) .choose(vary(1000)))
data_es = (load_dataset(“mteb/amazon_reviews_multi”, “es”, break up=“practice”, trust_remote_code=True) .shuffle(seed=42) .choose(vary(1000)))
# Combining right into a single DataFrame df = pd.concat([pd.DataFrame(data_en), pd.DataFrame(data_es)], ignore_index=True)
# Shuffling bilingual information df = df.pattern(frac=1, random_state=42).reset_index(drop=True)
# Options and Labels X = df[‘text’] y = df[‘label’]
print(f“Complete samples: {len(X)}”) print(“n— Class Verification (ought to have samples from 0 to 4) —“) print(y.value_counts()) |
Output:
|
Loading and shuffling information to guarantee class range... Complete samples: 2000
—– Class Verification (ought to have samples from 0 to 4) —– label 0 444 3 410 2 404 4 380 1 362 Title: rely, dtype: int64 |
The magic occurs subsequent. We outline a scikit-learn pipeline consisting of two main phases:
- Utilizing a GPTVectorizer from Scikit-LLM and having it set as much as make the most of our beforehand loaded BGE-M3 mannequin for constructing embeddings.
- Feeding the embeddings to coach a classifier primarily based on a LogisticRegression mannequin kind.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 |
from skllm.fashions.gpt.vectorization import GPTVectorizer from sklearn.pipeline import Pipeline from sklearn.linear_model import LogisticRegression from sklearn.model_selection import train_test_split from sklearn.metrics import classification_report
# Splitting into 80% coaching and 20% testing X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)
# Defining the Pipeline pipeline = Pipeline([ (“vectorizer”, GPTVectorizer(model=“bge-m3”, batch_size=32)), (“classifier”, LogisticRegression(max_iter=1000, random_state=42)) ])
# Coaching the pipeline print(“Extracting embeddings and coaching classifier…”) pipeline.match(X_train, y_train) |
Why did I say the magic takes place right here? Let’s look extra intently:
BGE-M3 is a multilingual embedding mannequin that has been pre-trained on large information spanning over 100 languages. Put one other means, it’s able to internally mapping each our English and Spanish evaluations into a typical dimensional (embedding) area: not primarily based on their concrete vocabulary, however primarily based on the that means behind it. Thus, language boundaries disappear in the course of the strategy of producing embeddings, with LLM outputs for “This product is unbelievable!” and “¡Este producto es fantástico!” being practically similar.
Consequently, by the point the embeddings arrive on the logistic regression mannequin for coaching and inference, the classifier doesn’t truly care in regards to the language anymore. It has the knowledge it must carry out ranking classifications on product evaluations.
|
print(“Evaluating on the take a look at set…”) y_pred = pipeline.predict(X_test)
print(“n— Classification Report —“) print(classification_report(y_test, y_pred)) |
Outcomes:
|
—– Classification Report —– precision recall f1–rating assist
0 0.66 0.78 0.72 82 1 0.40 0.30 0.34 64 2 0.46 0.46 0.46 91 3 0.56 0.54 0.55 84 4 0.71 0.73 0.72 79
accuracy 0.57 400 macro avg 0.56 0.56 0.56 400 weighted avg 0.56 0.57 0.56 400 |
The outcomes are simply okay, however not nice. There may be considerably higher efficiency in appropriately predicting excessive scores (0 for 1-star, 4 for 5-star) than for predicting intermediate scores. Don’t panic; there are at the very least two causes for this:
- The classification activity at hand is inherently difficult: distinguishing between a 3-star and a 4-star evaluation is intuitively more durable than discerning, for example, between constructive, unfavourable, and impartial evaluations.
- Extra importantly, now we have used simply 2000 samples (80% of them for mannequin coaching), however these samples are embeddings with 1024 options every. Feeding such a small quantity of high-dimensional information to a classifier is almost certainly the right recipe for overfitting your mannequin. When you’ve got the time to run the code for longer, strive utilizing a number of thousand extra examples as an alternative.
Wrapping Up
In conventional pure language processing, we have been typically confronted with two far-from-ideal choices when dealing with multilingual information for predictive duties like textual content classification: translate all of your information right into a base language — a sluggish, costly course of with frequent lack of nuance — or practice separate fashions: one for each language. Within the pipeline we simply constructed, the heavy burden is assumed by the multilingual embedding mannequin (BGE-M3) leveraged by Scikit-LLM, which is able to transparently mapping textual content throughout a wide range of languages right into a uniform embedding area.