Introduction
Retrieval-augmented era (RAG) solutions questions utilizing info retrieved from a set of paperwork. That doc assortment is named a corpus. A typical analysis sends a well-written query to a tidy corpus and checks whether or not the retriever returns the appropriate passage.
Manufacturing doc collections hardly ever keep tidy.
Previous pages stay searchable after a coverage adjustments. Customers kind “warehuse” as an alternative of “warehouse.” Optical character recognition (OCR), the software program that extracts textual content from scans, could learn “SSO” as “SS0.” A desk may also be divided at a web page boundary, separating a quantity from its label.
Every downside can ship the retriever to the flawed passage. The language mannequin then receives incorrect or incomplete context, so even a well-written reply could also be flawed.
On this article we are going to see a small retriever and fault injection, which suggests intentionally including issues to check how a system responds. I added an outdated coverage web page, an OCR character swap, a question typo, and a divided desk.
···
Hey there, I am Sara Nóbrega, an AI engineer with background in physics. For those who’re engaged on comparable issues or need suggestions on making use of these concepts, I accumulate my writing, sources, and mentoring hyperlinks right here).
···
The Toy Pipeline
A retriever searches paperwork and returns the passages that seem most related to a query. RAG techniques normally divide every doc into smaller passages known as chunks earlier than indexing them for search.
This instance retains the retrieval technique intentionally easy. It has 4 quick paperwork and one scoring operate. The operate splits the question and every doc into lowercase phrases, known as tokens. It then offers a doc 1 level for each question token present in that doc. The doc with the best rating wins.
Every Doc shops an ID, its textual content, a subject, and the date it was up to date. Manufacturing techniques usually use extra complicated matching strategies. Actual token matching makes every failure simple to see, and the identical enter issues can have an effect on these techniques.
Stale paperwork that contradict one another
The returns coverage modified from 60 days to 30 days firstly of 2026. The ingestion course of copies supply paperwork right into a searchable index. Right here, it added the brand new web page with out eradicating the outdated one.
Each pages obtain the identical token-overlap rating as a result of every incorporates “returns” and “days.” The retriever wants a rule for equal scores, referred to as a tiebreaker. Right here it makes use of checklist order, so it returns the primary web page: the coverage from 2024. A buyer might be advised they’ve 60 days to return an merchandise when the present restrict is 30.
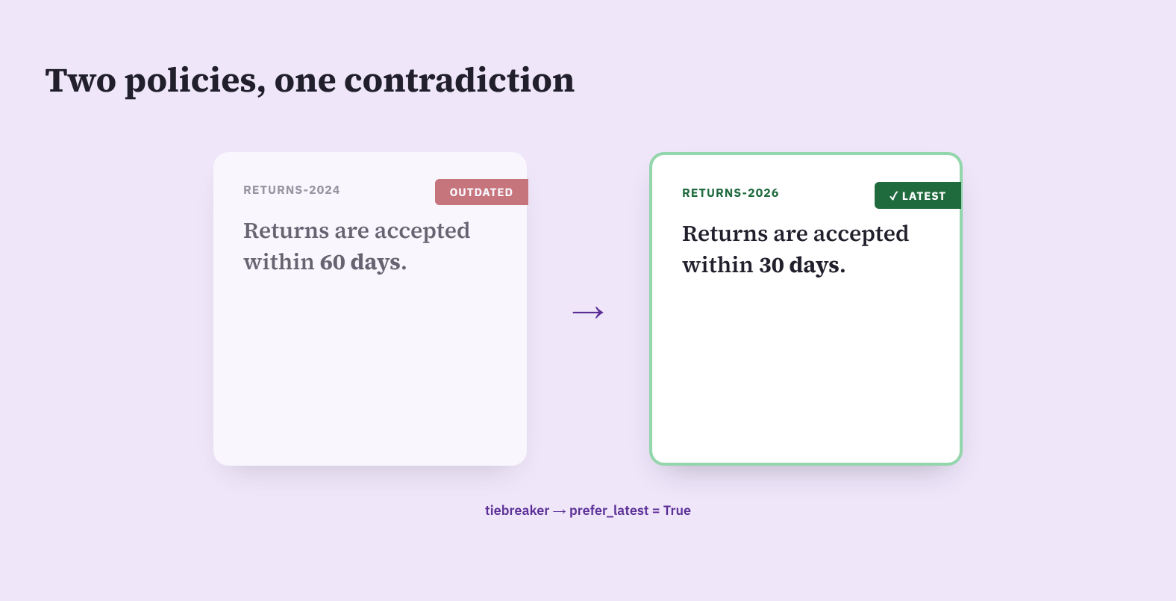
The correction provides a recency tiebreaker. When paperwork obtain the identical rating, the retriever prefers the one with the later up to date date.
This rule suits insurance policies with a transparent alternative date. Different collections may have an specific standing reminiscent of present or retired, particularly when a more moderen doc doesn’t exchange an older one.
OCR errors that cover the matching phrases
OCR converts scanned pages into searchable textual content. Related-looking letters and numbers trigger frequent extraction errors. The defective OCR output adjustments “Enterprise” to “Enterpr1se” and “SSO” to “SS0.”
The extracted textual content incorporates enterpr1se and ss0, so the question tokens enterprise and sso every obtain 0 factors. All 4 paperwork tie at 0, and checklist order sends the returns coverage again because the end result.
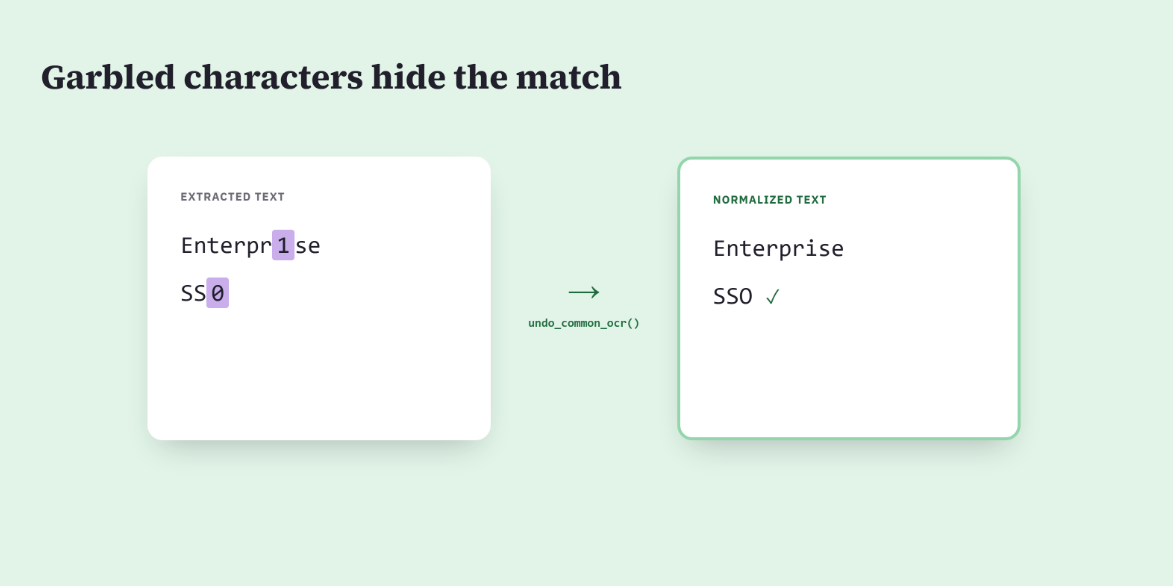
A normalization operate corrects recognized OCR substitutions earlier than tokenization. Making use of it to each queries and paperwork offers the scorer constant textual content.
Manufacturing normalization guidelines want care. Changing each 0 to o, for instance, may injury product codes or measurements. Construct substitutions from errors present in your individual extracted paperwork and restrict them to fields the place the change is secure.
A typo within the question
Customers make spelling errors. “warehuse sync” is lacking one letter from “warehouse sync,” and a precise token matcher treats the two phrases as unrelated.
The misspelled token contributes 0 factors. This leaves sync to find out the end result. Each the CRM doc and the warehouse stock doc comprise it, so the tie goes to the CRM doc as a result of it seems first.
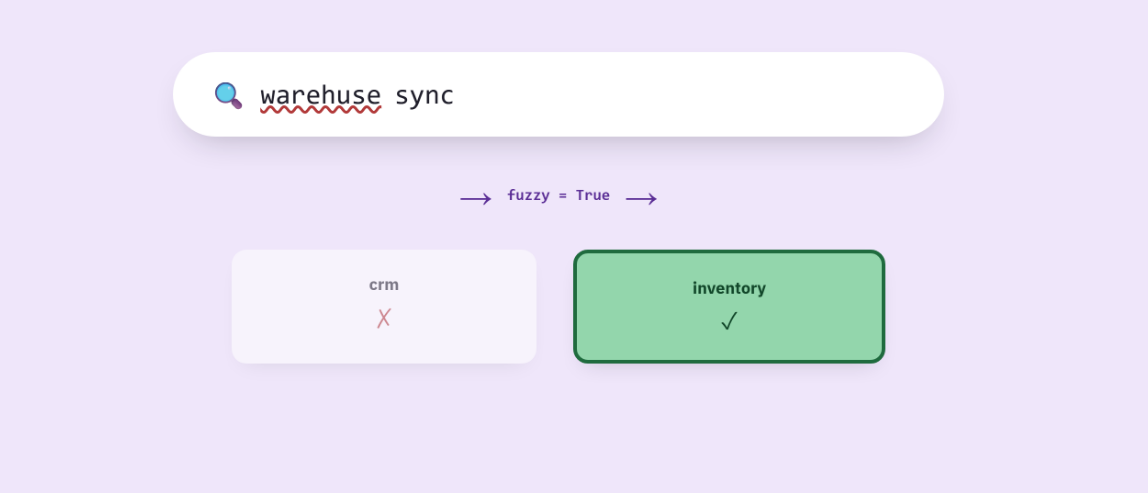
Fuzzy matching compares phrases by spelling similarity and offers shut matches partial credit score. With fuzzy matching enabled, warehuse is shut sufficient to warehouse for the stock doc to attain larger.
The similarity threshold issues. Set it too low and unrelated phrases can match; set it too excessive and customary typos nonetheless fail. Checks primarily based on actual queries present higher thresholds than a handful of invented spelling errors.
A desk divided throughout a web page boundary
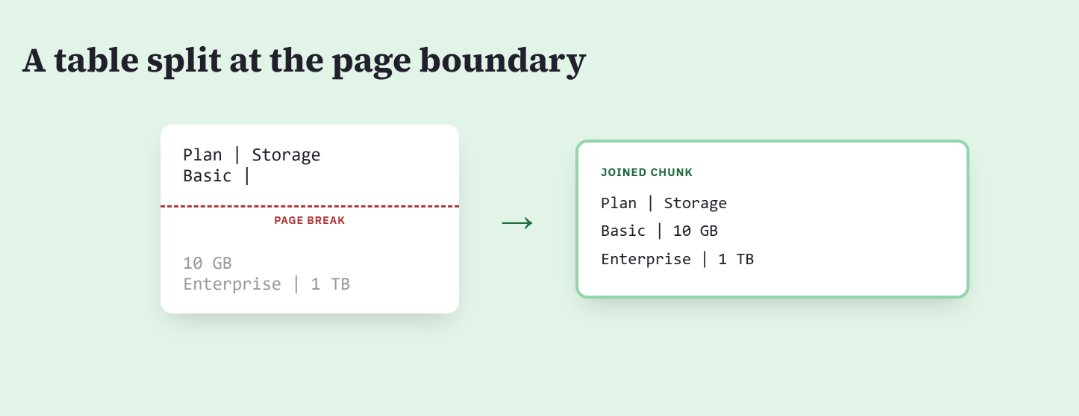
Some PDF extraction instruments create one chunk per web page. If a desk continues onto the subsequent web page, the primary chunk could comprise a row label whereas the second incorporates its worth.
Picture by Writer | Claude Design.
The primary chunk incorporates all 3 question tokens: fundamental, plan, and storage, so it ranks first. Its textual content ends after Primary |. The worth, 10 GB, is within the subsequent chunk and will by no means attain the language mannequin.
This correction belongs within the ingestion course of. Detect desk fragments and be a part of associated pages earlier than creating searchable chunks.
Becoming a member of each pair of pages would create outsized chunks and blend unrelated textual content. Restrict the rule to detected tables or carry sufficient neighboring content material ahead to protect every row.
Check the proof inside every end result
The returned doc ID confirms which supply ranked first. An proof examine confirms whether or not its chunk incorporates sufficient info to reply the query. The divided desk demonstrates the distinction: a piece from the proper limits doc may comprise Primary and Storage whereas leaving 10 GB on the subsequent web page.
Add an proof examine to every check. The examine names the phrases or values that should seem within the retrieved textual content for the language mannequin to provide a supported reply.
The returns-policy check ought to require each the present doc ID and the present worth:
The desk check ought to require the row label and its worth in the identical retrieved chunk:
These assertions additionally make failures simpler to diagnose.
A flawed ID factors to rating or filtering. An accurate ID with lacking textual content factors to extraction or chunking. An accurate ID with the required proof offers the era step sufficient supply materials to reply, though the ultimate reply nonetheless wants its personal analysis.
In case your retriever returns a number of chunks, apply the identical examine to the mixed textual content handed to the language mannequin. The evaluated textual content will then match the context the mannequin receives.
···
What the 4 checks catch
Operating the 4 corrupted inputs in opposition to the fundamental retriever produces 4 failures. After the matching correction is enabled for every case, all 4 return the anticipated doc.
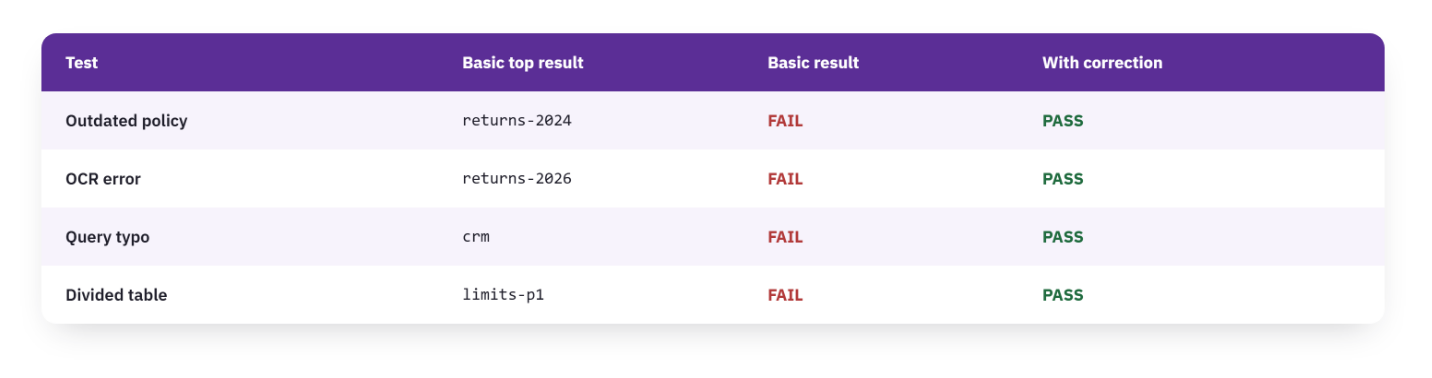
The fixes are small:
-
use doc dates to resolve a tie, normalize recognized OCR errors,
-
permit shut spelling matches, and
-
protect desk rows throughout ingestion.
Every one addresses a distinct trigger. The separate check outcomes establish which safety is lacking.
Run these checks alongside a typical relevance analysis. Relevance checks measure whether or not retrieval works on anticipated inputs. Fault-injection checks measure whether or not it nonetheless works after a sensible defect is added to the question or doc assortment.
The 4 instances are a beginning check set. When manufacturing returns the flawed doc, add a regression check: a repeatable examine that confirms the bug stays fastened after later code adjustments.
···
Thanks for studying!
My identify is Sara Nóbrega and I’m an AI engineer with background in physics.