My company buys editorial placements from impartial publishers. The provider checklist is just a little over 10,000 web sites, each certainly one of them an organization that sends us invoices, and retaining that checklist clear is the least glamorous drawback we now have. It is usually the one which prices cash when it goes unsuitable. A replica provider document is the way you pay the identical bill twice, and break up data imply break up worth historical past, so the speed you negotiated final yr is filed underneath a spelling no one searches for.
Since January we now have been syncing an exterior market catalog into our inside system via its API, on prime of a decade of guide entry by account managers and spreadsheets that arrive by e mail. The identical web site now exhibits up as solartravelmag.com, https://www.solartravelmag.com/, weblog.solartravelmag.com, and on a foul day SolarTravelMag.COM with a monitoring parameter hooked up. One market we sync is upfront that its listed costs match actuality about 90% of the time, which is trustworthy of them, and which implies cross-checking costs between sources is obligatory. Cross-checking solely works if two rows describe the identical web site. That’s entity decision, an issue with formal concept going again to Fellegi and Sunter in 1969 [1], and it has a property the tutorials not often lead with: the string matching is the straightforward half. Deciding what to do with the scores is the job.
This text walks via the pipeline that cleaned our checklist, run finish to finish on an artificial rebuild of it, with floor reality labels so each precision declare beneath is checkable. The punchline, in a single sentence: two boring deterministic levels eliminated 76% of the duplicates totally free, the fuzzy matcher scored 33.7 million pairs in two seconds, and no threshold existed that might safely merge what remained. The matcher’s actual output is a ranked evaluate queue, not a set of merges.
An artificial copy of an actual mess
I can not publish our vendor checklist, so I rebuilt one with the identical illnesses. Seven thousand invented writer manufacturers obtained domains throughout a practical unfold of endings, after which I corrupted the checklist the way in which ours will get corrupted: 2,429 floor variants (schemes, www prefixes, random casing, paths, monitoring parameters), 888 subdomain rows like weblog. and m., 529 country-domain siblings similar to model.com sitting subsequent to model.de, and 505 one-keystroke entry typos. I additionally planted 180 traps: domains one edit away from an current model that belong to a special vendor solely, as a result of the actual net is filled with near-name neighbors and any trustworthy check set wants them.
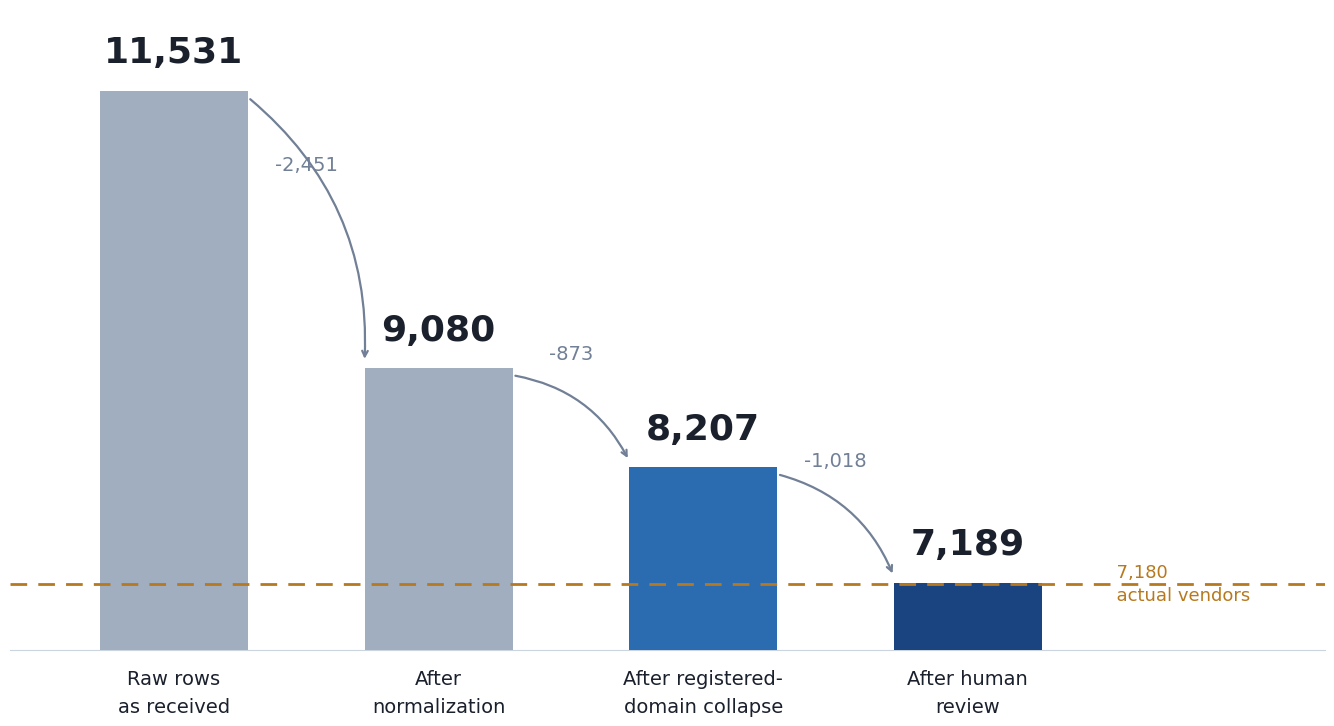
The result’s 11,531 rows describing 7,180 precise distributors. The generator is fifty traces of phrase lists and deliberate vandalism; the corruption recipe above is sufficient to rebuild it. Every part ran on Python 3.12 with RapidFuzz 3.14.5 [2] and tldextract 5.3.2 [3] on a single-vCPU cloud sandbox, so not one of the timings beneath required critical {hardware}.
The boring levels do a lot of the work
Stage one is normalization, and it’s intentionally dumb: lowercase, strip the scheme, lower the trail and question string, drop a number one www.
That took the checklist from 11,531 rows to 9,080 distinctive hosts in 0.03 seconds. No mannequin, no scores, 2,451 duplicates gone.
Stage two collapses subdomains, and that is the place individuals who break up on dots get damage. The registered area of weblog.solartravelmag.com is solartravelmag.com, however the registered area of solartravelmag.co.uk just isn’t co.uk, and the one solution to know that’s the Public Suffix Checklist [4], a maintained catalog of each suffix underneath which the general public can register names. The tldextract library wraps it:
One other 873 hosts collapsed, leaving 8,207 registered domains. Two deterministic levels, zero judgment calls, and three,324 of the 4,351 duplicate rows are already gone. In case you take one quantity from this text, take that one: 76% of the issue by no means wanted a similarity rating in any respect.
What’s left is the onerous quarter. The bottom reality says 1,135 true duplicate pairs are nonetheless hiding in these 8,207 domains, break up data that solely a cross-domain comparability can discover: the entry typos and the country-domain siblings.
Brute power is okay, and blocking nonetheless earns its preserve
8,207 domains make 33.7 million attainable pairs, which sounds just like the second to achieve for intelligent indexing. It isn’t, a minimum of not for velocity. RapidFuzz computes the total similarity matrix in a single name:
Two seconds, 67 MB. On an inventory this dimension, brute power is a espresso sip.
Blocking issues for 2 different causes. First, scale: at 100,000 distributors the identical matrix is 10 billion cells and 10 GB, and the espresso sip turns into an outage. Second, and underrated: a scored matrix just isn’t a to-do checklist. You need candidate pairs you may rank and route, not a wall of numbers. So I blocked anyway, evaluating solely domains that share a key:
Blocking has a worth, and you must measure it as an alternative of hoping. With solely the two-character prefix key, the candidate set caught 93.0% of the true duplicate pairs; typos that hit the primary two letters escaped their block. Including the last-three-characters key raised that to 99.8%, at the price of rising the candidate set from 864,600 pairs to 1,690,124. Scoring all of them took 1.1 seconds. Precisely two true pairs slipped previous each keys. On an actual checklist you’ll not have floor reality, so estimate blocking recall on a labeled pattern earlier than trusting it.
Two humps that refuse to separate
Right here is the place the tutorial model of this story ends and the operational model begins. I scored each candidate pair and break up the histogram by floor reality.
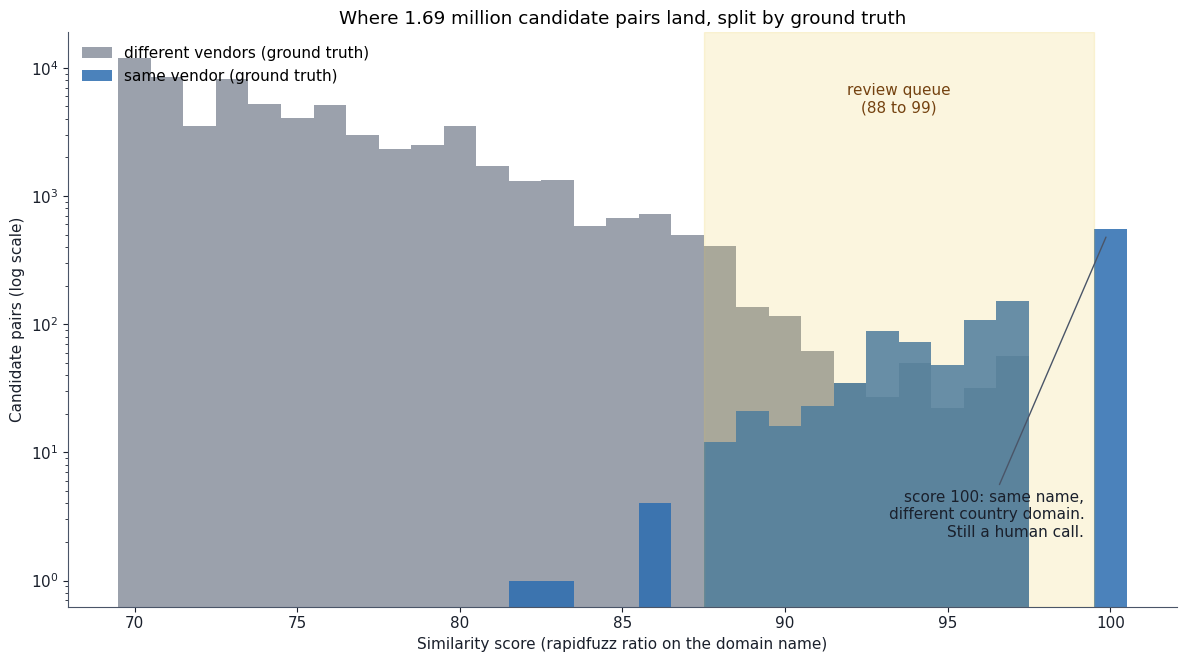
Each candidate pair from the blocking stage, scored with rapidfuzz and coloured by whether or not the 2 domains belong to the identical vendor. True duplicates and totally different distributors occupy the identical rating vary between 88 and 97, which is why no auto-merge threshold is protected.
Beneath a rating of 80 the information is clear: not one true duplicate lives down there. Above 97 it’s clear the opposite method, with one monumental catch I’ll get to. The area between 88 and 97 is a real combination, and it’s a combination for a structural motive, not a tuning one. A one-keystroke entry typo of a 14-character area scores within the low 90s. A genuinely totally different vendor whose title is one edit away from yours additionally scores within the low 90s. The string can not let you know which state of affairs you might be in, as a result of the 2 conditions are the identical string occasion with totally different house owners behind them.
The sweep makes it concrete. Auto-merging at 85 has a precision of 0.345, that means two of each three merges are unsuitable. At 90, precision reaches 0.764, so one merge in 4 remains to be unsuitable. At 95 you get precision 0.895 and have already dropped recall to 0.738. Solely at 98 does precision hit 1.0, with recall at 0.485.
And now the catch. Each single pair scoring in that good zone, all 551 of them, is similar title underneath two totally different nation domains: model.com subsequent to model.de or model.co.uk. The scorer is for certain the strings match, and the strings do match, however whether or not model.de is the German arm of the identical writer or an unrelated firm that grabbed the identical phrase is data about firms, and no quantity of certainty in regards to the textual content provides it. In our actual checklist each instances happen. So the one area the place the matcher isn’t unsuitable in regards to the textual content is the area the place being proper in regards to the textual content settles nothing. These pairs go to a human, by rule:
Discover what’s lacking: a merge department. After the deterministic levels, nothing that remained was protected to merge robotically.
Purchase recall with minutes, not thresholds
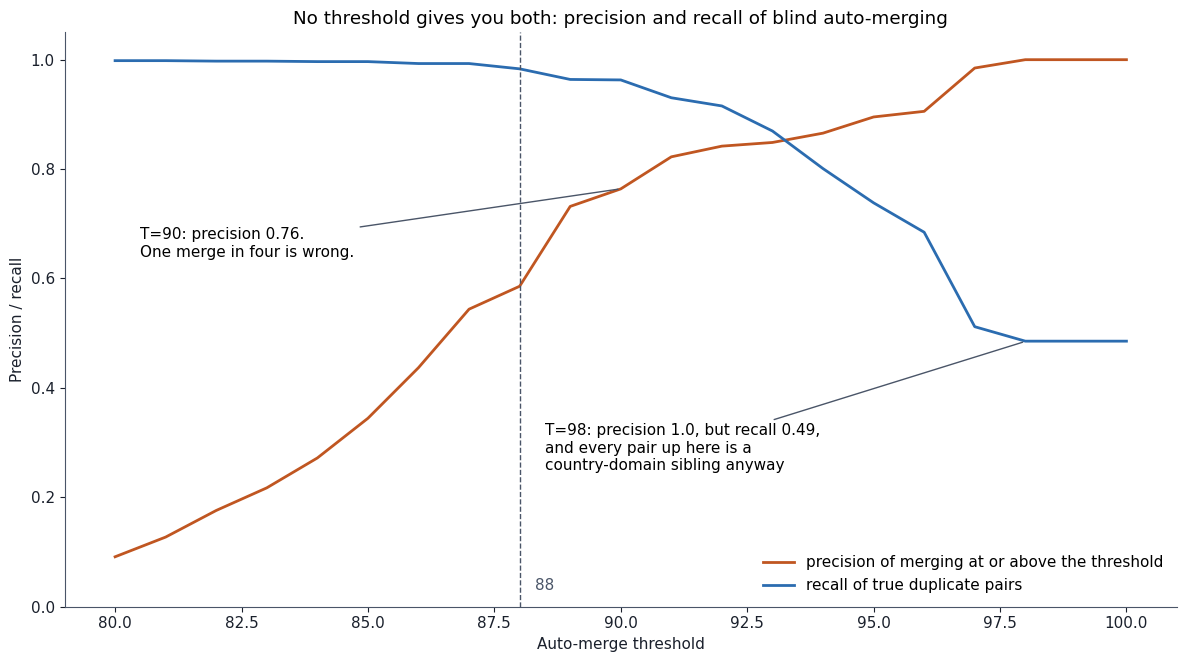
What blind auto-merging prices at each threshold. Precision solely reaches 1.0 at a rating of 98, by which level recall has fallen beneath half, and the pairs remaining at that stage are country-domain siblings that want a human resolution anyway.
Since no threshold merges safely, the brink’s actual job modifications: it sizes the evaluate queue. That turns a statistics knob right into a staffing resolution, and the numbers make the commerce express. The 88 to 99 band accommodates 1,354 pairs, of which 565 are true duplicates. Add the 551 forced-review nation siblings and a reviewer faces 1,905 pairs. At six pairs a minute, that’s simply over 5 hours: one working day to resolve a decade of vendor mess. Widening the band to 85 provides 1,378 extra pairs, roughly 4 further hours, and recovers precisely 15 further true duplicates. Dropping the ground to 80 balloons the queue previous 30 hours and recovers two extra. Whoever owns the provider funds can now select a degree on that curve whereas figuring out exactly what every hour buys.
I simulated each endings. The evaluate path, with the reviewer resolving the queue accurately, lands at 7,189 entities in opposition to a floor reality of seven,180, having repaired 1,116 of the 1,135 duplicate relationships. The 19 misses are 17 pairs that scored between 80 and 87 and the two pairs blocking misplaced. The opposite ending is the one the tooling makes temptingly straightforward: blind auto-merge at 90 and go dwelling. That run produced 6,914 entities, and 282 of them are data fusing two or extra genuinely totally different distributors. In accounts payable phrases, 282 suppliers whose worth historical past is now contaminated with another person’s charges, hooked up to a document that pays someone. A messy checklist prices you comparisons. A confidently unsuitable checklist prices you transfers.
Two habits made the evaluate day itself low cost. Type the queue by cash, so pairs involving costly placements get eyes first and the lengthy tail can anticipate a sluggish Friday. And make each merge reversible: preserve each supply rows, write a merge log, by no means overwrite. Half the worth of a human within the loop disappears if her errors are everlasting too.
What transfers to your checklist
Nothing above is restricted to publishers. Vendor names, buyer accounts, and affiliate accomplice lists fail in the identical shapes: floor noise that normalization kills, hierarchy {that a} canonical type collapses, and a residue of near-matches the place the string alone underdetermines the reply. When you might have extra columns than I used right here, spend them within the evaluate interface somewhat than the rating. A shared contact e mail or financial institution element turns a 91 right into a certainty in two seconds of human consideration; folding it right into a composite rating simply strikes the anomaly someplace tougher to see. And in case your entities are domains, respect the Public Suffix Checklist. Splitting on dots is how co.uk turns into your largest provider.
Conclusion
The pipeline that cleaned the checklist is unglamorous. Normalize onerous, collapse to registered domains, block on two keys, rating every little thing as soon as, and route by rule: certainties have been already collapsed, impossibilities keep ignored, and the blended center turns into a queue an individual can end in a day. On quick strings like domains, a similarity rating is an argument for a human to weigh, and the information right here exhibits it plainly: three in 4 merges unsuitable at 85, one in 4 unsuitable at 90, and perfection arriving solely within the actual area the place the string stops being the query. Rank the queue, dimension it to the hours you might have, preserve the merges reversible, and let the deterministic levels do the bragging.
All charts on this article have been generated by the writer with matplotlib. No AI picture instruments have been used.
References
[1] I. Fellegi and A. Sunter, A Principle for Report Linkage (1969), Journal of the American Statistical Affiliation
[2] M. Bachmann, RapidFuzz: speedy fuzzy string matching in Python (2026), GitHub
[3] J. Kurkowski, tldextract (2026), GitHub
[4] Mozilla Basis, Public Suffix Checklist (2026), publicsuffix.org