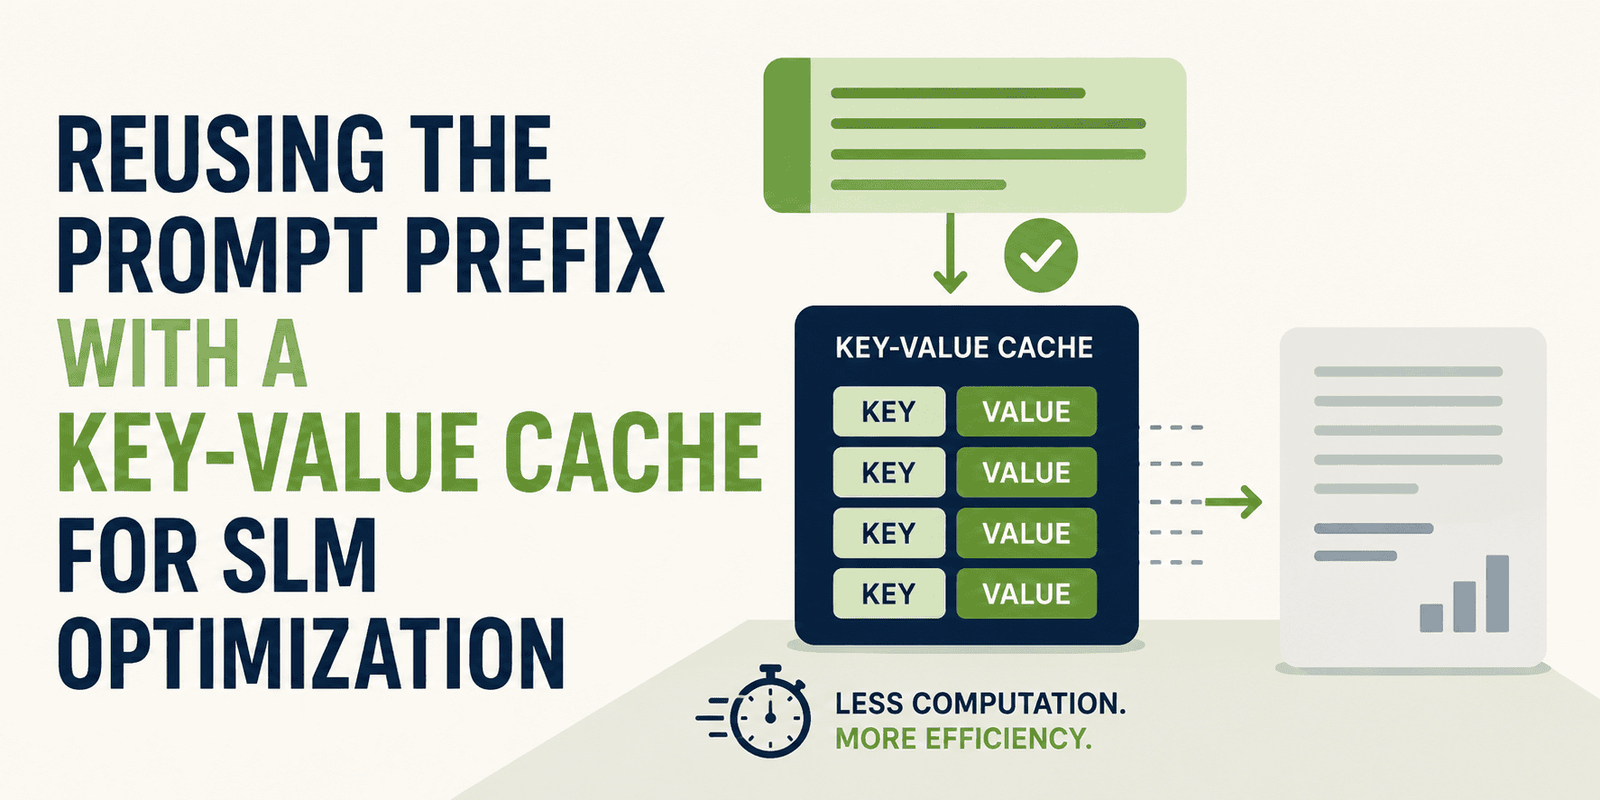
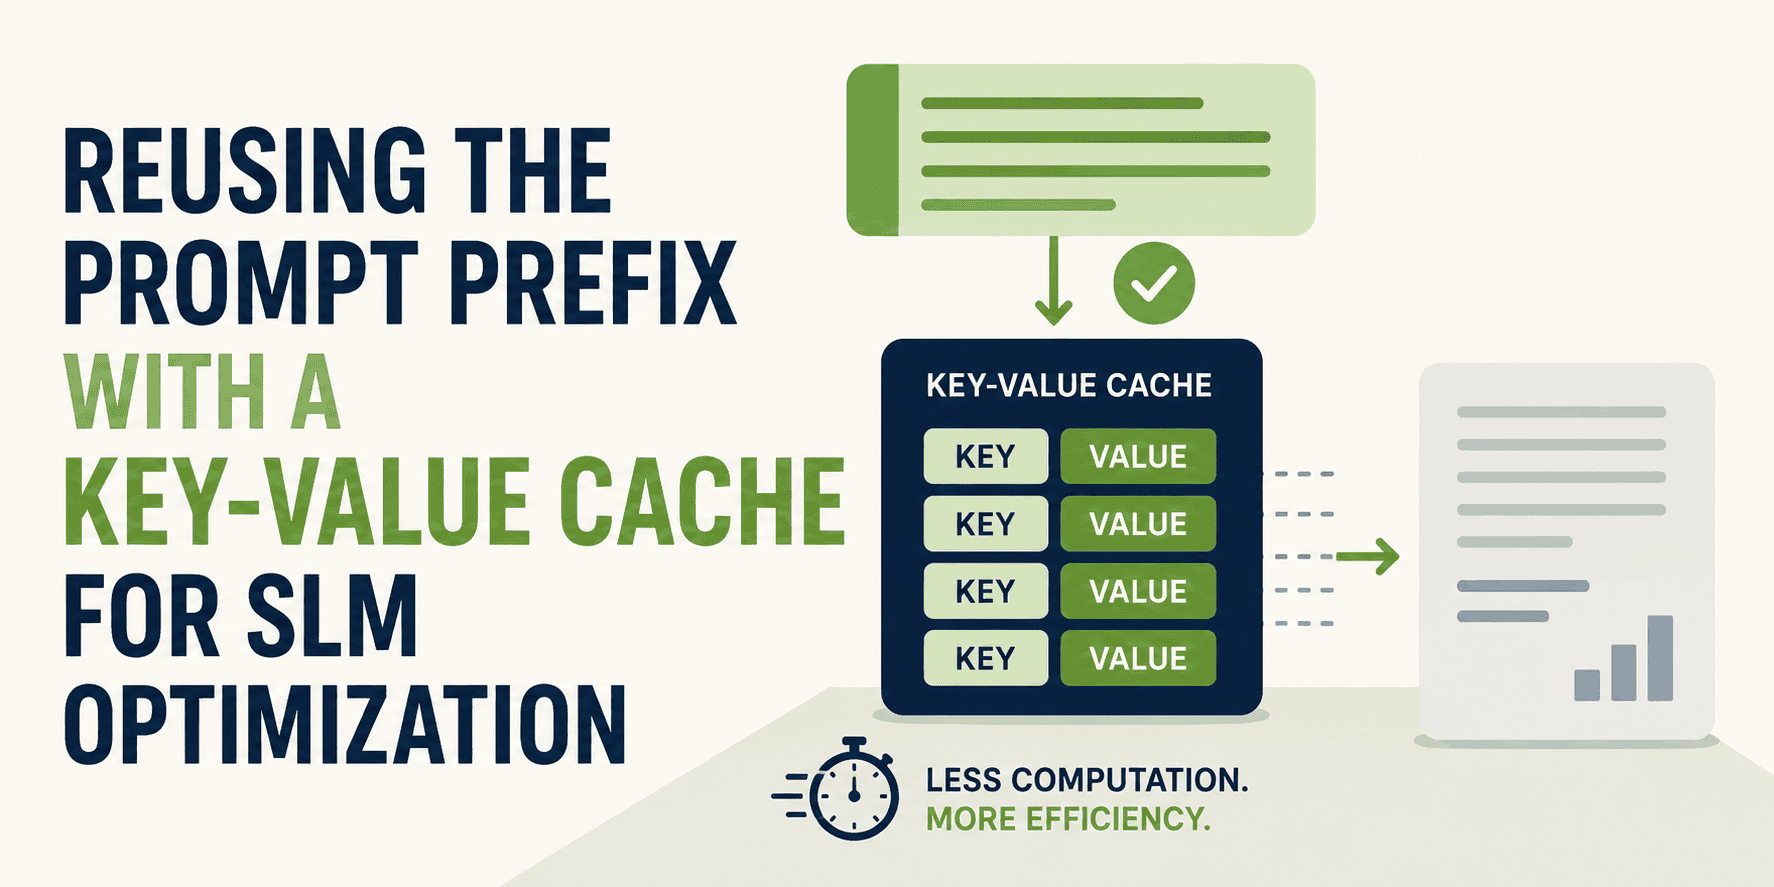
In a earlier article we mentioned constraining output house for small language mannequin (SLM) slim automation optimization. We talked about on the time that this was the primary in a brief sequence of SLM optimization technique articles. We are actually on the second of these. This time we are going to deal with the reuse of the immediate prefix with a key-value cache. Let’s not waste any additional time on the niceties and get proper to it as an alternative.
As in our earlier article, all benchmarks beneath use Qwen2.5-0.5B-Instruct in float16 via Hugging Face Transformers, working on an M2 Macbook Air with 24GB RAM and a 16-core Neural Engine.
First, ensure you arrange a Python atmosphere and set up your necessities:
pip set up torch transformers speed upWe’ll proceed to make use of the help ticket framing from our first article.
Why Reuse the Immediate Prefix with a Key-Worth Cache
Slender automation prompts are comparatively static. A process instruction, a taxonomy definition, and some examples make up the majority of the tokens, and solely a brief immediate tail adjustments from merchandise to merchandise. In case your instruction block runs to a few hundred tokens and every ticket provides twenty or thirty, then the overwhelming majority of each immediate is byte-for-byte similar to the final one. It is clearly wasteful to be recomputing all of it, for each layer, on each name.
Transformers compute a key and a worth vector for every token at every layer, and these rely solely on the tokens to the left. Because of this for a hard and fast prefix, they’re similar on each name. Computing them as soon as and holding onto them shrinks the per-item pre-fill down to simply the tokens that truly modified.
Re-encoding Each Ticket
First, the baseline: a sensible few-shot immediate, re-encoded in full for each ticket. The constrained scoring trick from our earlier article is carried ahead right here, so the choice is a single ahead move and the one factor left to optimize is the pre-fill. Word that the chat template is written out by hand slightly than going via apply_chat_template(), as a result of the following script wants to separate the immediate at a recognized boundary.
import os
import time
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM

MODEL_ID = "Qwen/Qwen2.5-0.5B-Instruct"

torch.set_num_threads(os.cpu_count() or 1)

tokenizer = AutoTokenizer.from_pretrained(MODEL_ID)
mannequin = AutoModelForCausalLM.from_pretrained(MODEL_ID, dtype=torch.float32)
mannequin.eval()

# our toy information to categorise (600 information)
LABELS = ["billing", "technical", "account"]
tickets = [
    "My card was charged twice for the same invoice.",
    "The mobile app crashes whenever I open the settings page.",
    "I need to change the email address on my profile.",
] * 200

# constrained scoring, carried over from the earlier article: the immediate ends on the
# begin of the assistant flip, so evaluating the logits of every label's FIRST token
# is sufficient to decide a winner, supplied these first tokens are distinct
label_first_ids = [tokenizer.encode(label, add_special_tokens=False)[0] for label in LABELS]
assert len(set(label_first_ids)) == len(LABELS), (
    "Labels share a primary token; rating full label sequences as an alternative."
)
label_first_ids = torch.tensor(label_first_ids, machine=mannequin.machine)

SYSTEM_PROMPT = """You classify buyer help tickets into precisely one class.

Classes:
- billing: funds, invoices, refunds, expenses, subscription prices
- technical: crashes, errors, efficiency issues, damaged options
- account: profile adjustments, login entry, permissions, account deletion

Examples:
Ticket: I used to be billed twice in March.
Class: billing
Ticket: The dashboard by no means finishes loading.
Class: technical
Ticket: Please take away my outdated telephone quantity from my profile.
Class: account
Ticket: My promo code was rejected at checkout.
Class: billing
Ticket: Exporting to CSV throws a 500 error.
Class: technical
Ticket: I can not reset my password.
Class: account
"""

# the chat template is written out by hand so the immediate might be break up at a recognized
# token boundary; that is the precise ChatML structure Qwen2.5-Instruct expects
prefix_text = f"<|im_start|>systemn{SYSTEM_PROMPT}<|im_end|>n"


def suffix_text(ticket):
    return (
        f"<|im_start|>usernTicket: {ticket}nCategory:<|im_end|>n"
        f"<|im_start|>assistantn"
    )


def encode(textual content):
    return tokenizer(textual content, add_special_tokens=False)["input_ids"]


# the break up needs to be token-clean: encoding the 2 halves individually should give
# precisely the identical ids as encoding the entire immediate in a single go, or the cached keys
# within the subsequent script is not going to line up with what the mannequin would in any other case have seen
_probe = suffix_text(tickets[0])
assert encode(prefix_text) + encode(_probe) == encode(prefix_text + _probe), (
    "Prefix/suffix break up isn't token-clean; transfer the boundary."
)

prefix_len = len(encode(prefix_text))
full_len = prefix_len + len(encode(_probe))
print(f"Static prefix size: {prefix_len} tokens")
print(f"Full immediate size:   {full_len} tokens ({100 * prefix_len / full_len:.0f}% of it static)")

# time inference
baseline_predictions = []
begin = time.time()

for n, ticket in enumerate(tickets, begin=1):

    # this loop runs for minutes on CPU, so report progress slightly than sitting silent
    if n % 100 == 0:
        print(f"  {n}/{len(tickets)} tickets ({(time.time() - begin) / n:.2f}s every)", flush=True)

    full = tokenizer(
        prefix_text + suffix_text(ticket), add_special_tokens=False, return_tensors="pt"
    ).to(mannequin.machine)
    with torch.no_grad():
        logits = mannequin(**full).logits[0, -1, :]
    baseline_predictions.append(LABELS[int(logits[label_first_ids].argmax())])

duration_full = time.time() - begin

# output process metrics
print(f"Recomputing the total immediate each time: {duration_full:.2f} seconds")
print(f"  ({1000 * duration_full / len(tickets):.1f} ms per ticket)")
Output:
Loading weights: 100%|████████████████████████████████████████████████████████████████████| 290/290 [00:01<00:00, 156.40it/s]
Static prefix size: 145 tokens
Full immediate size:   167 tokens (87% of it static)
  100/600 tickets (0.31s every)
  200/600 tickets (0.30s every)
  300/600 tickets (0.30s every)
  400/600 tickets (0.31s every)
  500/600 tickets (0.31s every)
  600/600 tickets (0.31s every)
Recomputing the total immediate each time: 184.85 seconds
  (308.1 ms per ticket)
Reusing the Immediate Prefix
We now run the prefix via the mannequin precisely as soon as, preserve the ensuing cache, and feed every merchandise solely its personal tokens. This continues in the identical script, so the mannequin, the tokenizer, the immediate halves, and the baseline timing are all nonetheless in scope.
import os
import time
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM, DynamicCache

MODEL_ID = "Qwen/Qwen2.5-0.5B-Instruct"

torch.set_num_threads(os.cpu_count() or 1)

tokenizer = AutoTokenizer.from_pretrained(MODEL_ID)
mannequin = AutoModelForCausalLM.from_pretrained(MODEL_ID, dtype=torch.float32)
mannequin.eval()

# our toy information to categorise (600 information)
LABELS = ["billing", "technical", "account"]
tickets = [
    "My card was charged twice for the same invoice.",
    "The mobile app crashes whenever I open the settings page.",
    "I need to change the email address on my profile.",
] * 200

# constrained scoring, carried over from the earlier article: the immediate ends on the
# begin of the assistant flip, so evaluating the logits of every label's FIRST token
# is sufficient to decide a winner, supplied these first tokens are distinct
label_first_ids = [tokenizer.encode(label, add_special_tokens=False)[0] for label in LABELS]
assert len(set(label_first_ids)) == len(LABELS), (
    "Labels share a primary token; rating full label sequences as an alternative."
)
label_first_ids = torch.tensor(label_first_ids, machine=mannequin.machine)

SYSTEM_PROMPT = """You classify buyer help tickets into precisely one class.

Classes:
- billing: funds, invoices, refunds, expenses, subscription prices
- technical: crashes, errors, efficiency issues, damaged options
- account: profile adjustments, login entry, permissions, account deletion

Examples:
Ticket: I used to be billed twice in March.
Class: billing
Ticket: The dashboard by no means finishes loading.
Class: technical
Ticket: Please take away my outdated telephone quantity from my profile.
Class: account
Ticket: My promo code was rejected at checkout.
Class: billing
Ticket: Exporting to CSV throws a 500 error.
Class: technical
Ticket: I can not reset my password.
Class: account
"""

# the chat template is written out by hand so the immediate might be break up at a recognized
# token boundary; that is the precise ChatML structure Qwen2.5-Instruct expects
prefix_text = f"<|im_start|>systemn{SYSTEM_PROMPT}<|im_end|>n"


def suffix_text(ticket):
    return (
        f"<|im_start|>usernTicket: {ticket}nCategory:<|im_end|>n"
        f"<|im_start|>assistantn"
    )


def encode(textual content):
    return tokenizer(textual content, add_special_tokens=False)["input_ids"]


# the break up needs to be token-clean: encoding the 2 halves individually should give
# precisely the identical ids as encoding the entire immediate in a single go, or the cached keys
# is not going to line up with what the mannequin would in any other case have seen
_probe = suffix_text(tickets[0])
assert encode(prefix_text) + encode(_probe) == encode(prefix_text + _probe), (
    "Prefix/suffix break up isn't token-clean; transfer the boundary."
)

prefix = tokenizer(prefix_text, add_special_tokens=False, return_tensors="pt").to(mannequin.machine)
prefix_ids = prefix["input_ids"]
prefix_len = prefix_ids.form[1]
full_len = prefix_len + len(encode(_probe))
print(f"Static prefix size: {prefix_len} tokens")
print(f"Full immediate size:   {full_len} tokens ({100 * prefix_len / full_len:.0f}% of it static)")

# Populate the cache as soon as with the static instruction block
prefix_cache = DynamicCache()
with torch.no_grad():
    mannequin(
        input_ids=prefix_ids,
        attention_mask=torch.ones_like(prefix_ids),
        past_key_values=prefix_cache,
        use_cache=True,
    )


def classify_cached(ticket):
    suffix = tokenizer(
        suffix_text(ticket), add_special_tokens=False, return_tensors="pt"
    ).to(mannequin.machine)
    suffix_ids = suffix["input_ids"]
    suffix_len = suffix_ids.form[1]

    # the masks should cowl the cached prefix in addition to the brand new tokens, and the brand new
    # tokens have to be informed they begin at place prefix_len, not at place 0
    attention_mask = torch.ones((1, prefix_len + suffix_len), machine=mannequin.machine, dtype=torch.lengthy)
    cache_position = torch.arange(prefix_len, prefix_len + suffix_len, machine=mannequin.machine)

    with torch.no_grad():
        out = mannequin(
            input_ids=suffix_ids,
            attention_mask=attention_mask,
            past_key_values=prefix_cache,
            cache_position=cache_position,
            use_cache=True,
        )
        logits = out.logits[0, -1, :]
        label = LABELS[int(logits[label_first_ids].argmax())]

        # roll the cache again so the following ticket begins from the prefix alone
        prefix_cache.crop(prefix_len)

    return label


def classify_full(ticket):
    """Reference path: re-encode the entire immediate, no cache. Used solely to confirm."""
    full = tokenizer(
        prefix_text + suffix_text(ticket), add_special_tokens=False, return_tensors="pt"
    ).to(mannequin.machine)
    with torch.no_grad():
        logits = mannequin(**full).logits[0, -1, :]
    return LABELS[int(logits[label_first_ids].argmax())]


# correctness first: the cached path should agree with the uncached one on each
# distinct ticket, in any other case the speedup beneath is measuring the flawed computation
mismatches = [t for t in dict.fromkeys(tickets) if classify_cached(t) != classify_full(t)]
assert not mismatches, f"Cached path disagrees with full re-encoding on: {mismatches}"
print(f"Cache verified towards full re-encoding on {len(set(tickets))} distinct tickets")

# time inference
predictions = []
begin = time.time()

for n, ticket in enumerate(tickets, begin=1):

    # this loop is quick, however report progress anyway so the 2 scripts look alike
    if n % 100 == 0:
        print(f"  {n}/{len(tickets)} tickets ({(time.time() - begin) / n:.2f}s every)", flush=True)

    predictions.append(classify_cached(ticket))

duration_cached = time.time() - begin

# output process metrics
print(f"Reusing the cached prefix: {duration_cached:.2f} seconds")
print(f"  ({1000 * duration_cached / len(tickets):.1f} ms per ticket)")
Output:
Static prefix size: 145 tokens
Full immediate size:   167 tokens (87% of it static)
Cache verified towards full re-encoding on 3 distinct tickets
  100/600 tickets (0.13s every)
  200/600 tickets (0.13s every)
  300/600 tickets (0.13s every)
  400/600 tickets (0.13s every)
  500/600 tickets (0.13s every)
  600/600 tickets (0.13s every)
Reusing the cached prefix: 80.07 seconds
  (133.5 ms per ticket)
Our baseline script model ran for 184.85 seconds whole, with a mean of ~0.3s for every ticket. The cached immediate prefix model of the script is 80.07 seconds whole, with a mean of 0.13s per ticket. That is an general runtime discount of ~57%. The achieve scales with the ratio between your static and dynamic content material, which is why this method rewards lengthy, detailed instruction blocks slightly than punishing them. And simply to notice: the predictions needs to be similar on each ticket, which is the consequence you need: it is a pure compute optimization, not a change to the mannequin’s habits.
Some additional clarification of the code above:
DynamicCacheholds the per-layer key and worth tensors for the prefix. Passing it aspast_key_valuestells the mannequin these positions are already computed, so the ahead move solely processes the brand new tokens whereas nonetheless attending backward throughout the total context.- Two arguments need to agree with the cache or the outcomes might be deceivingly flawed. The eye masks covers the cached prefix and the brand new tokens, so its width is
prefix_len + suffix_lenregardless that solelysuffix_lenids are handed in.cache_positiontells the mannequin the brand new tokens start at offsetprefix_len, so the rotary embeddings match what the total immediate would have produced. Current variations of Transformers infer the positions from the cache size, however passing them explicitly paperwork the intent and guards towards model drift. - The decision to
prefix_cache.crop(prefix_len)isn’t non-compulsory. The ahead move appends the suffix keys and values to the cache, so with out the crop the second ticket would attend to the primary ticket’s tokens and the cache would develop with out sure. - Cut up the immediate at a clear boundary — the tip of a line, or a chat template delimiter. Tokenizing two halves individually can produce a special token sequence than tokenizing the concatenation if the break up comes mid-word, after which the cached keys not correspond to what the mannequin would have seen. The assertion within the first script checks this instantly.
- Preserve the entire pipeline beneath
torch.no_grad()slightly thantorch.inference_mode(). Tensors created inside inference mode carry a flag that makes them awkward to slice and reassign afterwards, which is precisely whatcrop()does to the cache.
Wrapping Up
This was the second entry in our makes an attempt at optimizing SLMs for slim automation, and our goal approach this time was prefix caching. This method replaces the total and full re-encoding of a static instruction block with a single pre-fill whose key and worth tensors are computed as soon as and reused, leaving us to solely account for the tokens that differ. By implementing it, we get the identical predictions the naive loop produced at a far decrease compute value. The longer and extra detailed our directions develop, the higher the commerce turns into.
A small language mannequin, comparable to our use of a 0.5B parameter mannequin at present, turns into a sensible manufacturing alternative for slim automation as soon as the code round it stops treating each name as an remoted occasion. The immediate is usually the identical each time. As soon as your loop is aware of that, the small mannequin stops being a compromise and begins being the plain reply.
Matthew Mayo (@mattmayo13) holds a grasp’s diploma in laptop science and a graduate diploma in information mining. As managing editor of KDnuggets & Statology, and contributing editor at Machine Studying Mastery, Matthew goals to make complicated information science ideas accessible. His skilled pursuits embrace pure language processing, language fashions, machine studying algorithms, and exploring rising AI. He’s pushed by a mission to democratize data within the information science neighborhood. Matthew has been coding since he was 6 years outdated.