

A brand new take a look at known as DolphinBench checks whether or not an AI assistant’s reminiscence helps it get issues completed. Most reminiscence checks ask the assistant a query in regards to the previous, equivalent to which espresso store Sam likes. The authors say that’s too straightforward, as a result of the query itself hints {that a} reality should be seemed up. DolphinBench offers the assistant a job, equivalent to ordering espresso, and checks that it used the correct reality.
DolphinBench has three simulated folks. Every has about 500,000 tokens of chat historical past. A token is a small piece of textual content, about three quarters of a phrase. Every particular person additionally has 200 duties.
Each job was checked each methods. The assistant needed to cross with the related historical past and fail with out it. Outcomes should additionally report whole value and time, not solely accuracy.
DolphinBench’s personal challenge website calls it a benchmark by Mem0, an organization that sells a reminiscence system. Its announcement submit, written by one of many paper’s authors, reveals a Mem0 setup with the highest rating, 70.67 % of duties. I didn’t reproduce DolphinBench, and I examined no firm’s reminiscence product.
That raises a query for anybody constructing an assistant. If it may possibly repeat a reality, will it use the actual fact when it acts? And what does every approach of giving it reminiscence value? I constructed a a lot smaller take a look at of my very own to search out out.
The take a look at offers a made up challenge supervisor a 12 months of chat historical past, about 40,000 tokens. An assistant then does 30 duties that want one or two information from that historical past, and solutions 30 plain questions on the identical information. I attempted 4 methods of giving the assistant its reminiscence on two fashions, which made 1,260 runs. I logged each run to Weights & Biases (W&B), a device that data experiments. The W&B Report has the charts and tables.
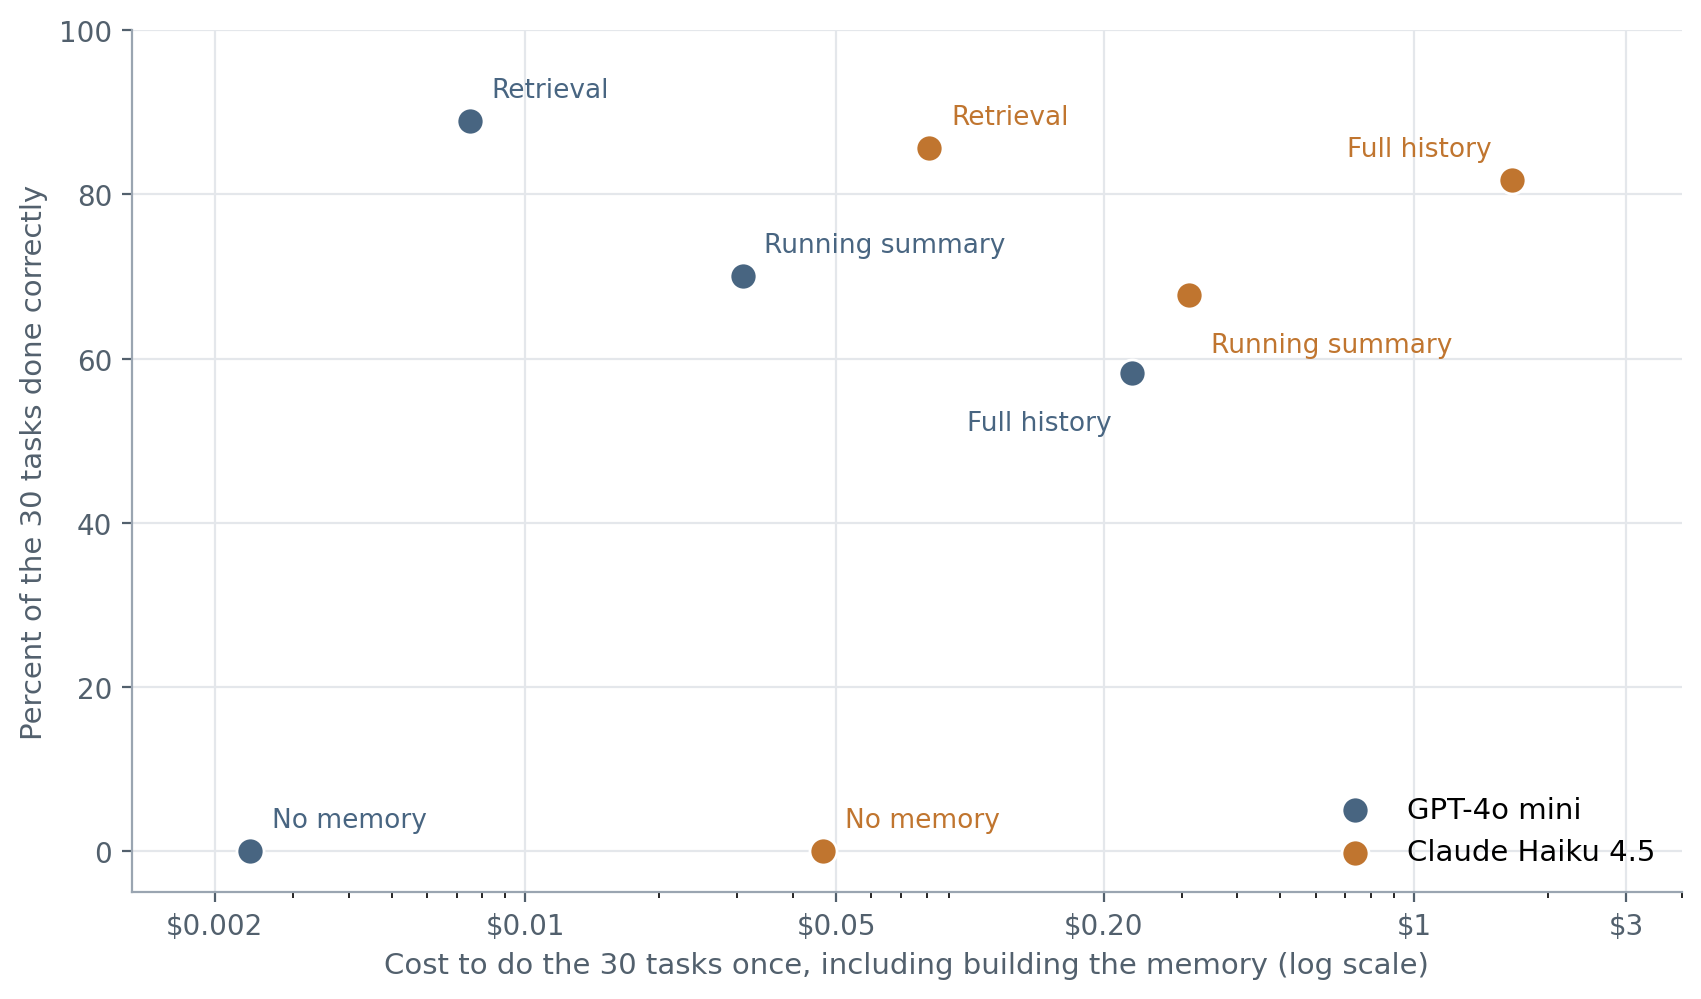
One consequence stunned me. With the entire historical past in entrance of it, GPT-4o mini answered 97 % of the questions accurately, but it did solely 58 % of the duties accurately. A less expensive approach of giving it reminiscence, retrieval, bought 89 % of the duties proper.
By the top, you’ll have a brief script that runs the identical 4 reminiscence designs by yourself historical past and duties.
What does it imply to provide an assistant a reminiscence?
Suppose you rent a brand new assistant, and your entire 12 months of diary sits in a cupboard. There are 3 ways to assist them. You possibly can hand over the entire diary each morning. You possibly can hand over a one web page cheat sheet that somebody wrote from the diary. Or you possibly can pull out the few diary pages that match every request.
These are the three designs I examined, plus a fourth the place the assistant will get nothing. A language mannequin doesn’t keep in mind something between requests. No matter it ought to know must be written into the immediate, which is the textual content you ship with every request.
How was the take a look at constructed?
The particular person is Dana Whitfield, a made up challenge supervisor. Her historical past has 80 entries over a 12 months, about 40,000 tokens in whole. Thirty entries every state one reality, equivalent to her lunch place, a gathering time, a challenge launch date, or who owns a challenge. Eleven extra entries change a type of information later. The remaining 39 entries are bizarre days of chat about printers, trains, and the climate, so the information aren’t straightforward to identify.
A modified reality makes the previous worth the incorrect reply. For instance, the crew lunch order strikes from one restaurant to a different. A mannequin wrote the chat from my checklist of information, and code checked that each reality seems as one actual sentence and nowhere else.
There are 30 duties, one for every reality. Every job is a request that ends in a device name, which is the assistant asking a program to do one motion. The instruments are scheduling a gathering, ordering meals, sending a message, and assigning a job. 9 duties want two information. For instance, “inform the Atlas proprietor the launch date” wants each the proprietor and the date.
A job passes solely when the device name holds the correct values, equivalent to the correct particular person and the correct day and time. The reply textual content is rarely learn. For every reality I additionally ask one plain query, equivalent to “when is Dana’s common one on one with Sam?”, and test that the reply offers the latest worth.
I checked that the duties are honest in two methods. With no reminiscence, no job ought to cross. With precisely the correct snippets handed over, nearly each job ought to cross.
My first strive on the second test failed, with solely about 70 % passing. Some snippets named an individual with out saying their position, and my device directions let fashions write full calendar dates. I mounted each earlier than the actual run.
Which reminiscence designs and fashions did I take a look at?
-
No reminiscence. The assistant sees solely the request.
-
Full historical past. The entire 40,000 token historical past goes into each immediate.
-
Working abstract. A mannequin reads the historical past in 11 steps and rewrites one abstract of about 1,000 phrases because it goes. The assistant sees solely the abstract. Every mannequin wrote its personal abstract as soon as.
-
Retrieval. The historical past is lower into 184 items of about 1,200 characters. Each bit turns into a listing of numbers, known as an embedding, that captures its that means. For every request, the 5 items closest to the request go into the immediate.
The 2 fashions are GPT-4o mini from OpenAI, known as mini from right here on, and Claude Haiku 4.5 from Anthropic, known as Haiku from right here on. Every job ran 3 instances for each design besides full historical past, which ran twice as a result of it prices essentially the most. Every query ran 3 instances, besides full historical past as soon as.
How will you run the take a look at by yourself historical past?
Save the script beneath as memory_test.py in a brand new folder. It wants Python 3.9 or later and an OpenAI key, and no different packages. It holds a small made up historical past of 14 messages and 6 duties, which you’ll change with your personal.
Open a terminal in that folder and run these two instructions. The primary units your key. The second runs the take a look at with gpt-4o-mini. A run makes about 70 calls and prices just a few cents.
That is the output I bought. The historical past is tiny, so full historical past does properly right here, and the numbers solely present that the script works. The experiment beneath makes use of the 80 entry historical past.
How properly did every reminiscence design do?
For every design, I depend the share of the 30 duties completed accurately, averaged over the repeats. I do the identical for the 30 questions. Larger is healthier, and the desk reveals each fashions aspect by aspect.
|
Reminiscence design |
Mini, duties completed (%) |
Mini, questions answered (%) |
Haiku, duties completed (%) |
Haiku, questions answered (%) |
|---|---|---|---|---|
|
No reminiscence |
0.0 |
3.3 |
0.0 |
3.3 |
|
Working abstract |
70.0 |
63.3 |
67.8 |
86.7 |
|
Retrieval |
88.9 |
96.7 |
85.6 |
94.4 |
|
Full historical past |
58.3 |
96.7 |
81.7 |
93.3 |
With no reminiscence, no job handed on both mannequin, so the duties actually do want the reminiscence. Mini guessed in all 90 runs, and each guess had a incorrect or lacking worth. Haiku requested a query as a substitute of appearing in 72 of its 90 runs, regardless that it was advised by no means to ask.
Retrieval did essentially the most duties accurately for mini, 88.9 %. For Haiku it scored 85.6 % in opposition to 81.7 % for full historical past, which is shut sufficient that I might not name a winner. With precisely the correct snippets handed over, each fashions did 96.7 % of the duties, so that’s the ceiling for this take a look at.
Price tells a unique story. The desk reveals what it value to do the 30 duties as soon as, together with constructing the reminiscence, and the median time for one job.
|
Reminiscence design |
Mini, value for 30 duties |
Haiku, value for 30 duties |
Mini, seconds per job |
Haiku, seconds per job |
|---|---|---|---|---|
|
No reminiscence |
$0.002 |
$0.047 |
1.4 |
1.5 |
|
Working abstract |
$0.031 |
$0.311 |
1.3 |
1.7 |
|
Retrieval |
$0.007 |
$0.081 |
2.3 |
2.4 |
|
Full historical past |
$0.232 |
$1.661 |
2.1 |
2.3 |
Full historical past value 20 to 31 instances greater than retrieval. Retrieval was the slowest by somewhat, as a result of it makes two calls, one to search out the items and one for the assistant. Sending 40,000 tokens with each request added little time.
Did the assistant use what it remembered?
Right here I examine two scores for every design. The gray bars present how most of the 30 questions the assistant answered accurately. The coloured bars present how most of the 30 duties it did accurately, utilizing the identical information.
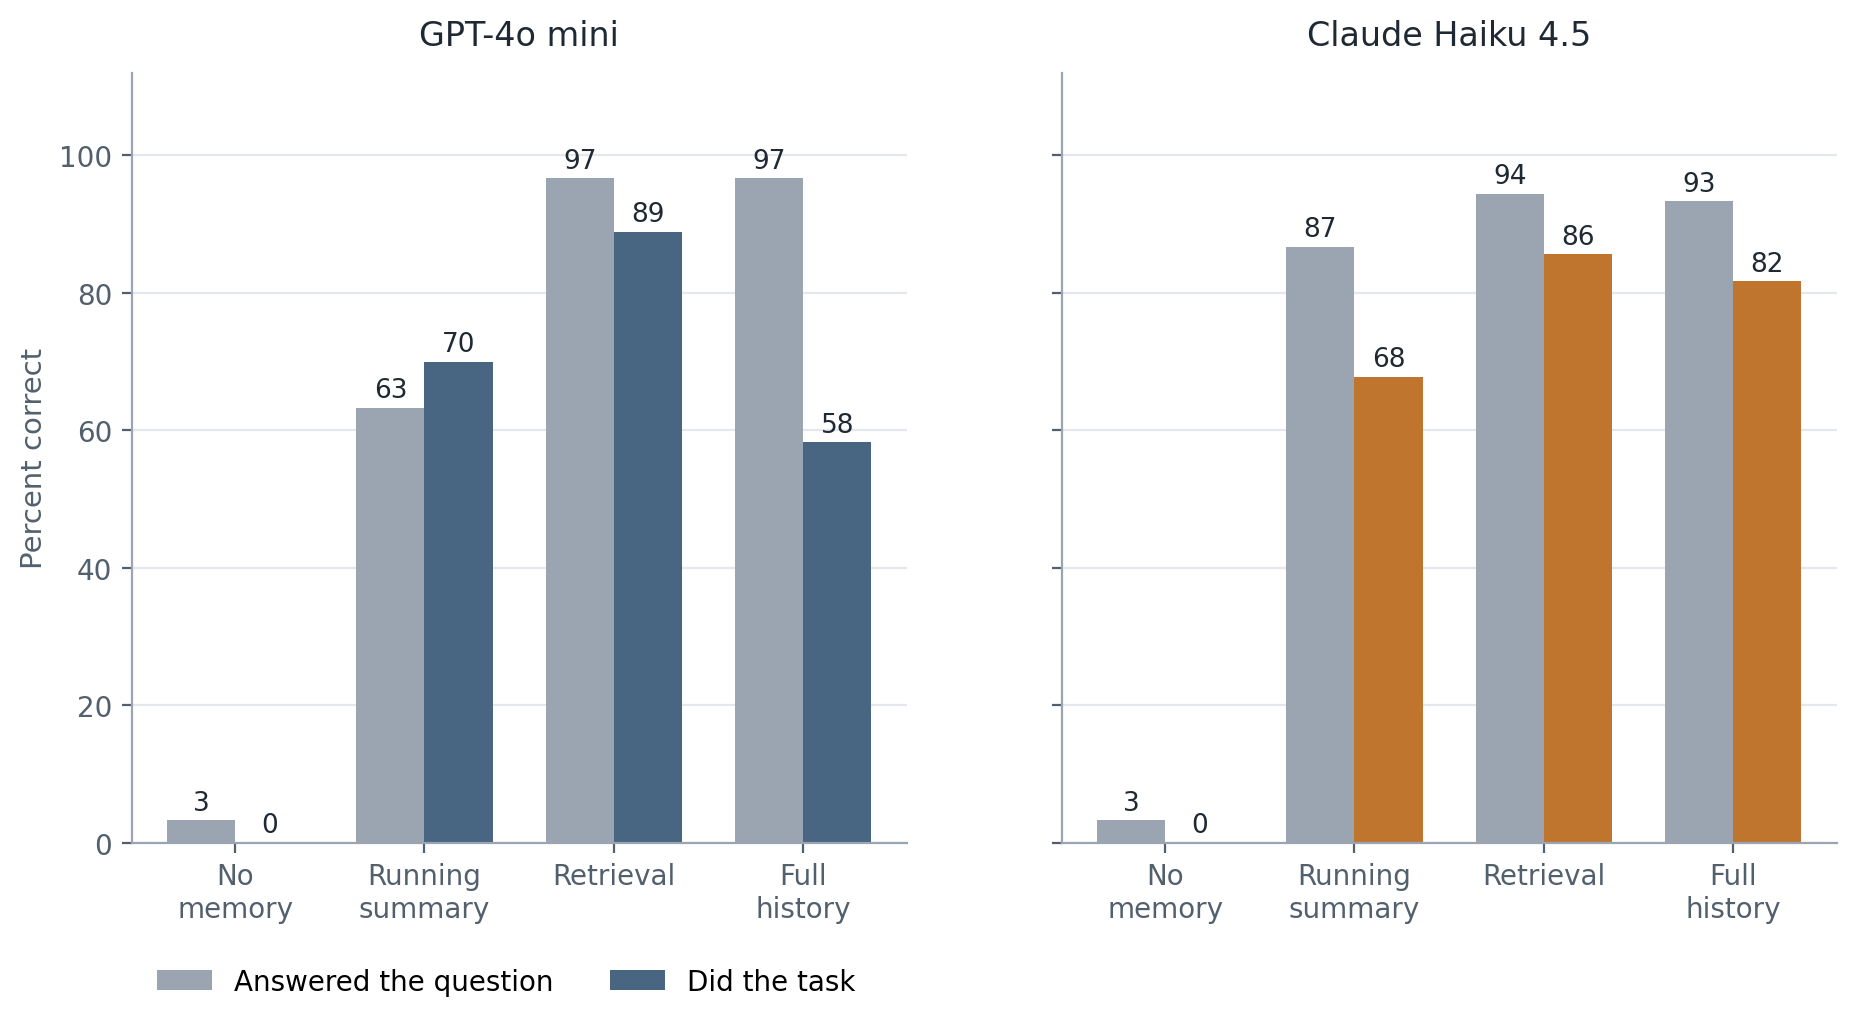
Mini with the total historical past reveals the most important hole, 38 factors. It answered 29 of the 30 questions accurately. But it did solely 58 % of the duties. In 5 of its 13 scheduling misses, it selected the correct time and the incorrect day, equivalent to “Monday 10:00” for a Tuesday 10:00 assembly.
Haiku’s gaps have been smaller, 12 factors with full historical past and 9 with retrieval. With the total historical past, 10 of its 11 missed duties have been questions requested instead of appearing. One instance is asking whether or not to e-book a gathering at a time it had already discovered.
Mini with a working abstract went the opposite approach. It did 70 % of the duties however answered solely 63 % of the questions. So the concept an assistant remembers greater than it makes use of held for 5 of the six setups with reminiscence, and never for all of them.
The place did every design fail?
The clearest failure got here from corrections. Determine 3 splits the duties into the 19 information that by no means modified and the 11 that have been corrected later.
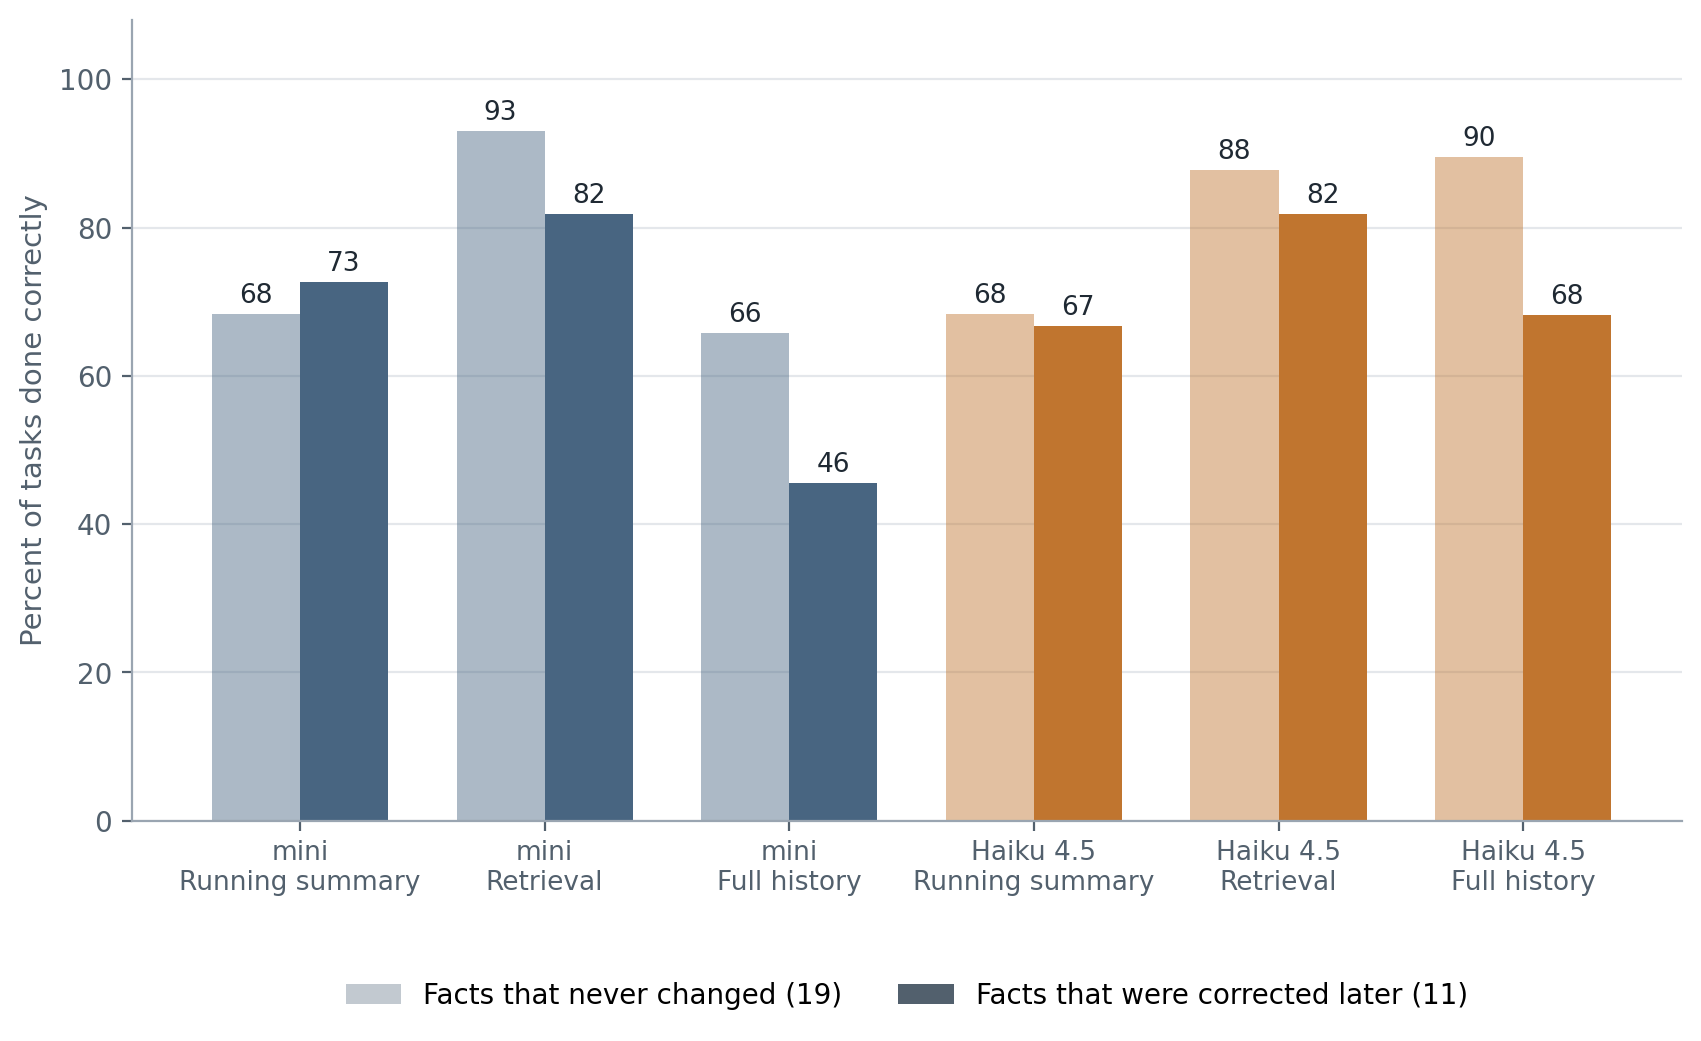
Full historical past retains each the previous message and the brand new one within the immediate, and the mannequin has to note that the later one wins. Mini didn’t at all times. Requested to order lunch for the crew workshop, it ordered from the previous restaurant in each of its runs. A later message had moved the order to a brand new one. With the total historical past it did 46 % of the duties about corrected information, in opposition to 66 % for information that by no means modified.
The working abstract failed another way. It misplaced information whereas it was being written. Mini’s abstract saved the latest worth for 20 of the 30 information, and Haiku’s saved 28. The identical job took mini 122 seconds and $0.019, and Haiku 250 seconds and $0.19.
Retrieval failed solely when it missed. It fetched each piece a job wanted in 93 % of runs. In these runs it handed 95 % of duties for mini and 92 % for Haiku. Within the 6 runs per mannequin the place it missed a bit, nothing handed.
Here’s a query for you. When an assistant is uncertain, would you moderately it asks first or acts and will get corrected? My rating counts a query as a miss, as a result of the duty requested for the motion, and your reply decides how harsh that’s for Haiku.
How do the runs present up in Weights & Biases?
In W&B, every recorded take a look at is named a run. The W&B Report has one run for every mannequin and reminiscence design, a comparability desk, a line chart of the repeats, and the outcomes for every reality. Every run additionally holds each device name and reply, so you possibly can filter for the duties the place the assistant used the previous worth.
The logging occurred after the experiment, from the saved information, so it data what occurred and didn’t change it. The logging script is optionally available, and the take a look at above works with out a W&B account.
Did my take a look at agree with DolphinBench?
I went in anticipating three issues. First, that no reminiscence would fail, because it does in DolphinBench. Second, that doing a job could be more durable than answering a query. Third, that full historical past would set the ceiling, with the opposite designs making an attempt to match it extra cheaply.
The primary two held. No reminiscence handed not one of the duties, and appearing was more durable than answering in 5 of the six setups with reminiscence. The third didn’t maintain. Full historical past was not the ceiling. Retrieval did higher for mini and about as properly for Haiku, at a fraction of the price.
That matches why DolphinBench asks for value and time subsequent to accuracy. In my take a look at, the designs that use reminiscence differed in value by as much as 31 instances, and the rating didn’t observe the price. I can not examine my numbers with DolphinBench’s 70.67 %, as a result of my duties, historical past, and fashions are completely different.
What do you have to take away?
-
Check the motion, not solely the query. Mini answered 97 % of the questions and did 58 % of the duties with the identical historical past.
-
Don’t assume extra reminiscence is healthier. Full historical past value 20 to 31 instances greater than retrieval and didn’t rating greater.
-
Verify what occurs after a correction. Add a later message that modifications a reality, and see which worth the assistant makes use of.
-
Depend what your abstract saved. Verify what number of information survive in it, as a result of mine misplaced 10 of 30 for mini.
-
Verify the duties first. Run them with no reminiscence and with precisely the correct snippets, so a failure is about reminiscence.
My outcomes come from 30 duties on one made up particular person, so that they present what to check, not how each assistant behaves.
What do you have to strive subsequent?
Substitute the bundled historical past within the script with just a few weeks of your personal notes, and write six requests that want a reality from them. Run all 4 designs and examine the duties completed with the questions answered. Then add a message that modifications one reality, and run it once more.
Chosen sources
-
Soumil Rathi, Deshraj Yadav, and Taranjeet Singh. DolphinBench: Mapping the Pareto Frontier of Agent Reminiscence. arXiv, September 21, 2026, revised September 22, 2026. Supply for the three simulated folks, the five hundred,000 token histories, the 200 duties every, and the rule to report value and time. Licensed CC BY 4.0, which permits reuse with credit score.
-
Mem0. Introducing DolphinBench. Announcement submit by Deshraj Yadav, September 22, 2026. Supply for the 70.67 % high rating and for Mem0’s connection to the benchmark.
-
DolphinBench. Venture website. Describes the benchmark as a benchmark by Mem0 and hyperlinks the dataset and code.
-
OpenAI. Operate calling information and Embeddings information. Documentation for device calling and for the retrieval step.
-
Anthropic. Software use with Claude. Documentation for device calling with the Claude Haiku mannequin.
-
Weights & Biases. Observe experiments. W&B documentation, for logging the runs and constructing the report.