Two fashions, one quantity, reverse realities
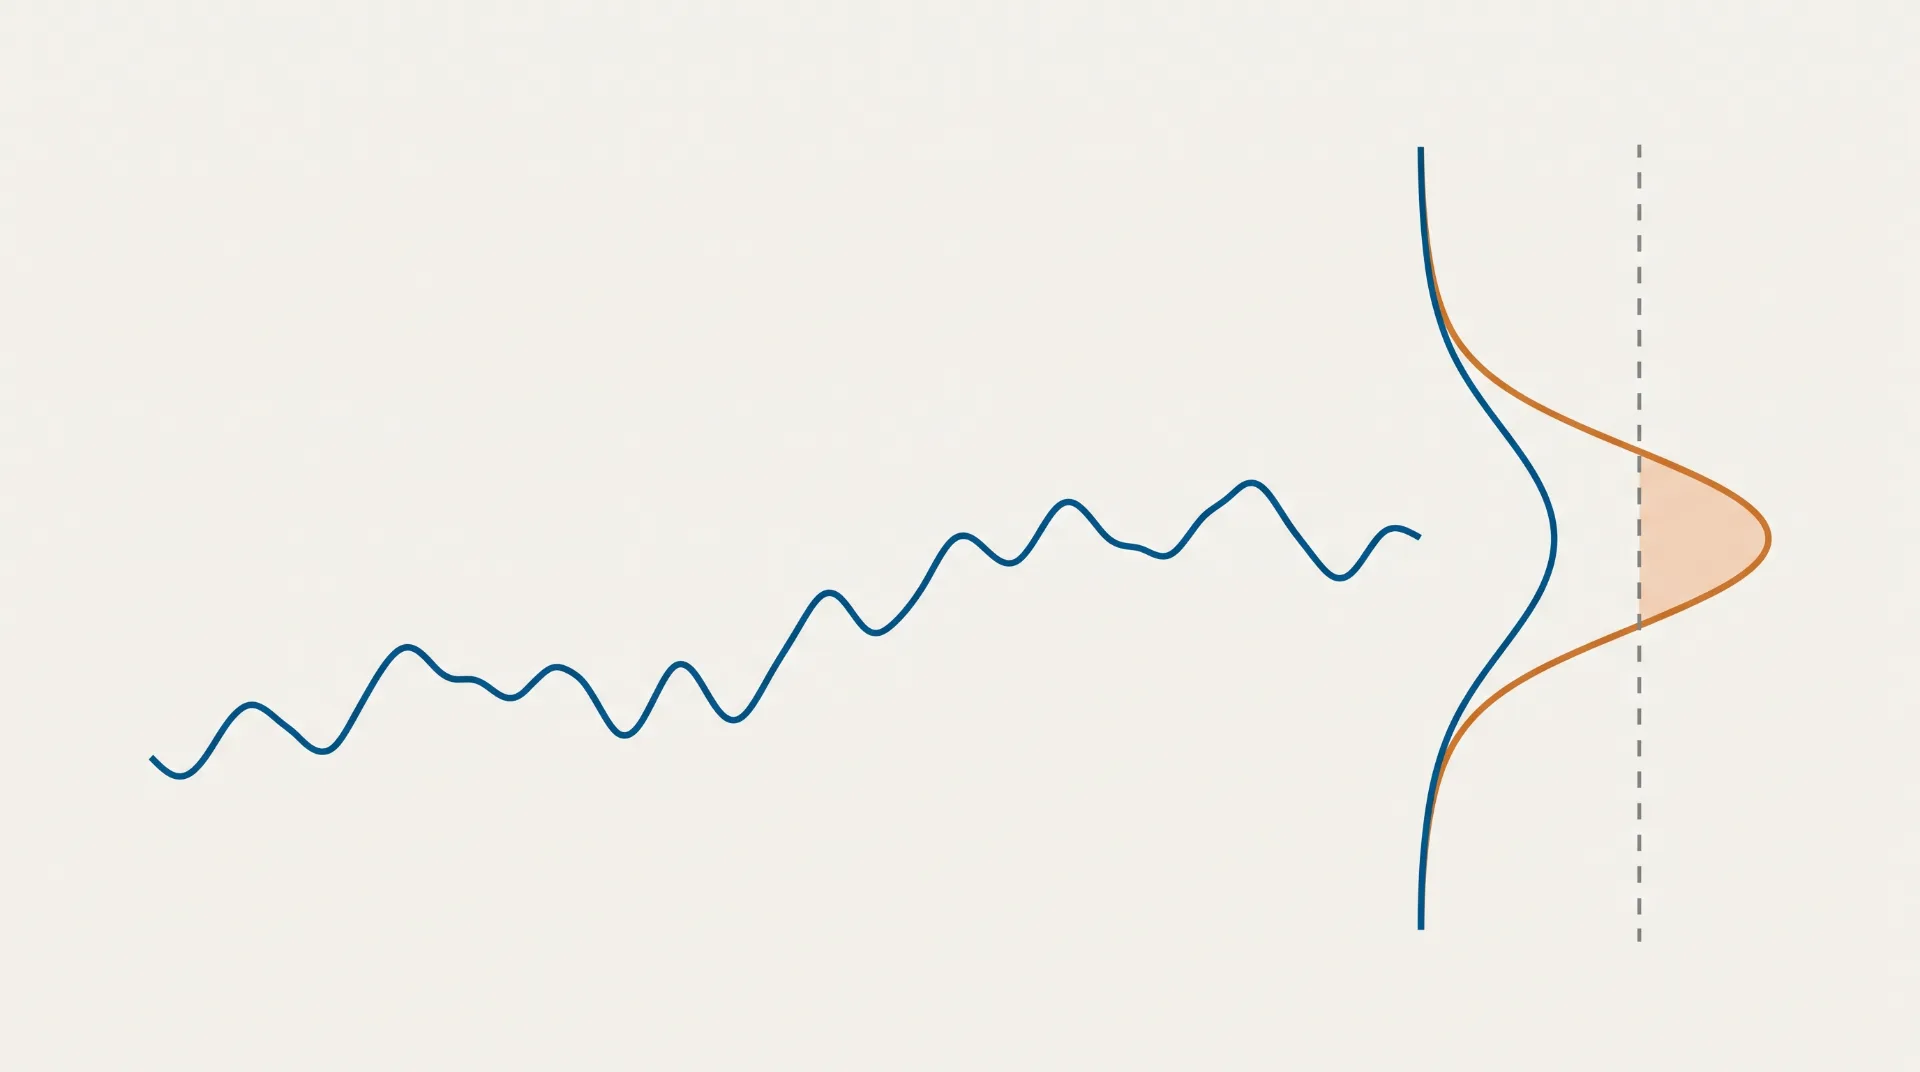
Think about you may have a sensor recording one thing you care about, for instance seismic background at a detector web site, electrical load on a grid, or pressure in a bridge cable, and you have educated a mannequin to forecast the following worth. The mannequin seems on the latest historical past, thinks for a second, and provides you a single quantity: .
There is a threshold that fires an alarm. The query is: must you fear?
You possibly can’t reply that. Not since you’re lacking details about the mannequin, however as a result of the mannequin is lacking a method to inform you what it is aware of. That single quantity is all it might probably say. Let’s have a look at why that is an issue.
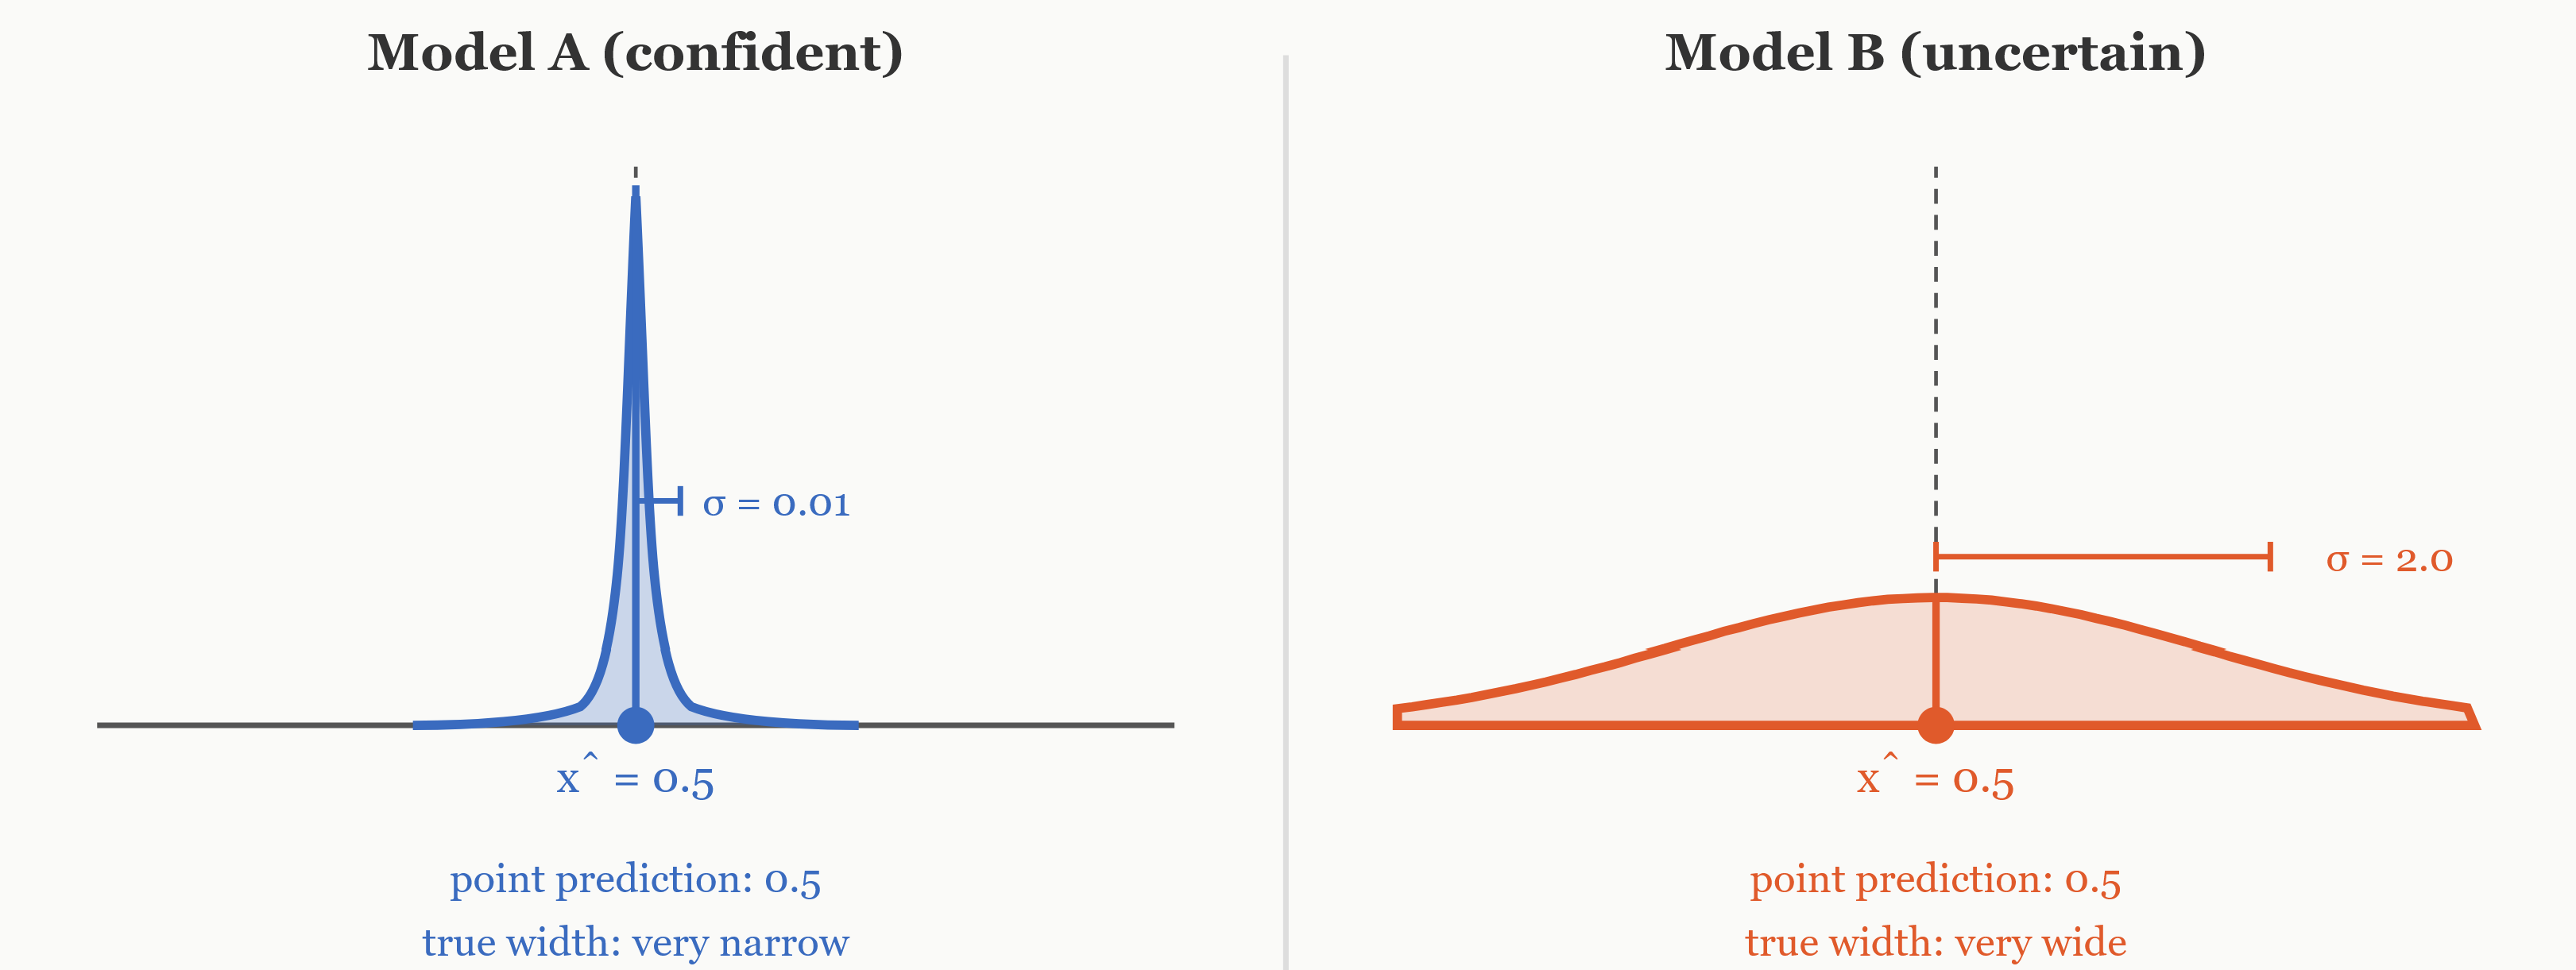
Think about you even have two fashions, each watching the identical sign, each predicting on the similar timestep. They even publish the identical imply squared error in your check set, not roughly, however identically to a few decimal locations. By each customary rating metric, they’re interchangeable. Besides they don’t seem to be.
This is what’s hiding beneath.
-
Mannequin A is a second the place the true conditional distribution, the precise unfold of values the sign may realistically take, given its latest historical past could be very tight:
If this notation is new to you: is a Gaussian distribution (the basic bell curve), the place is the middle, and is the customary deviation, which controls the width. A small means the values cluster tightly across the heart. Right here, 99.7% of the likelihood mass sits inside of the imply, roughly between 0.47 and 0.53. The brink at 1.0 is 50 customary deviations away. That alarm is not going to hearth within the lifetime of the experiment.
-
Mannequin B is a second the place the true distribution is vast:
Similar heart, however . The bell curve is now extraordinarily unfold out. The brink at 1.0 is simply customary deviations away. That is nothing. Roughly 40% of the time, the sign will cross the alarm.
Similar forecast. Similar MSE. Similar check set. However the precise danger of triggering the alarm is versus . When you’re deciding whether or not to evacuate, reroute energy, or flag a detector occasion, these are reverse conclusions and the quantity you ranked each fashions with can’t inform you which is which.
The issue is not that both mannequin is damaged. Each predicted the proper imply. The issue is {that a} single quantity cannot specific I am positive versus I am guessing and the rationale the mannequin cannot specific that is not a coaching bug or a lacking characteristic. It is a direct, provable consequence of the loss operate it was educated with.
That is what this publish unpacks. We’ll see precisely why MSE fingers you the imply and discards all the pieces else, what to interchange it with, and what that substitute prices as soon as an actual optimizer will get maintain of it.
···
What forecasting really asks
Let’s arrange the issue correctly, as a result of the idea we’ll break is hiding within the setup itself.
A time collection is a sequence of numbers recorded so as over time.
For example, temperature each hour, inventory value at market shut every day, or displacement of a seismometer sampled at 100Hz. The important thing property is that the order carries data, the worth at time tells you one thing in regards to the worth at . Shuffle the sequence and that data is destroyed. That is what separates a time collection from, say, a bag of impartial measurements.
We write the noticed sequence as:
the place is the worth at timestep . Forecasting means predicting the longer term values:
Two numbers management the setup:
-
= context size: how far again the mannequin seems.
-
= forecast horizon: how far forward the mannequin predicts.
The best case is , which implies predicting solely the very subsequent worth. That is the place we’ll focus. In apply, could be dozens or a whole lot, however the argument about MSE versus NLL applies identically no matter .
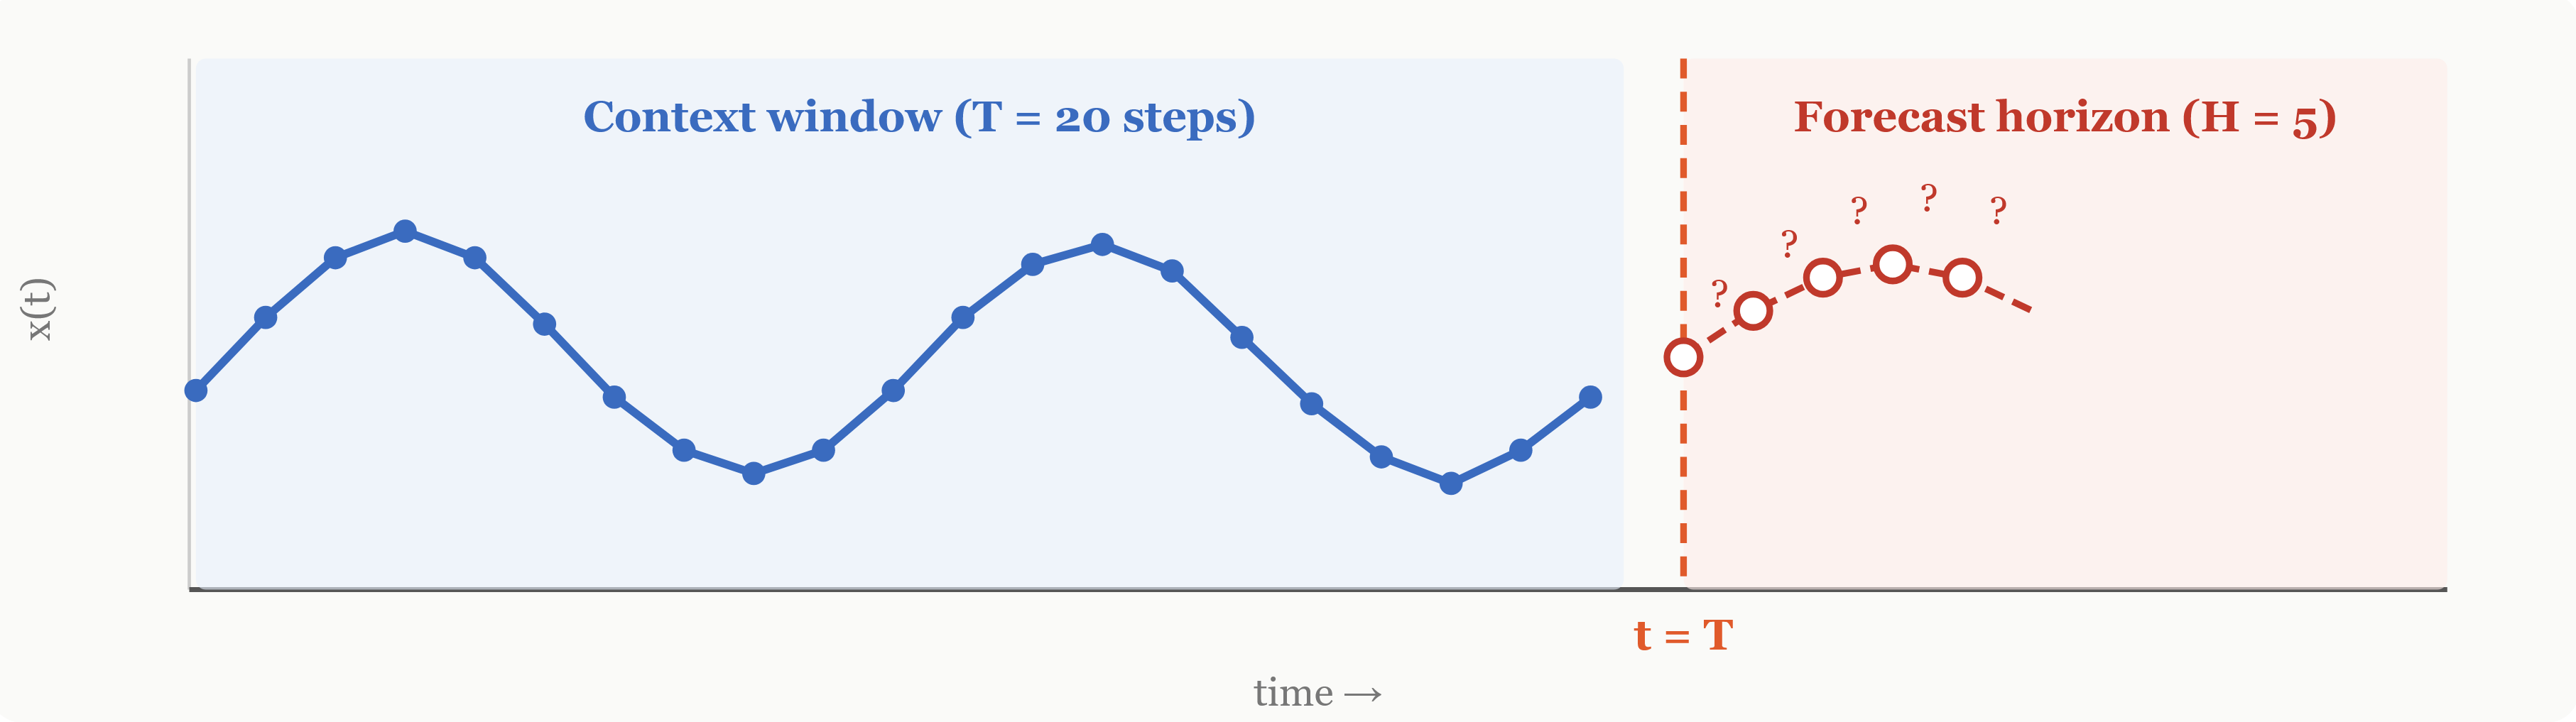
Now this is the delicate half that the majority textbooks gloss over. If you write down your prediction as a single quantity , you’ve got made a philosophical dedication with out realizing it. You are treating the longer term as if it is decided by the previous, as if figuring out the historical past completely would inform you the following worth precisely.
Take into consideration what that single quantity means. The mannequin says the subsequent worth is 0.5, not most likely round 0.5, not someplace between 0.3 and 0.7, simply 0.5, full cease. That format has no room for doubt. There is no such thing as a discipline within the output for by the way in which, I am undecided about this one.
No person agrees to this assumption on function. You comply with it by choosing a loss operate. The loss decides what the mannequin can and can’t specific, and the usual loss, MSE, decides for you: the reply is some extent, not a distribution.
···
The best loss, and what it really optimizes
Essentially the most pure factor a mannequin can do is emit one actual quantity for every future step. Coaching wants a loss operate, that’s, a method to measure how fallacious the prediction was. The near-universal alternative is of this downside is the imply squared error:
the place the sum runs over all coaching examples and timesteps. It is zero when the prediction is actual, and grows quadratically because the prediction drifts away:
-
An error of two prices 4 instances an error of 1.
-
An error of 10 prices 100 instances an error of 1.
Massive errors dominate the gradient, which is precisely what you need, miss the spike and you have missed the purpose.
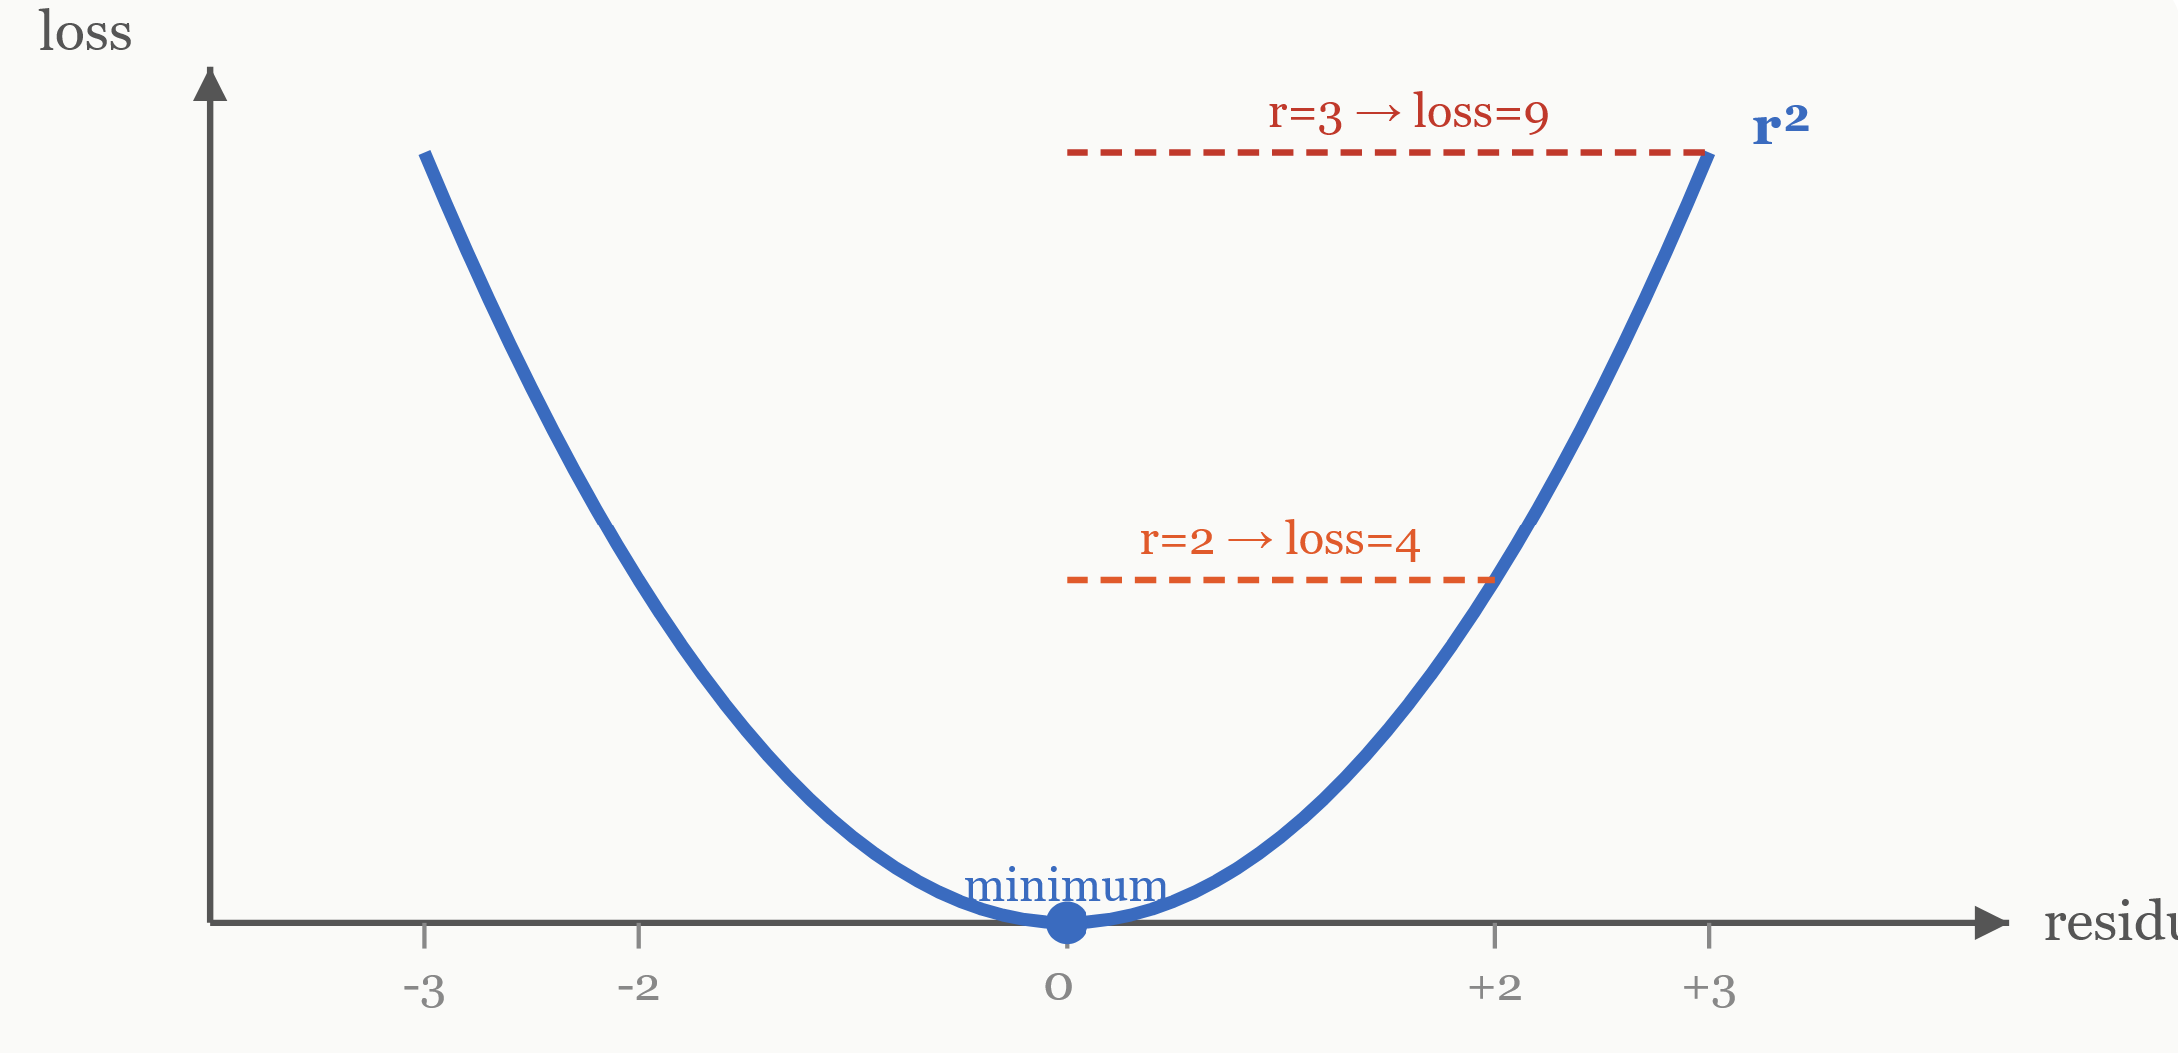
Thus far, so good. The difficulty begins once you ask: what prediction does MSE really reward? If the mannequin might be good, what would MSE push it towards?
The proof: with out historical past first
Let’s overlook about neural networks, architectures, all the pieces. Simply pure math. Bear with me, the derivation is brief, and it tells you one thing basic.
You’ve got a random variable , the subsequent worth the sign will take. You do not know what will probably be, but it surely has some distribution with imply . Your mannequin should decide to a single quantity. Consider it as writing one quantity on a bit of paper and handing it over, earlier than the reality is revealed. Which minimizes the anticipated squared error?
We need to decrease:
Broaden the sq. (simply , then take the expectation of every time period):
is a set quantity (is dependent upon the distribution of , not our alternative). can be fastened, that is . In order a operate of , this can be a parabola opening upward. It has precisely one minimal.
Differentiate with respect to and set to zero:
The optimum single-number prediction beneath squared error is the imply. Geometrically: the purpose closest on common, in squared distance, to a cloud of potential outcomes is the middle of that cloud.
Now with historical past
In forecasting, is not drawn from a set distribution. Its distribution is dependent upon the historical past, that’s, what the sign has been doing. Totally different pasts result in completely different futures. Now, write for the noticed historical past. Run the very same argument, however situation all the pieces on :
Differentiate with respect to , set to zero:
Nothing modified structurally. The derivation is precisely the identical as earlier than, we simply added “” in every single place.
That is what the MSE optimizes for:
The MSE-optimal prediction is the conditional imply. That is what any mannequin educated with MSE is pushed towards, no matter structure (transformer, LSTM, linear regression, something). Given infinite information and sufficient capability, the mannequin converges to predicting the typical of the place the sign may go subsequent, given the previous it has seen.
The imply is a superbly affordable factor to foretell. No different single quantity does higher beneath squared error. However the imply is a single abstract of location. It tells you the place the middle of the distribution sits. Nonetheless, it tells you nothing about:
-
Width: Is the distribution tight ) or vast )?
-
Form: Symmetric? Skewed? Heavy-tailed?
Two fully completely different conditions can share an similar conditional imply and MSE, however by development, can’t inform them aside. It has no time period that rewards getting the width proper, and no time period that punishes getting it fallacious. The unfold is invisible to the loss. That is Mannequin A and Mannequin B restated within the language of the maths. Similar conditional imply, incompatible futures, one quantity.
···
The idea no person writes down
This is the place it will get worse. MSE would not merely ignore the unfold, ignoring it might be survivable. Coaching with it’s mathematically equal to assuming the unfold is the similar in every single place. To see this, we want a brief detour by most probability estimation (MLE). Do not let the title intimidate you, the thought is definitely fairly easy.
Most probability: the instinct
Overlook loss features for a second and give it some thought in another way. Your mannequin, with parameters , seems on the historical past and makes a prediction. As a substitute of simply asking how shut was the prediction, ask a richer query: how possible did the mannequin suppose the true consequence was?.
Say the true worth turned out to be 3.7. A very good mannequin ought to have thought 3.7 was possible. A nasty mannequin thought 3.7 was a one-in-a-million occasion after which it occurred, which implies the mannequin had a foul image of actuality.
Most probability simply says: choose the mannequin parameters that make the noticed information as possible as potential. The settings beneath which actuality seems least shocking. However to assign chances to outcomes, we want a noise mannequin, an assumption about how noticed values scatter across the prediction. Essentially the most pure place to begin is a Gaussian with some fastened width.
The noise assumption
Assume that what you observe equals the mannequin’s prediction plus random noise:
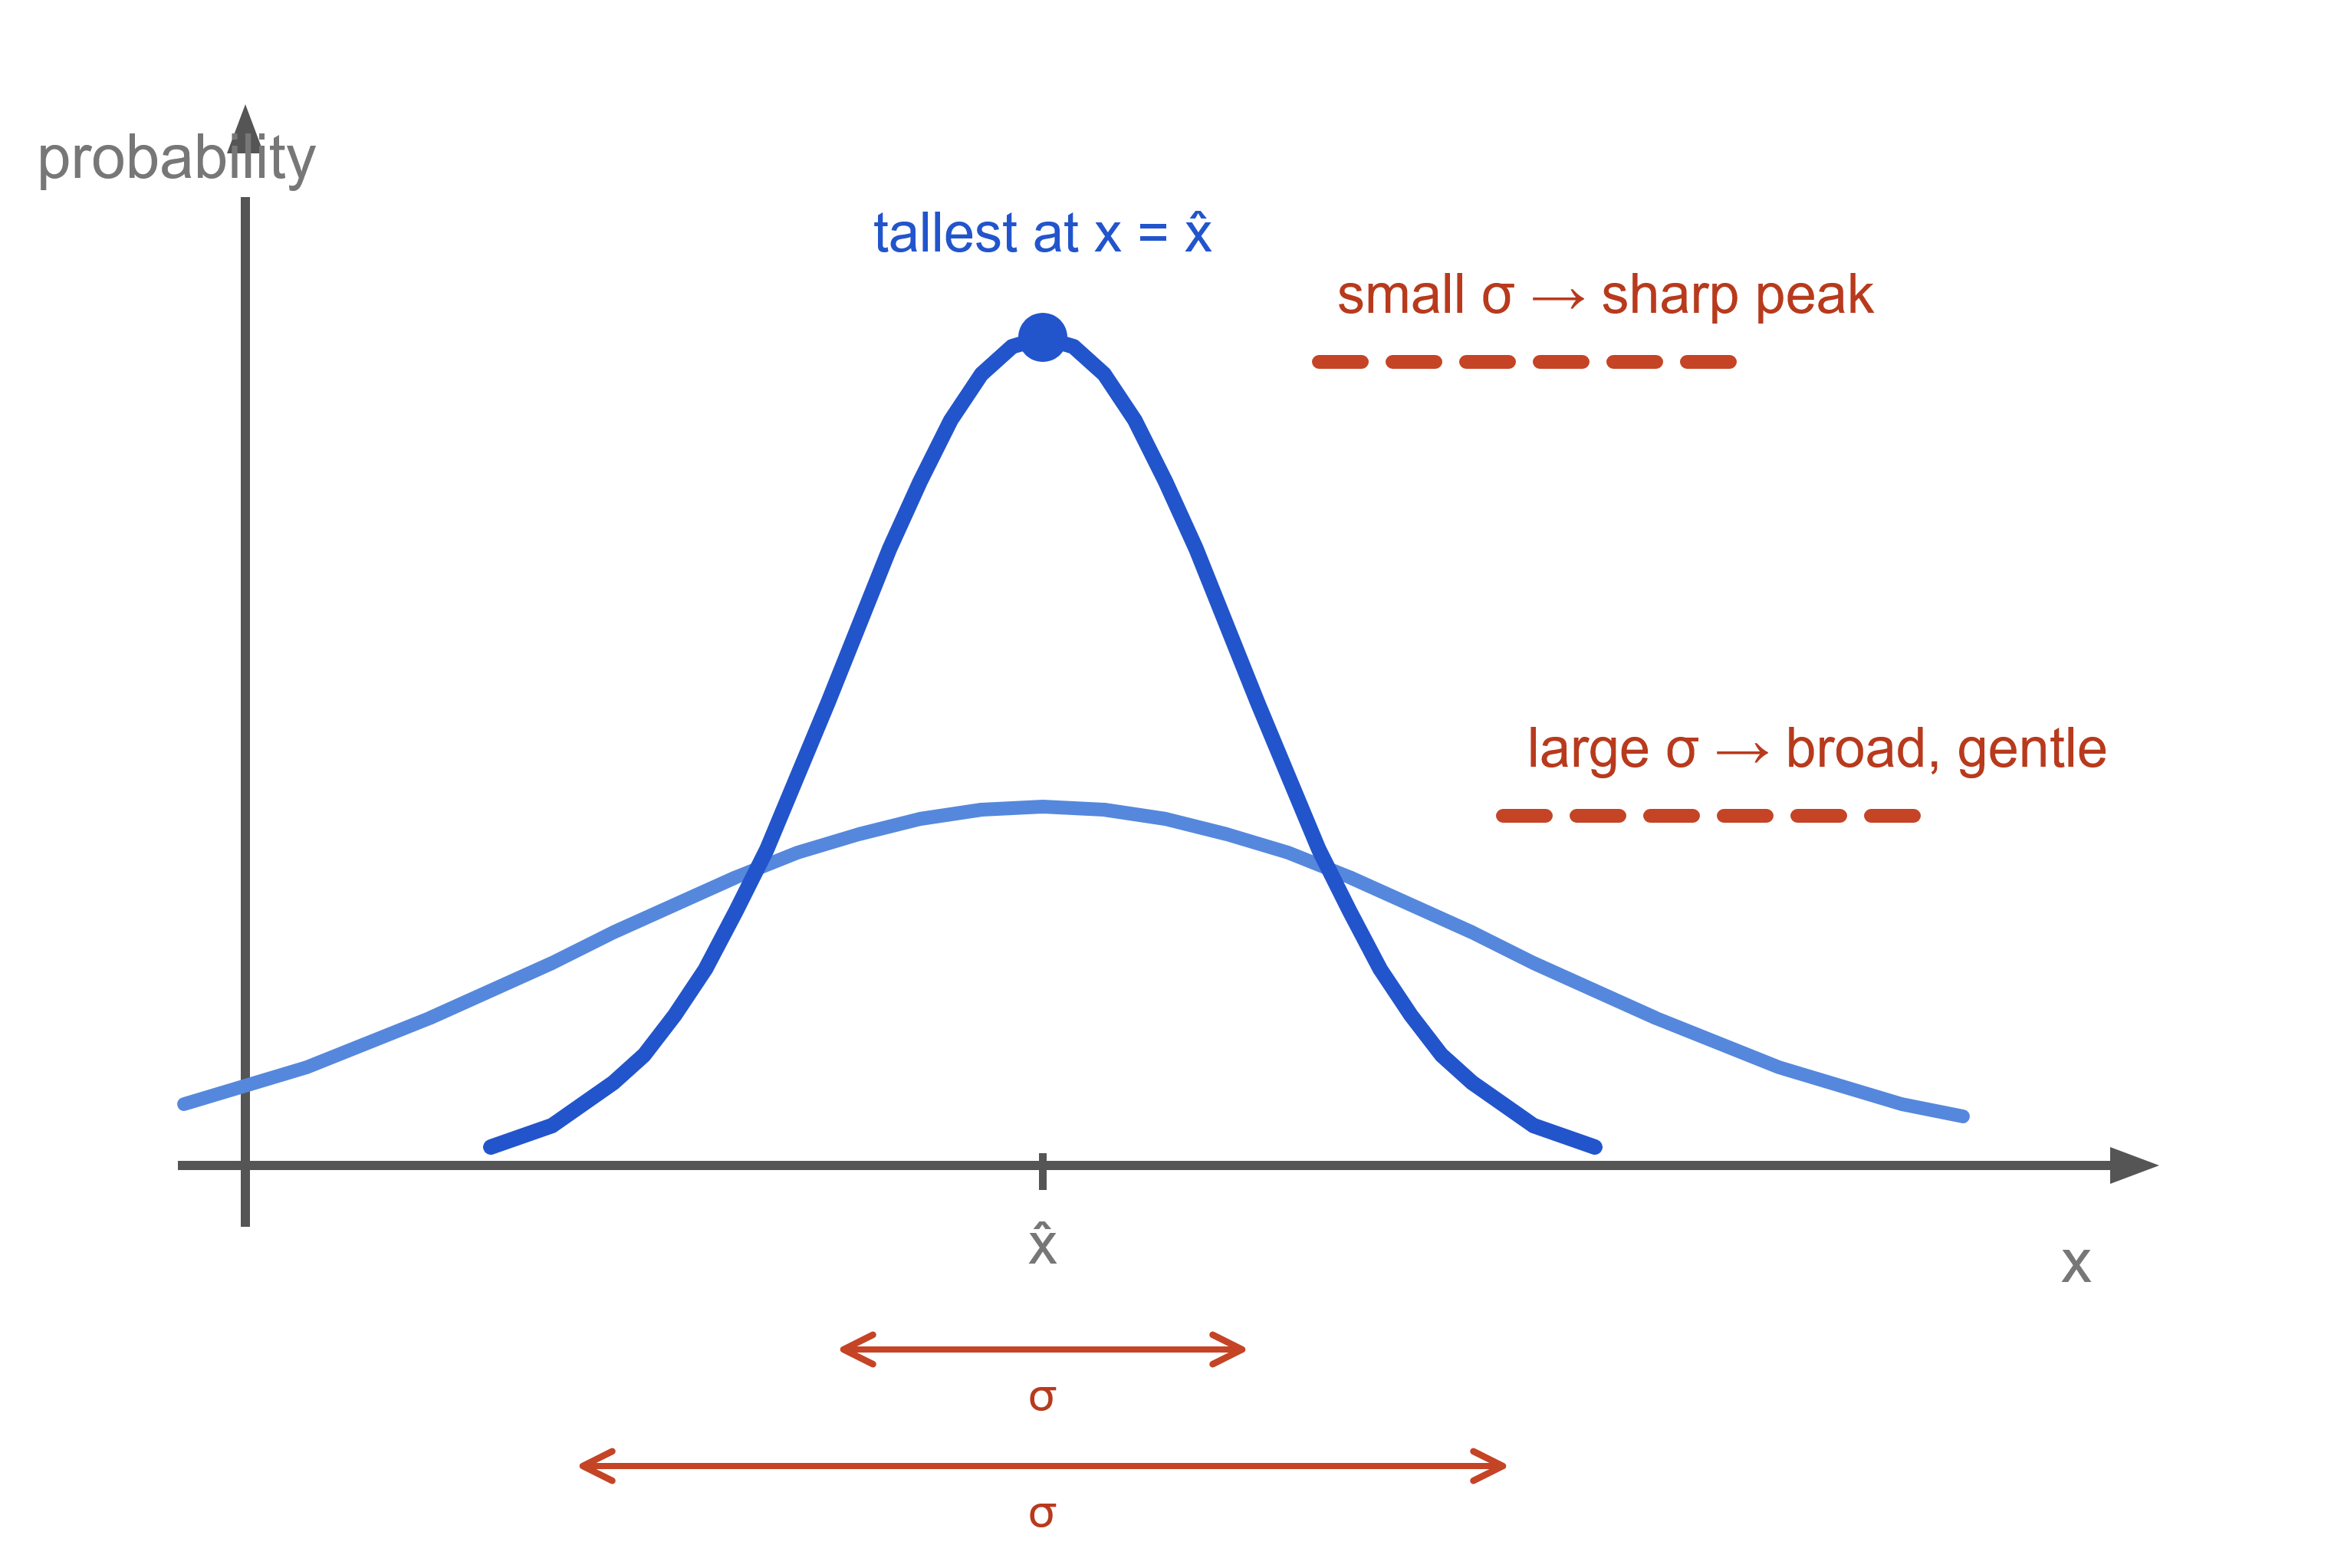
In phrases: the true worth is the prediction, plus a small random perturbation drawn from a Gaussian centered at zero with variance . The important thing phrase right here is fastened, the identical for each information level, each timestep, each enter. Underneath this assumption, the likelihood density of observing given the prediction is the Gaussian density:
If this formulation is new to you: it is tallest when (good prediction), and falls off as strikes away from . The velocity of falloff is managed by , small means a pointy peak, giant means a broad light curve.
From likelihood to loss operate
Now you may have impartial observations. Each has a likelihood beneath the mannequin. The overall likelihood of the whole dataset is the product:
Merchandise of many small numbers underflow to zero on a pc, and their derivatives are messy. So we take the logarithm. Since is monotonically rising, the parameters that maximize the product additionally maximize the logarithm. The product turns into a sum:
Plug within the Gaussian density. For a single time period:
The primary half is , which is identical for each information level (since is fastened). Sum over all observations:
Now, maximize over the predictions (i.e., over the mannequin parameters). Take a look at the 2 phrases:
-
First time period: . Incorporates no in any respect. It is a fixed. Ignore it.
-
Second time period: . The issue is a constructive fixed. It rescales however would not change which parameters produce the utmost.
Strip each away, and maximizing the log-likelihood is exactly minimizing:
That is MSE. Now learn it backwards.
Each time you practice with MSE, you may have implicitly assumed that the residuals are Gaussian with fixed variance , similar for each enter. You made a probabilistic assumption. You by no means stated it out loud. The loss operate stated it for you.
And as soon as coaching ends, even that single is gone. It lived solely contained in the derivation. The educated mannequin fingers you and nothing else.
Why fixed variance is sort of all the time fallacious
Take into consideration what fixed means in apply. The mannequin is pressured to be equally assured in every single place:
-
Forecasting electrical energy demand on an bizarre Tuesday evening: straightforward, low variance. Forecasting it throughout a shock heatwave: laborious, excessive variance. Similar for each? That is the idea.
-
Seismic background at a detector web site on a quiet day: virtually flat, very predictable. Throughout a teleseismic occasion: wild fluctuations. Similar for each? That is the idea.
The technical time period for fixed variance is homoscedastic. Nonetheless, in a practical scenario, variance that adjustments with the enter is heteroscedastic. Virtually each actual bodily and financial sign is heteroscedastic. MSE cannot symbolize that.
That is precisely what separated Mannequin A from Mannequin B mentioned above. The true conditional variance was in a single case and within the different. An MSE-trained mannequin matches one for the entire dataset and applies it in every single place, too vast when issues are calm, too slim when issues are unstable, fallacious in each instructions. That is the crack within the basis, however, the repair is shorter than you’d suppose.
···
The leap: predict a distribution
The entire downside comes down to 1 factor: by no means seems within the mannequin’s output. It was hiding contained in the derivation that produced MSE, it was fastened to 1 worth for the whole dataset, and it vanished after coaching. The mannequin actually has no method to say I am unsure right here.
The repair could be very easy. As a substitute of emitting a single quantity, make the mannequin emit the parameters of a likelihood distribution.
The best alternative, and the pure one, provided that MSE was already implicitly Gaussian, is 2 numbers:
the place is the anticipated heart and the anticipated width. The mannequin now claims:
In phrases: I believe the following worth is drawn from a bell curve centered at with customary deviation.
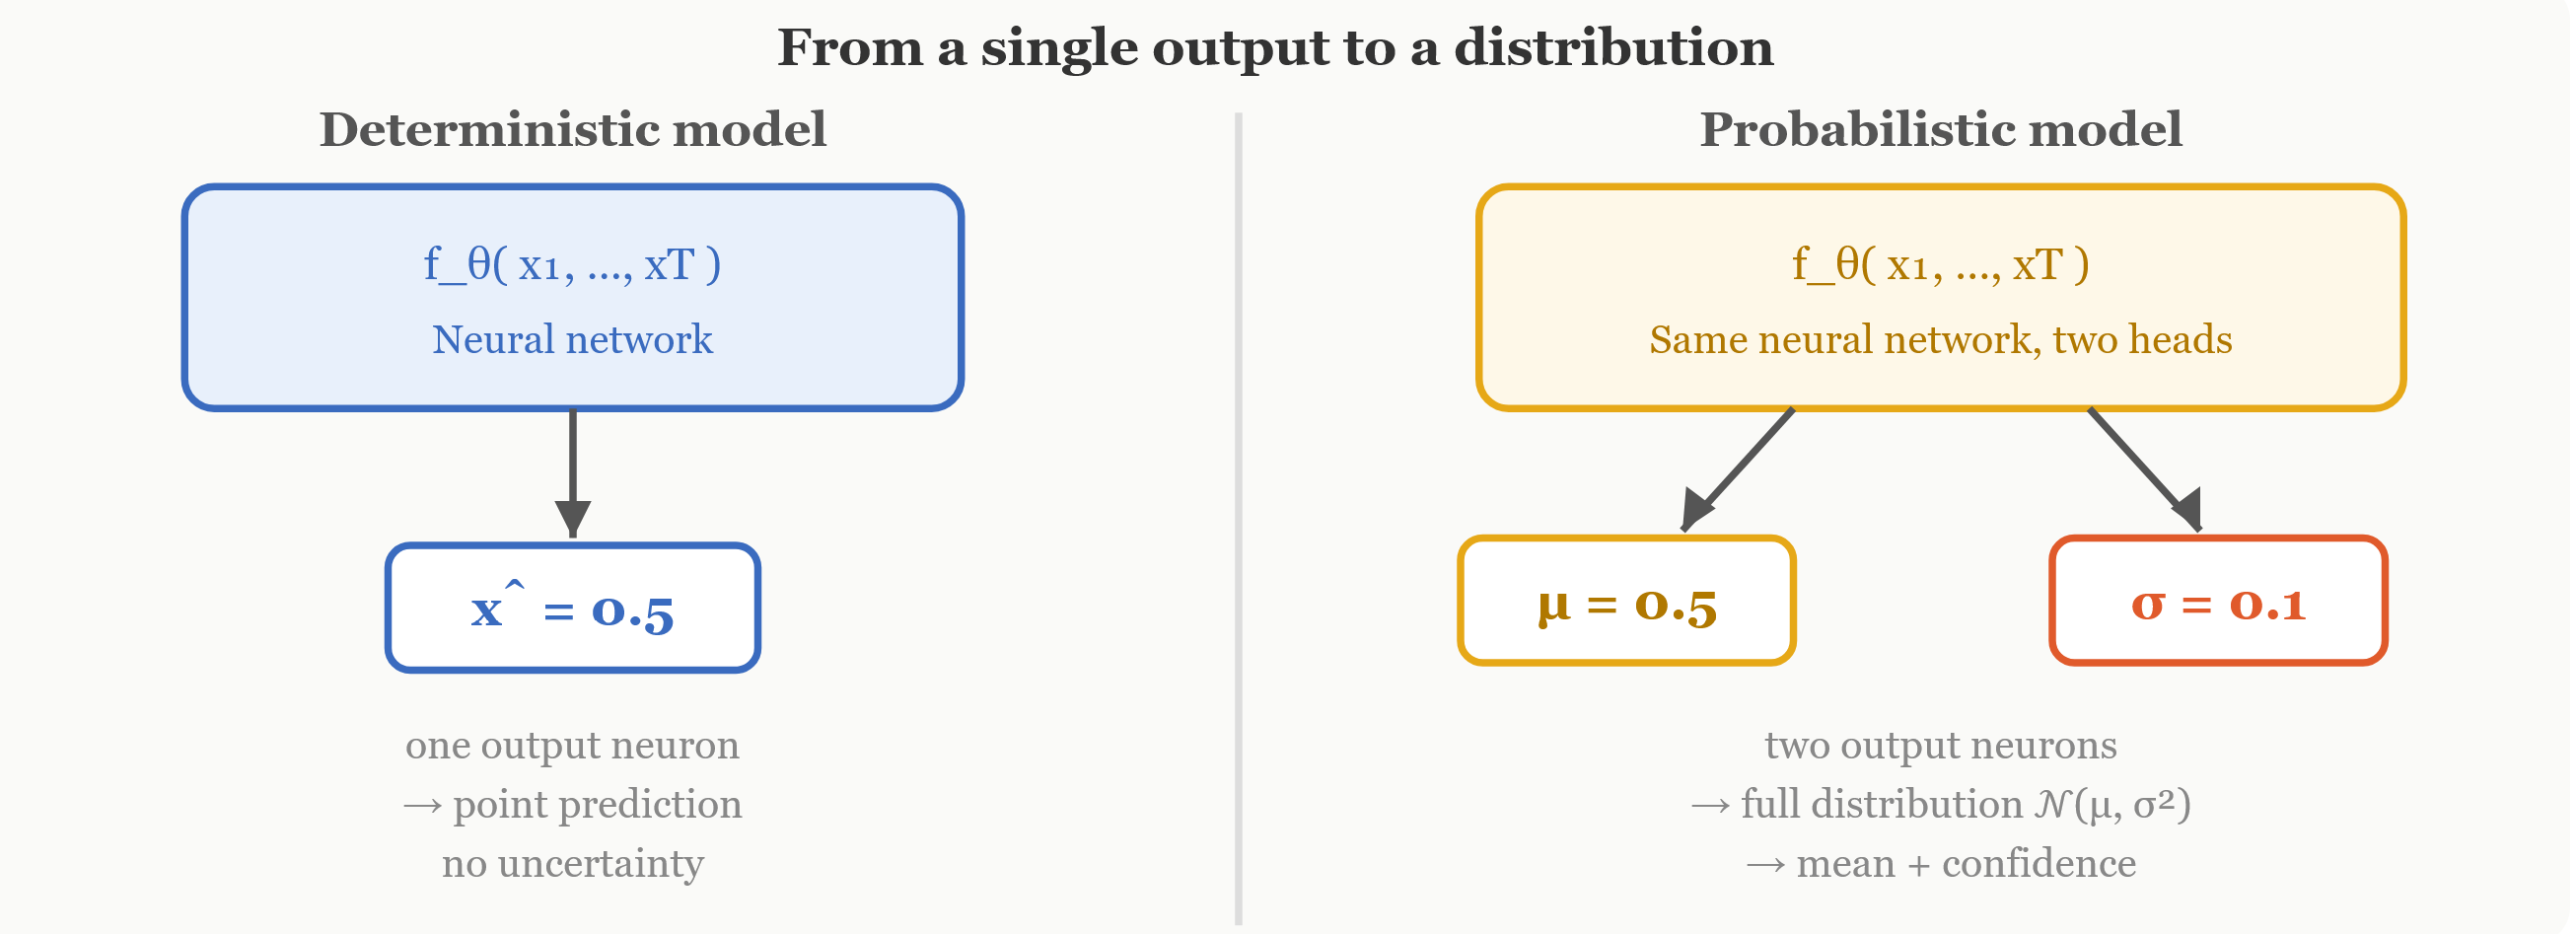
That could be a larger change than one further output neuron suggests. The output area adjustments from (a single level on the quantity line) to a distribution over . The mannequin stops committing to 1 reply and begins reporting a weighted vary of prospects, together with how vast that vary needs to be at this explicit second, given this explicit historical past.
And is not a single world quantity. It is a operate of the enter. The identical mannequin can output when the sign is in a relaxed stretch and when the sign enters a loud regime. It will get to resolve, at every timestep, how assured to be.
Architecturally, the change is minimal. The spine, each consideration head, each hidden layer, all of the characteristic extraction, stays similar. The ultimate layer positive factors one further output neuron. One neuron produces , the opposite produces . That is it. However now we want a brand new loss. MSE solely is aware of how one can examine one quantity to 1 quantity, it has no concept what to do with . When you practice with MSE, the head will be taught (MSE can rating it), however the head will get no gradient sign in any respect. We want one thing that trains each.
···
Asking a greater query
Your mannequin predicts that the following worth follows:
Then the true worth is revealed. How can we rating the prediction?
Overlook formulation for a second. Give it some thought intuitively. The mannequin drew a bell curve. That bell curve assigns a likelihood density to each potential consequence, excessive density close to the middle, low density out within the tails.
Then actuality handed us a particular quantity . If landed close to the height, the place the mannequin put numerous likelihood, the mannequin did properly. It thought this consequence was possible, and it was proper. If landed means out within the tails, the place the mannequin put virtually no likelihood, the mannequin did poorly. It was stunned by actuality. So the pure rating is: how a lot likelihood density did the mannequin assign to the worth that truly occurred?
That density is:
We would like this to be giant. Since is monotonically reducing, maximizing this density is identical as minimizing the detrimental log-likelihood:
Why the logarithm? Two causes. Virtually: coaching minimizes losses, so we negate to flip maximize into decrease. As well as, numerically: likelihoods over many information factors are merchandise of small numbers (which underflow); turns merchandise into sums, holding issues secure. Discover the shift in philosophy:
-
MSE asks: How far was your quantity from the reality?
-
NLL asks: How stunned ought to you may have been by the reality, given the distribution you predicted?
The second query is richer as a result of it includes each the middle and the width.
Now let’s derive the formulation. No tips, simply algebra. Bear with me, it is simply 4 strains after which we’re finished. Begin from the Gaussian density:
Step 1: take the logarithm: The expression is a product (fraction instances exponential), so splits it right into a sum:
Step 2: increase the primary time period. Utilizing and:
Step3: assemble.
Step 4: negate and drop the fixed. The time period is dependent upon neither nor , so its gradient is zero. Drop it:
Two phrases, two jobs. They usually do not cooperate, they struggle. The struggle is the mechanism.
···
Two phrases and the struggle between them
Understanding this competitors is the important thing to understanding each failure mode you may probably meet later. Let’s take the 2 phrases one by one.
The match time period:
The numerator is the squared residual, precisely MSE. The brand new ingredient is the denominator: , which is the mannequin’s claimed variance (instances 2).
Dividing by makes the penalty relative to the boldness the mannequin claimed earlier than seeing the reply.
Think about the mannequin predicted and the reality is . The squared residual is 1.0. Now:
-
(very assured): match time period . Monumental. The mannequin stated I am sure, and was badly fallacious.
-
(modest): match time period . The miss was throughout the claimed unfold.
-
(very unsure): match time period. Practically free.
The mannequin is allowed to make errors, however provided that it admitted beforehand that these errors had been potential. The worth of was chosen earlier than was revealed, no dishonest after the actual fact. However this is the catch. The match time period will get cheaper as grows. At all times. For any fastened residual, a much bigger means a smaller penalty. So if this had been the one time period, the mannequin would uncover a trivial technique: set and by no means be punished for something. That is clearly ineffective, a mannequin that claims I do not know in every single place is not forecasting, it is giving up.
The honesty time period:
This closes that door. will increase as will increase. That is it. That is the entire mechanism.
-
Small (excessive confidence): is small and even detrimental. This reduces the entire loss. The mannequin is rewarded for precision.
-
Massive (low confidence): is giant and constructive. This will increase the entire loss. The mannequin pays a value for hedging.
The stability
Put each phrases collectively:
The match time period says: make larger so my errors price much less, whereas the honesty time period says: make smaller so I get rewarded for precision. These two forces pull in reverse instructions, and the mannequin has to seek out the place they stability. That stability isn’t a hand-tuned tradeoff. There is no such thing as a hyperparameter weighting the 2 phrases, they got here from the identical derivation, from the identical logarithm of the identical Gaussian density. The stability falls out of the maths.
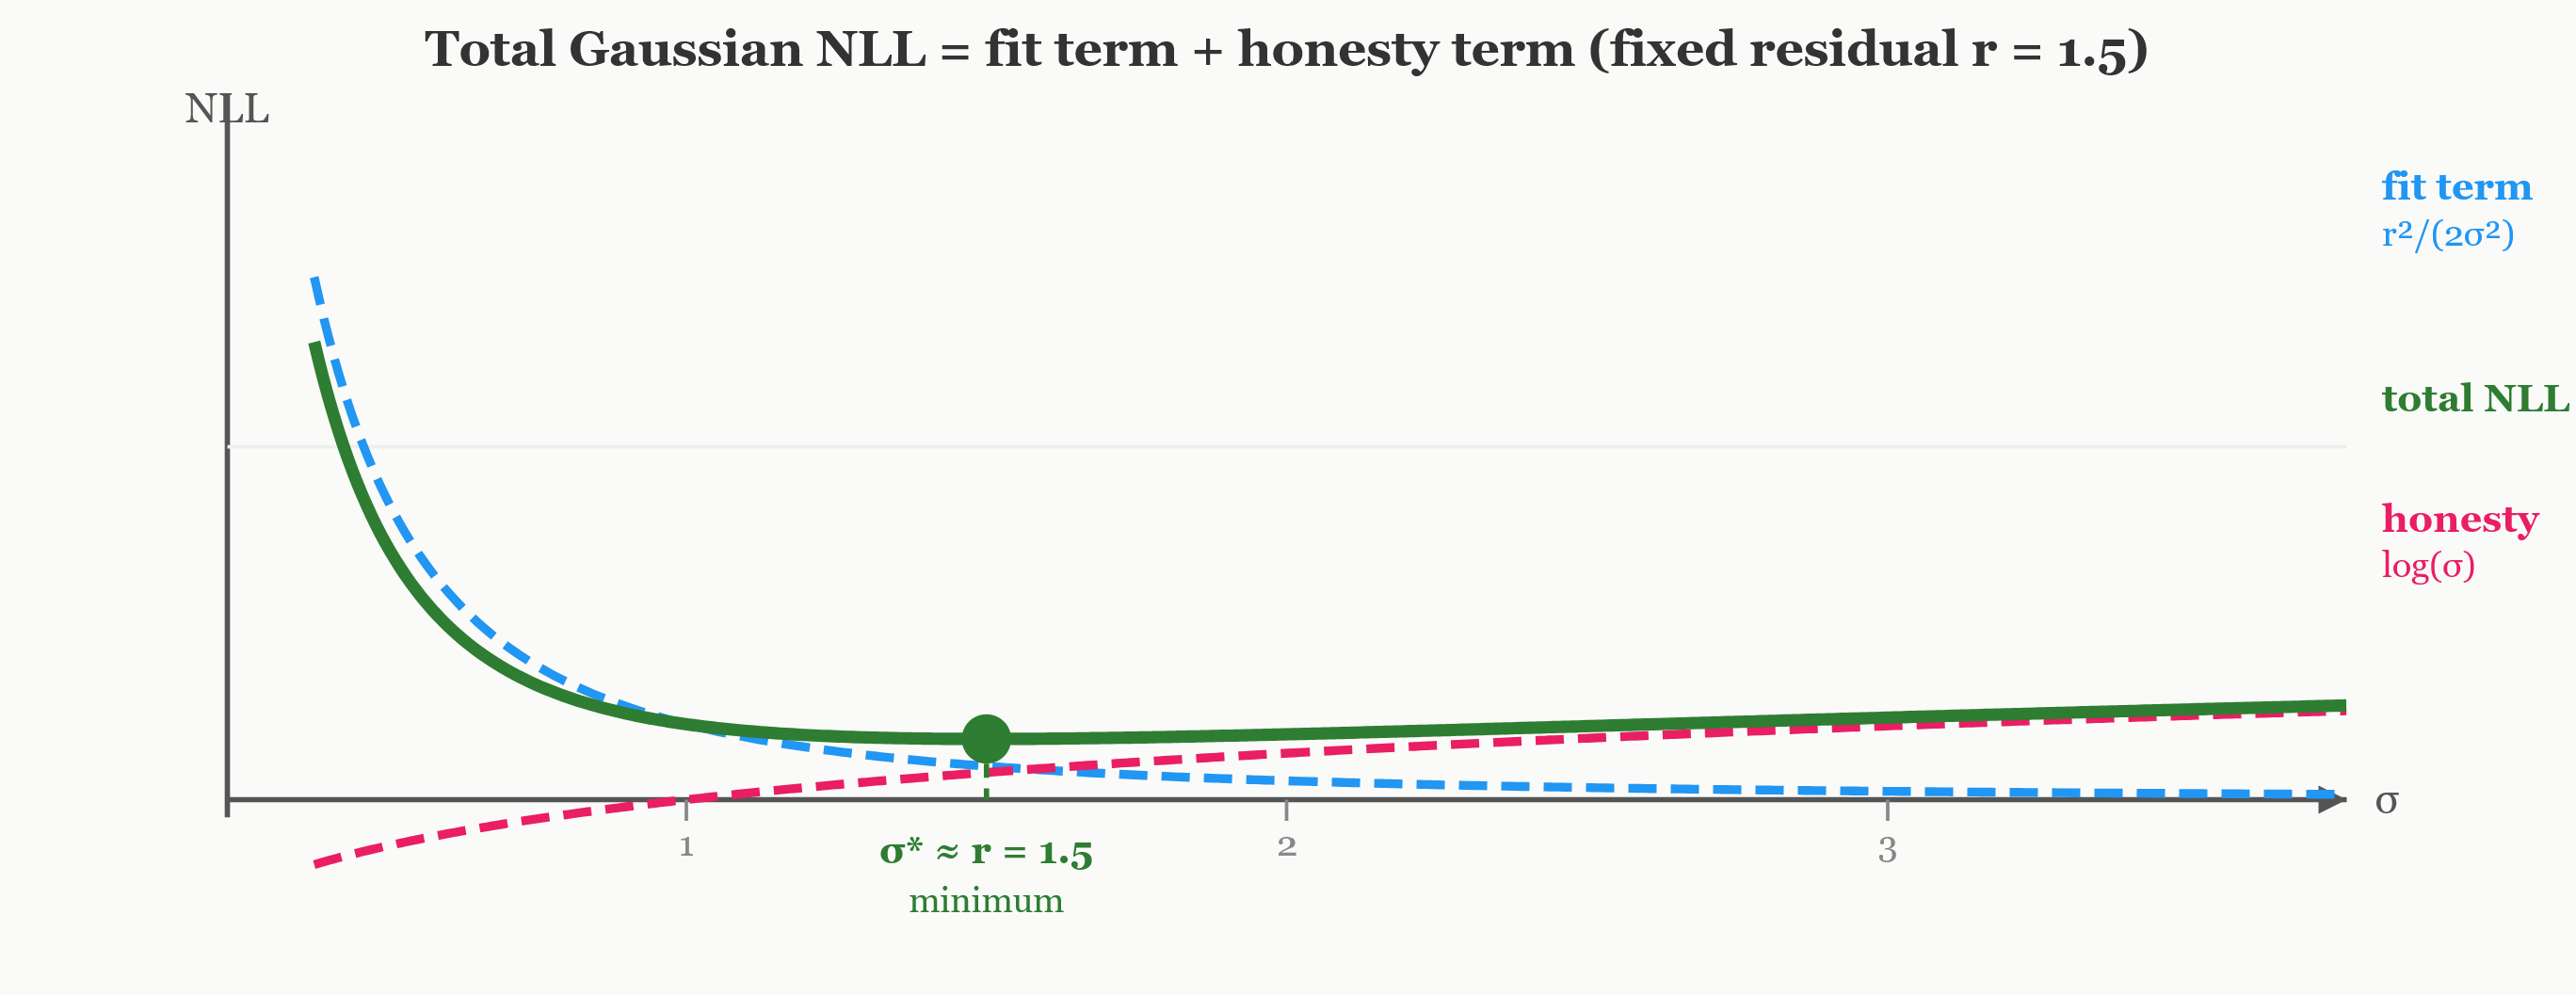
To make this concrete, repair the residual at and take a look at the entire loss for various :
|
|
Match time period |
Honesty time period |
Complete |
|
|
|
|
1.557 |
|
|
|
|
1.125 |
|
|
|
|
0.905 |
|
|
|
|
0.974 |
|
|
|
|
1.224 |
|
|
|
|
1.654 |
The minimal is at , which is precisely , the dimensions of the residual. At small , the match time period dominates. At giant , the honesty time period takes over. The candy spot is the place the mannequin’s claimed uncertainty matches the precise error.
Wow, that is not a coincidence. The subsequent part proves it precisely.
···
What the optimum must be
We have seen the instinct. Now let’s discover the stability precisely.
Optimum
Maintain fastened and optimize . The one -dependent a part of the loss is:
That is MSE multiplied by the constructive fixed . Multiplying by a constructive fixed stretches the operate vertically however would not transfer the minimal. We already know MSE is minimized by the conditional imply, so:
NLL and MSE agree fully on the place the middle needs to be. The within the denominator rescales the penalty however would not shift the optimum. All the things the mannequin already knew how one can do is preserved.
Optimum
Now repair and optimize . Outline the true conditional variance:
That is how unfold out really is round its imply, given the enter. It is a property of the info, not the mannequin. From ‘s perspective, is only a fastened constructive quantity.
The anticipated loss as a operate of :
Differentiate. The spinoff of is .
The spinoff of is :
Gaussian NLL pushes towards the true conditional variance.
The mannequin learns each the conditional imply and the conditional variance concurrently, one loss operate, two targets.
This implies the uncertainty isn’t a manually chosen fixed. The mannequin produces a unique for each enter, matching the precise native noise. When the sign is in a relaxed regime, is small and so is . When the sign enters a loud regime, each develop. The mannequin learns to be assured the place it needs to be assured, and unsure the place it needs to be unsure, mechanically, from the info.
That is the lacking piece from Sections 1-4. Mannequin A’s small variance ) and Mannequin B’s giant variance () can lastly be distinguished, as a result of the loss provides the mannequin a cause to be taught them.
···
Why that is the fitting loss, not merely a very good one
All the things to date has been: this is a loss, the maths works out, the optimum is good. However you might fairly ask why this loss? May you prepare dinner up a unique two-term penalty that additionally balances and ? One thing like with a hand-tuned ?
Certainly, that might additionally penalize giant . It’d even work okay. However it might be an arbitrary recipe with no principled interpretation. Gaussian NLL is not one recipe amongst many. It has a deeper justification from data principle.
KL divergence: the instinct
Let be the true conditional distribution (how actuality really generates outcomes) and the mannequin’s prediction. The Kullback-Leibler divergence measures how completely different they’re How a lot data is misplaced once you use the mannequin’s distribution as a stand-in for the true one?
In the event that they match completely, KL is precisely zero, no data misplaced. The extra they differ, the bigger the KL. The KL divergence is outlined as:
Broaden the log ratio:
The primary time period is the detrimental entropy of the true distribution, this can be a fastened quantity that relies upon solely on floor reality (actuality), not on the mannequin. From ‘s perspective, it is a fixed. The second time period is the anticipated log-likelihood beneath the mannequin. So:
The deep connection
If you decrease NLL, you might be minimizing the information-theoretic distance between the mannequin’s predicted distribution and the bottom reality. You are dragging towards .
As well as, KL divergence would not simply care in regards to the imply or the variance. It cares about each facet of the distribution, equivalent to skewness, kurtosis, tail habits, all the pieces. The one cause we be taught simply imply and variance right here is that we selected a Gaussian for , and a Gaussian is totally decided by these two numbers. Select a richer household, and the identical NLL precept pushes the mannequin to be taught these further features too.
The cleanest method to see the elemental distinction:
-
MSE minimizes a distance between two numbers.
-
NLL minimizes a distance between two distributions.
MSE operates within the area of values. NLL operates within the area of likelihood distributions. The second is infinitely richer. And this is the attractive half: once you prohibit NLL to a Gaussian with fastened , it collapses again to MSE, that was Part 4. MSE is a particular case of NLL, the case the place you’ve got given up on studying uncertainty. NLL is the overall framework; MSE is what you get once you freeze and throw it away.
···
Sensible Engineering
Stunning goal. Now make it survive when it really works with an optimizer. To realize this, two engineering particulars have to be taken under consideration and one deeper concern stands between the derivation and the code that trains.
Predict , not
The output layer produces any actual quantity, however have to be strictly constructive. How do you implement that?
-
ReLU: . Constructive (or zero), however horrible. For the output is zero, the gradient is zero, the community cannot be taught. Half the vary is lifeless. And is catastrophic, the match time period blows as much as infinity.
-
Softplus: . Higher, all the time constructive, by no means zero. However the gradient saturates close to , making studying sluggish precisely the place precision issues.
-
The usual transfer: let the community predict (unconstrained, any actual quantity) and get better . The exponential is all the time constructive, clean in every single place, and its personal spinoff. Rewritten in , the NLL turns into:
Each and now vary freely over . Nothing for the optimizer to struggle.
Clamp the vary
Even reparameterized, can wander someplace ineffective:
-
(): the match time period explodes on the tiniest residual. Gradients blow up.
-
(): the mannequin claims whole ignorance. Ineffective.
A easy clamp retains issues sane:
This offers , vast sufficient for normalized time collection. The decrease certain is named the -floor. When you see the mannequin’s pinned on the ground throughout many inputs, one thing is probably going fallacious with the ground setting or the info normalization.
The optimization entice
This one is subtler. It is not about numerical stability, it is in regards to the optimization panorama. Take a look at the gradient of the match time period with respect to :
See the ? The gradient that updates is scaled by the inverse of . When is properly calibrated, that is wonderful. However early in coaching, this is what occurs:
-
The mannequin begins with random parameters. Predictions are unhealthy, giant residuals in every single place.
-
Two paths to cut back the loss: enhance (laborious, requires studying sign construction) or enhance (straightforward, simply shift the output upward).
-
The mannequin takes the simple path, grows.
-
As grows, the issue shrinks. The gradient on weakens.
-
The mannequin stops bettering for the laborious examples, as a result of it already labeled them as unsure.
A vicious cycle: giant weak -gradient stays unhealthy giant residuals justify giant . The mannequin learns to clarify away its personal errors by claiming uncertainty, as a substitute of truly getting higher. And the examples the place this occurs most are precisely the toughest ones, those the mannequin most must be taught from.
There are two sensible fixes:
-
MSE warmup. Practice with plain MSE first, ignoring the head. As soon as is fairly correct, change to NLL. Now has a significant sign to be taught from, and the shortcut of inflating is much less tempting as a result of the predictions aren’t that unhealthy anymore.
-
-NLL. Multiply every pattern’s loss by a indifferent issue of .
This reweights gradients so laborious examples preserve contributing even when is giant. At you get customary NLL; at the weighting precisely cancels the impact. In apply is an effective default.
The important thing lesson: a loss operate can have a mathematically right optimum and nonetheless be tough to optimize in apply. Proving that tells you what the mannequin ought to be taught. It doesn’t assure that gradient descent will get there.
···
The place the pocket book picks up
All the things above is the derivation. Now the query we parked: does this really occur once you practice an actual mannequin?
The companion pocket book builds two transformers with the identical spine, on the identical artificial sign. The sign is designed in order that its noise degree adjustments over time, quiet stretches and noisy stretches, and no person tells both mannequin the place the boundaries are.
-
Mannequin 1: educated with MSE. Outputs one quantity per timestep.
-
Model2: educated with Gaussian NLL. Outputs and .
On plain level accuracy, they end almost comparable. We already predicted this: NLL and MSE agree on the optimum , so including would not damage level predictions. On this metric alone, you’d name them interchangeable. However they don’t seem to be. Break up the check set into quiet and noisy regimes. Ask every mannequin to attract a 90% prediction interval, a band that ought to include the true worth 90% of the time. For the level mannequin, the one choice is one fastened band width computed from the worldwide residual variance. For the probabilistic mannequin, every timestep has its personal , so the band is .
|
Quiet regime |
Noisy regime |
|
|---|---|---|
|
Level mannequin (fastened band) |
|
|
|
Probabilistic mannequin (discovered ) |
|
|
The purpose mannequin overshoots the 90% goal when issues are calm (the fastened band is just too vast) and catastrophically undershoots when issues are noisy (the band is way too slim). One in three values that needs to be contained in the interval falls outdoors. The probabilistic mannequin stays roughly sincere in each regimes, as a result of its band really tracks the native noise. Proper on common, fallacious the place it issues. That is the entire argument in a single desk.
The pocket book additionally closes the circle on the brink query from the opening. Given a threshold, the purpose predictor can solely say sure or no. The probabilistic mannequin returns an actual likelihood, the amount a choice really wants. And there’s a plot of the anticipated widening and narrowing with the true noise. The mannequin discovered that from the information, as a result of the loss gave it a cause to.
···
Conclusion
MSE isn’t a foul loss operate. It does a very good job of studying the heart of the goal distribution. Nevertheless it says nothing in regards to the uncertainty. by no means seems within the MSE formulation. If the loss by no means sees uncertainty, it can’t be taught it or consider it. That’s, coaching with MSE implicitly assumes that the identical quantity of uncertainty applies in every single place, an assumption that’s hardly ever true in real-world information.
Gaussian NLL fixes this by letting the mannequin predict each and . The loss has two competing components: one encourages the mannequin to elucidate the info precisely, the opposite discourages it from claiming pointless uncertainty. Collectively, these forces drive the mannequin towards the true conditional variance. By means of the KL divergence connection, this goal is not a handy heuristic, it minimizes the information-theoretic hole between the mannequin’s distribution and actuality’s. With one further output neuron and a easy clamp, the mannequin learns each the imply and the uncertainty in a single coaching run.
Two necessary classes to hold ahead:
-
First, predicted uncertainty is simply as dependable because the optimization course of that produced it. Despite the fact that Gaussian NLL has an accurate optimum, coaching would not all the time attain it. The weighting creates a shortcut that may entice early studying. Sensible strategies, equivalent to MSE warmup and -NLL, make the trail to the optimum extra dependable.
-
Second, the Gaussian continues to be an assumption. Predicting provides the mannequin an input-dependent measure of uncertainty, however the predicted distribution stays unimodal (one peak) and symmetric (equal likelihood above and under the imply). Some issues do not match this form. Think about a ball balanced on a ridge: it may roll left or proper, and the imply (the ridge high) is the one place it will not keep. Information with a number of potential futures, sudden regime adjustments, or heavy tails requires richer predictive distributions than a single Gaussian can present.
That’s the place extra expressive approaches, equivalent to quantized-token fashions and movement matching, turn into helpful, and the place the following a part of this collection begins. Till then, suppose again to the query we began with: Ought to I fear about this prediction? A mannequin educated solely with MSE has no significant method to reply. A probabilistic mannequin educated with Gaussian NLL lastly can.
···
References
[1] D. A. Nix and A. S. Weigend, Estimating the imply and variance of the goal likelihood distribution, Proc. IEEE Worldwide Convention on Neural Networks, 1994.
[2] A. Kendall and Y. Gal, What Uncertainties Do We Want in Bayesian Deep Studying for Laptop Imaginative and prescient?, Advances in Neural Data Processing Methods (NeurIPS), 2017.
[3] T. Gneiting and M. Katzfuss, Probabilistic Forecasting, Annual Evaluate of Statistics and Its Software, 2014.
[4] M. Seitzer, A. Tesch, N. Rasiwasia, and G. Martius, On the Pitfalls of Heteroscedastic Uncertainty Estimation with Probabilistic Neural Networks, ICLR 2022.